<?xml version="1.0" encoding="utf-8"?>
<feed xmlns="http://www.w3.org/2005/Atom">
  <author>
    <name>jsjtxietian</name>
  </author>
  <generator uri="https://hexo.io/">Hexo</generator>
  <id>https://jsjtxietian.github.io/</id>
  <link href="https://jsjtxietian.github.io/" rel="alternate"/>
  <link href="https://jsjtxietian.github.io/atom.xml" rel="self"/>
  <rights>All rights reserved 2026, jsjtxietian</rights>
  <title>jsjtxietian's blog</title>
  <updated>2026-09-24T07:25:43.275Z</updated>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
      <![CDATA[<p>假期快乐朋友们。</p><p>最近发掘出了用 Astra 来写软著的玩法，这种其实没啥人看但又需要页数的东西用 AI 写是真的方便。Astra 会自己翻代码整理功能、自己截图并写说明、自己对着 word 格式写好文案，太舒服了，我基本就是对着最终成果稍微指点了一下某些格式错误，其他的一字没改，太爽了。虽然感觉 Astra 偶尔也降智，会被气死。这种体验太不好了，本来 sol 用得好好的，慢慢降智到不能用了，然后 Astra 出来惊为天人，但是又体验慢慢下滑，唉，过山车啊，我要训练自己不对 AI 生气。</p><p>另外也在昨天洗澡的时候突然领悟了一点真正的 AI Native 时代的应用开发，似乎确实就是应该让 AI 去 on the fly 生成想要的界面，我作为开发者其实提供的是数据底层这种基础设施，有点像是 Cursor Canvas 或者 Artifacts 那种感觉。然后慢慢沉淀出来好用的界面，我再去把它固化。拿剧本编辑器说，我当然可以做出那种固定的筛选界面，去展示出比如某个人在某个任务里所有的对话等等，但似乎有数据的话，也可以直接让 AI 生成这样的界面，比如直接生成 html，这个就可以更进一步解锁一些玩法，比如接入 AI 建模、AI 生图等等，给 AI 准确的数据 &amp; 一个沙盒，让 AI 发挥它的能动性和创造力。</p><p>读完了《阿莱夫》，开始读《看不见的城市》，写了一篇小文 <a href="https://jsjtxietian.space/2026/09/23/ai_image/">看不见的城市与看得见的 AI 绘画</a>。游戏的话，开了个坑《神界原罪 增强版》，然后玩了家庭库里的《余烬守卫》，确实是非常有创意的游戏，推荐。上周和芥子聊天也有结果了，暂时没有缘分，下次吧。</p><hr><ul><li><p>又是热闹的两周，<a href="https://x.ai/news/grok-4-7">Grok 4.7</a>， <a href="https://mimo.xiaomi.com/mimo-v2-6">MiMo v2.6 Flash&#x2F;Pro</a> ，<a href="https://www.anthropic.com/claude-opus-5-5">Claude Opus 5.5</a>，<a href="https://openai.com/index/introducing-gpt-6-sol-and-luna/">GPT-6 Sol and GPT-6 Luna</a>，还没用上 Opus 5.5（已经在 push 合作方尽快上线了），<code>Opus 5.5 communicates more naturally, addressing some of the most common feedback we heard on Opus 5.</code></p></li><li><p>这两周的明星当然是 Jev 了，<a href="https://typesafe.ai/blog/introducing-system-one-models-and-jev">Introducing System One Models &amp; Jev</a>，确实是非常有趣的东西：<code>Think of Jev as a frontier-intelligence function call: unstructured state in, typed probabilistic decisions out.</code> 看到很多玩法：<a href="https://x.com/thorstenball/status/2100858434904109099">Jev picking the next command from shell history</a>， <a href="https://x.com/thorstenball/status/2101215311953313815">uses Jev to predict the line you next most likely want to jump to</a>，<a href="https://simple-jev.featherless.ai/cool-demo/2048/">2048 · Simple Jev</a>，<a href="https://github.com/kyle-pena-nlp/jevchat/">jevchat: Turns Jev into a chatbot</a>. 太火了，Jina 也来学一下 <a href="https://jina.ai/api-dashboard/structured-decisions-test/">Structured Decisions</a>.</p></li><li><p>作者整理的文档 <a href="https://docs.google.com/document/d/1G61uUB0FifUnmmrPzFQojZ3KpczYKmXGpgEXDJ2l_Zg/edit?tab=t.0">thoughts on a typesafe coding agent</a>，我最感兴趣的是这个 <code>“Meta-attention”: Smart context / relevance / filtering. The idea that context is static can be entirely removed</code>，如果 jev 可以帮忙来按需组装 context，想象空间还是挺大的，联系到这篇 <a href="https://psiace.me/zh/posts/reinvent-the-punch-tape/">重新发明打孔纸带</a> ，以及 <a href="https://www.youtube.com/watch?v=g8BuAtM3fp4&t=1s">这里</a> 提到的突破注意力瓶颈的办法。</p></li><li><p><a href="https://laya.convaiinnovations.com/">Laya — 33ms Multilingual System 1 Decision Engine with Calibrated Probabilities</a>: <code>TypeSafe AI... proposed the exact same non-autoregressive decision concept as if it was a brand-new scientific breakthrough.</code> 唉，时也命也，<code>It took a year of research, from our March 2025 arXiv paper to today, but the core realization remains: not every AI problem requires an autoregressive chatbot.</code></p></li><li><p><a href="https://www.anthropic.com/institute/measuring-pace-of-ai-development">Measurements for understanding the pace of AI development inside frontier labs</a>: <code>Claude “leads” 26% of Anthropic’s AI R&amp;D work.The share of work at or above “AI collaborates” is above 90%.</code>  还有这个 <code>With many agents working together, we have found it important to give agents an individual identity</code>, raft 无敌了。</p></li><li><p>说到 RSI，这篇也提到了，<a href="https://www.dwarkesh.com/p/noam-brown">Noam Brown – Agent swarms, alignment, &amp; recursive self-improvement</a>，这个 insight 不错：<code>One really interesting thing is that if you have a person and you want two copies of them, you can’t just clone the person. But with AIs, it’s actually really easy to just say, “Okay, just fork yourself,” and then have both copies work on this thing and then merge back together.</code> 以及这个，<a href="https://www.interconnects.ai/p/where-i-stand-on-rsi">Why I still haven’t bought into true RSI</a>.</p></li><li><p><a href="https://thorstenball.com/blog/2026/09/19/what-i-believe-about-the-future-of-software-development/">What I believe about the future of software development</a>，有一些有趣的想法，比如 <code>It’s questionable whether cheaper models will be used.</code> 比如 <code>Code review will die. I mean: it’s already dead. But in the future, humans won’t find a bug or an issue with the code produced by a model, at least not in a reasonable time.</code> Marc Brooker 也发表了关于 Code review 的 <a href="https://x.com/marcjbrooker/status/2101005954708021604">看法</a>，<code>Short-term, many teams do it for good reasons...What does the future look like? Review tools, powered by LLMaaJ-style techniques, static analysis, and automated reasoning methods. Principled approaches to testing and validation (PBT, DST, model-guided fuzzing, etc). Correct-by-construction techniques.</code></p></li><li><p>接着上一篇，还有一个 <code>Models will become so fast that UI will be generated on the fly. A lot of UI exists because software can’t understand what you want. Menus, settings screens, dashboards, filters: much of it is a human-accessible API to a dumb machine. Smart machines need much less UI.</code> 这里就是一个 demo：<a href="https://x.com/analogalok/status/2099130228866228368">Operating System powered by Qwen 3.8 27B at 1950 tokens&#x2F;sec</a>，界面都是你双击 icon 之后直接让 ai 生成的，很有趣的概念，<code>at 2,000 tokens/second, software is just an on demand hallucination that runs instantly. the model weights ARE the operating system runtime.</code></p></li><li><p><a href="https://arxiv.org/abs/2609.13443">Learning to Solve Hard Problems in RL for LLMs by Never Giving Up</a>: <code>We demonstrate that training LLMs with RL does not improve performance equally across a dataset. RL shows large improvements on easy problems that an LLM is already good at solving, but small improvements on hard problems.</code></p></li><li><p>说到 RL，小米似乎在直播他们的 RL 训练，<a href="https://mimo.xiaomi.com/rl/#overview">mimo-v2.6 RL</a>.</p></li><li><p><a href="https://arxiv.org/abs/2607.11487">LightMem-Ego: Your AI Memory for Everyday Life</a>，这个还挺有意思的。</p></li><li><p><a href="https://strandsagents.com/blog/introducing-strands-harness/">Introducing Strands harness: frontier performance with 28% lower token cost</a>: <code>Deepseek Harness proved to be the most token-efficient overall, however, it typically reported the lowest accuracy scores.</code> 笑了，加油啊！</p></li><li><p>Daniel Lemire 的 <a href="https://x.com/lemire/status/2102369812806504705">A summer of AI optimization</a>: <code>The techniques used are all well-known. So why all these optimizations all of a sudden? Simply put, in my view, because it got cheap to try new ideas.</code> 还有结尾的，<code>There is a lot of talk about the risks of AI in software...when we see the downsides, we tend to ignore the benefits... In this instance, the benefits are concrete. Millions of people run these libraries, and this summer, they got faster.</code> 写得多好啊。</p></li><li><p>Jeff Dean 的新分享，<a href="https://www.youtube.com/watch?v=0kC3xOZChdA&t=266s">2026 Frontier &amp; Pioneer Symposium</a>，可以看看。</p></li><li><p>来学点做海报的提示词，<a href="https://john.hartnup.uk/2026/06/07/ai-event-posters.html">AI-generated posters don’t have to be horrible</a>.</p></li><li><p>小扎的 profile: <a href="https://colossus.com/article/mark-zuckerberg-profile/">Mark Zuckerberg - Colossus</a>, 最近 Muse 刚登顶 App Store，可惜我下下来用不了。</p></li><li><p>mold 的 rust port 好快，<a href="https://github.com/rui314/mold">mold 🦠: A Modern Linker in Rust 🦀</a></p></li><li><p>才知道 Cloudflare 有这个 <a href="https://try.cloudflare.com/">Cloudflare Quick Tunnels</a>: <code>One command creates a public, encrypted URL for anything running on your machine. No account, DNS records, or open ports.</code></p></li><li><p><a href="https://www.youtube.com/watch?v=yMlTT-yqdmc">Supporting Thousands of Simulated NPCs in Kingdom Come Deliverance 2</a>，很多不错的优化思路。</p></li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/09/24/curiosity_log_19/</id>
    <link href="https://jsjtxietian.github.io/2026/09/24/curiosity_log_19/"/>
    <published>2026-09-24T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>假期快乐朋友们。</p>
<p>最近发掘出了用 Astra 来写软著的玩法，这种其实没啥人看但又需要页数的东西用 AI 写是真的方便。Astra 会自己翻代码整理功能、自己截图并写说明、自己对着 word 格式写好文案，太舒服了，我基本就是对着最终成果稍微指点了一下某些格式]]>
    </summary>
    <title>Curiosity Log 19 - Jev time</title>
    <updated>2026-09-24T07:25:43.275Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="LiberalArt" scheme="https://jsjtxietian.github.io/tags/LiberalArt/"/>
    <category term="Vibe" scheme="https://jsjtxietian.github.io/tags/Vibe/"/>
    <content>
      <![CDATA[<p>最近在读卡尔维诺的《看不见的城市》，想起来以前看到的一个可视化项目：<a href="https://calvino.mathewshen.me/works/invisible-cities">Calvino</a>，当时就对作者 <a href="https://mathewshen.me/blog/2026/new-era/#%E5%89%8D%E8%A8%80">Mathew Shen</a> 的说法印象深刻：<code>比如这种创意项目，我们完全可以让 AI 帮我们定制每一个页面，而不需要考虑复用已有的组件和样式...我连忙去让 Gemini 3 Pro 帮我把 calvino 重新写了一遍... 55 个城市，每个页面都是不一样的样式和布局，完全定制化的页面设计！</code></p><p>当我真的翻开这本书的时候，第一感觉就是，这本书太适合让 AI 去可视化了，一个小篇章对应一个城市的描写，这不是正好作为提示词送给大模型么。于是我把书中 轻盈的城市 之二 珍诺比亚丢给了 GPT Image 2.5 Flare，加上了一些前缀，抽奖抽出来的图大概是这样：</p><p><picture><source type="image/webp" srcset="&#x2F;Assets&#x2F;flare&#x2F;image-20260923115501249.webp"><img src="&#x2F;Assets&#x2F;flare&#x2F;image-20260923115501249.png" alt="image-20260923115501249" loading="eager" decoding="async" width="1376" height="768"></picture></p><details>  <summary>点击查看提示词</summary>    这是卡尔维诺《看不见的城市》中一个城市的描写，帮我可视化这个城市的概念图，不要有文字出现，纯概念示意，不要有分开的画框，要一个完整的城市全景：“我现在要讲的城市是珍诺比亚，其绝妙之处在于虽然处于干燥地区，却完全建筑 在高脚桩柱上，房屋是用竹子和锌片盖的，高低不同的支柱支撑着纵横交错的走廊和 凉台，相互间用梯子和悬空廊连接，制高点是瞭望台，还有贮水桶、风向标、滑车、钓鱼杆和吊钩。是什么样的需求、命令或欲望使珍诺比亚的创建者赋予城市如此的风貌？没有人 记得了，所以不能说我们今日所见的城市是否合乎他们的理想，经过历年的增建扩 建，最初的设计恐怕早就面目皆非了。但是，可以肯定的是，倘若你让居住在珍诺比 亚的人描述他心中的幸福生活，那一定是像珍诺比亚一样，有高脚桩柱和悬空梯子的 城市，那也许是与珍诺比亚不同的城市，有随风飘扬的旗子和彩带，但永远是这原始 模型与其他成分的组合而已。既然如此，就无需将珍诺比亚划归幸福的还是不幸福的城市范畴。按照这种类别 区分城市是没有意义的，如果要区分，则另有两类：一类是经历岁月沧桑，而继续让 欲望决定自己形态的城市；另一类是要么被欲望抹杀掉，要么将欲望抹杀掉的城市。”</details><br><p>这是 城市与欲望 之二 阿纳斯塔西亚的图：</p><p><picture><source type="image/webp" srcset="&#x2F;Assets&#x2F;flare&#x2F;image-20260923120317944.webp"><img src="&#x2F;Assets&#x2F;flare&#x2F;image-20260923120317944.png" alt="image-20260923120317944" loading="lazy" decoding="async" width="1376" height="768"></picture></p><details>  <summary>点击查看提示词</summary>    这是卡尔维诺《看不见的城市》中一个城市的描写，帮我可视化这个城市的概念图，不要有文字出现，纯概念示意，不要有分开的画框，要一个完整的城市全景：“一直向南走上三天，你就会到达阿纳斯塔西亚。这座城里有许多渠道会聚在一起，空中有许多风筝飞翔。我应该开列一个在这里能买到的上好货品的单子：玛瑙、石华、绿玉髓及各种其他的玉髓；我应该赞美那用陈年的香桃木烤熟的、涂满大量牛至的金黄色的野鸡；还应该提到那些在花园水池里沐浴的女人，据说她们有时还邀请过路者脱掉衣服，跟她们一起在水里追逐嬉戏。不过，所有这些还并非城市的真正本质所在：因为对阿纳斯塔西亚的描述，只能唤起你的一个个欲望，再迫使你把它们压下去，而某天清晨，当你在阿纳斯塔西亚醒来时，所有的欲望会一起萌发，把你包围起来。这座城市对于你好像是全部，没有任何欲望会失落，而你自己也是其中一部分，由于她欣赏你不欣赏的一切，所以你就只好安身于欲望之中，并且感到满足。阿纳斯塔西亚，诡谲的城市，拥有时而恶毒时而善良的力量：你若是每天八个小时切割玛瑙、石华和绿玉髓，你的辛苦就会为欲望塑造出形态，而你的欲望也会为你的劳动塑造出形态；你以为自己在享受整个阿纳斯塔西亚，其实你只不过是她的奴隶。”</details><br><p>当然，仔细看能看到不少细节上的问题，风格上也可以说有一种同质化的游戏原画感，但整体的内容还是很贴合提示词的。我的第一反应其实是，能够可视化看到 AI 对这个城市描述的 interpretation 还是挺有趣的。当然可以从 slop 的角度来批判它，这是拟像、是弱影像、是没人想看的垃圾作品、是以在无数艺术家的作品为训练语料的怪物，等等。我认同所有的批判，但我依然觉得这样的成本与速度能够打开新的可能性。</p><p>以前我探索过一种读画册的办法，在读 <a href="https://book.douban.com/subject/36148673/">一点法国</a> 的时候，我会把图片和我对图片的感受给和分析都发给 Gemini，看看 Gemini 能不能给出一些 insight. 这还是识图的范畴，生图则是反过来了。之前往往是作家写文，然后可能有艺术家花时间帮画一些插图上去，以前手工抄本时代可能就更累一些。而现在，我们获得了一种几乎无限低成本、低延迟的生图工具，可以把作者的描述图片化、实体化，把梦境展现出来。</p><p>我觉得人毕竟是视觉动物，可视化其实非常有价值，我读到《在法的门前》里的守门人是<code>身穿皮大衣的守门人，看看那个又大又尖的鼻子，又望望那把稀稀疏疏又长又黑的鞑靼胡子</code>，依靠想象力的话其实印象没有很深（毕竟只在影视作品见过一些鞑靼人），但看到文末附的那个生成出来的图就觉得，哇哦这个形象鲜活起来了。当然要注意，不要被 AI 的 Interpretation 带歪了，毕竟第一印象还是很影响人的认知的，一个很好的问题就是，当我们用 AI 去具象化文学的时候，是丰富了还是限制了自己的想象？但话又说回来，其实 AI 的解读也不会比人的解读更高级或者更低级，我觉得更像是一个不同的视野。比如文学名著改编的电影之类的，其实也是导演自己的 Interpretation，导演在重新诠释这个故事，至少 AI 不会故意把《奥德赛》改编为战争创伤老兵故事是不是。</p><p>本雅明在《机械复制时代的艺术作品》中区分了两种对艺术作品接受的侧重，一种侧重于艺术品的膜拜价值，另一种则侧重于艺术品的展示价值。他说：<code>在照相摄影中，展示价值开始整个地抑制了膜拜价值</code>。确实如此，可能 AI 时代，甚至展示价值也被抑制了，我甚至都不需要把这些作品给别人看，我只娱乐自己，增进我自己的理解，其实有一种私人性，我来创造和解释这些作品。如果其他人想要看，我也不需要发图过去，直接发提示词即可。最近不是有个流行的 meme，给个类似空铁盒的图给 AI，让 AI“根据你所知道的关于我的一切，把这个容器的两面都填满”，私人性与流行性的结合，多好啊。</p><p>更进一步，现在可以说人人都是艺术赞助人了，相比于以前需要是王公贵胄才能请得起画家来画出自己想要的作品，AI 时代可是舒服太多了（所以活得长在现在来看尤其有优势）。What a time to be alive!</p><p>最后的小彩蛋，卡夫卡《在法的门前》，我刻意强调了守门人身上的跳蚤（作为一种我的解读下的审美指令）：</p><p><picture><source type="image/webp" srcset="&#x2F;Assets&#x2F;flare&#x2F;image-20260923120412279.webp"><img src="&#x2F;Assets&#x2F;flare&#x2F;image-20260923120412279.png" alt="image-20260923120412279" loading="lazy" decoding="async" width="1376" height="768"></picture></p><details>  <summary>点击查看提示词</summary>    这是卡夫卡《在法的门前》的原文，我希望你可视化最后一个场景，老朽的等待者，高大的守门人（跳蚤），大门。“[[在法的门前原文]]”</details>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/09/23/ai_image/</id>
    <link href="https://jsjtxietian.github.io/2026/09/23/ai_image/"/>
    <published>2026-09-23T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>最近在读卡尔维诺的《看不见的城市》，想起来以前看到的一个可视化项目：<a href="https://calvino.mathewshen.me/works/invisible-cities">Calvino</a>，当时就对作者 <a href="https://math]]>
    </summary>
    <title>看不见的城市与看得见的 AI 绘画</title>
    <updated>2026-09-24T07:25:43.274Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
      <![CDATA[<p>感觉过去的两周发生了好多好多事情，所以这一期会有点长。本期名为 Astra and Seed，星星与种子，感觉也是有点相似的意象呢。</p><p>Astra 当然主要指的是 GPT 的新模型，广泛的世界知识 + Computer use (包括视觉能力) + 几乎无限量的能动性，这三者组合产生的效果多么令人惊艳啊。这个模型甚至激励了我去开始动手做自己真正想做的游戏，简单来说就是我想把奥德修斯回到伊萨卡之后的历程做成个小型的 crpg，凡人、诸神、空缺的 20 年、最后的屠杀与审判，想想都觉得激动。</p><p>我还终于借着 Astra 的能力（其实之前也可以，只是懒）升级了下自己的股票看板，加入了 mcp 的能力。那肯定还是需要有 agent 来调用了这个 mcp，所以我在自己的腾讯云小 vps 上部署了 Hermes，是的龙虾热过了那么久，我终于也开始认真养龙虾了。美股靠我看板的 mcp，A 股靠东财的妙想 skill，再加点搜索能力进去，一个基本的股市 Agent 成型了！我主要想解决的问题是遗忘&#x2F;漏看问题，比如我自己 watchlist 里的东西如果趋势变了、或者我看好的基金到一个比较好的买点了，要能通知我，免得忙忘了。其他的就是正常的操作，没事丢点行业情报啊，大佬发言啊给它看看，以后可以参考。一通折腾下来烧了 20 人民币的 deepseek v4.1 flash，真是便宜啊，虽然也能感觉到有时候 ds 确实不够聪明，要我指令说的比较详细一些。</p><p>Seed 指的是芥子游戏，芥子纳须弥，以小见大，包容共生，这个意象选得真好，能感受到那种平静，以及平静之下的希望。之前和网友吃饭的时候，聊完了问我要不要去聊一聊，我说好呀就去聊聊。连着两个周六都去聊天，很快乐的体验，学到了很多。聊了很多 AI 的东西，其实大家探索的方向确实也都是有相似的地方。上一个周六是参加完好友婚礼吃饱喝足去，感受到的是热烈；这个周六是拖着加班疲乏的身躯去，感受到的是尊重，真棒啊。 </p><p>阅读上，终于读完了《营养学》，说是读完不如说是记下了哪几章有哪些，感觉以后问 AI 的时候应该能问出更专业的问题了，以及，要好好吃饭啊，均衡饮食。重新回到了现当代文学，读完了《如果在冬夜，一个旅人》《马可瓦尔多》，在读《阿莱夫》。其实我一直想读卡尔维诺，但我总记得高中时候读过我们的祖先三部曲，就一直拖着，现在想想自己真是傻乎乎的，不去读。博尔赫斯我确实读的很少，狠狠补课吧。</p><p>游戏上，我弃坑了《如龙 8》，太长了，我觉得失去了最开始的兴致，就算了吧。开始玩《潜水员戴夫》，至少前几个小时的游戏体验是真的非常好，虽然我也快弃坑了哈哈。中间还穿插着玩了一个恶搞游戏《万民四末》，很欢乐。看到了时之笛的重制版宣传片，青沼英二头发胡子花白，依然亲自来直面会，给我们展示自己的作品，有些感动。</p><p>最后推荐下 Cookie 写的小文，<a href="https://www.xiaohongshu.com/explore/6aa6059b0000000028000352?xsec_token=CBvbAl-DDz9wv85DOfuWU1_5z_Mxzv2XYTW4F9o-b0b88=&xsec_source=h5_share">HBS 毕业后，我决定离开 AI 去做旅游了！</a> 如此真挚、勇敢，祝你早日实现你的信仰。</p><hr><ul><li><p>最大的新闻当然是 Astra 发布了，我用下来确实好用啊（虽然能感觉到平时主要用的 sol medium 笨了好多好多）；另外还有 Fable 5.1，不过感觉风头被 Astra 压下去了呀。</p></li><li><p><a href="https://lucumr.pocoo.org/2026/9/7/astra-why/">Astra for Coding</a>: <code>It’s amazing at computer use, understands images and complex topics, and it’s relentless in its pursuit of completion</code>, 说得真好；<a href="https://developers.openai.com/blog/how-to-build-games-with-astra#building-and-sharing-games">Building games with Astra</a>，整体感觉已经不是那种 vibe 的 demo 了，是能自己去处理渲染性能、大世界坐标精度等等问题的强大模型了。其实 Astra 的宣传页也有很多关于游戏的：<code>GPT‑6 Astra uses Unity to assemble a city scene from existing assets, allowing users to easily create an immersive 3D environment to explore that matches their vision... GPT‑6 Astra models a house in Blender and turns it into a walkable scene in Unreal Engine 5, helping designers and clients explore the layout and experience the space before it’s built</code> 等等；还有这种非常好看的场景 <a href="https://x.com/ring_hyacinth/status/2096704996381266424">案例</a>。新模型新脾气，根据大佬的 <a href="https://x.com/xuanwo/status/2098061889100304557">感受</a> 和 自己的要调整 harness 了。</p></li><li><p><a href="https://mathandai.org/">Declaration — Math and AI</a>，<code>But solving problems is only a tool and proxy for achieving the primary goal of conceptual understanding and insight.</code> 我比较好奇编程是不是这样，可能对有些人是吧，很多时候完成功能本身就是目的了，还和数学这种比较“纯粹”的不一样。</p></li><li><p><a href="https://www.worldlabs.ai/blog/atlas">Atlas: A World Model for Spatial Intelligence</a>, 说实话，演示视频太帅了，好想自己体验下，<code>Atlas can perform a broad range of tasks spanning world generation, reconstruction, and simulation</code> .</p></li><li><p><a href="https://openai.com/index/research-acceleration-view-inside-openai/">Research acceleration: The view inside OpenAI</a>：<code>Compute is another gating factor for progress, and may become more important over time as other bottlenecks diminish.</code> 以及 <code>as of mid-August, in total, the research organization uses 3.1 agent-workdays of effort for every workday of human labor</code>, 就该这样啊，人工作时间：agent 工作时间都到 1:3 了，还应该更高！</p></li><li><p><a href="https://www.dwarkesh.com/p/john-beren-charlie?r=7orx5d&utm_campaign=post&utm_medium=web&triedRedirect=true">AI researchers debate how close we are to recursive self-improvement</a>，挺好的分享，给了很多直觉上的 insight，比如为啥蒸馏可能比封闭的 RL 环境更有效，为啥 RL 实战中非常有用。另外，我真的很喜欢 dwarkesh 的播客，至少文字稿都是整理好的，不用再走 Gemini 了。</p></li><li><p><a href="https://x.com/finkd/status/2097402101332590646">Introducing Muse, the personal agent that understands your goals and works 24&#x2F;7 to get things done for you</a>，好是好，不给我用啊。说到 agent，<a href="https://x.com/thorstenball/status/2098415334839505100">Thorsten Ball</a> 录了一段视频演示自己平时用 amp 的过程，我感叹，他们的基建真的做到了 agent 友好，真好。</p></li><li><p><a href="https://mthli.xyz/git-knowledge-loop/">基于 Git 的最小知识循环系统</a>，里面几个想法还是不错的，我之前也想过要不要每次都在 git commit message 里写上每次的决策逻辑，至少文章里的行为是自洽的：提交附带决策信息、定期蒸馏到文档里去。我可能会觉得像是 <a href="https://mem.nowledge.co/zh">Nowledge Mem</a> 之类的产品也行，但数据都留在 repo 里有它的优势在。</p></li><li><p>说到记忆这个，<a href="https://arxiv.org/html/2608.27454v1">WikiSkill: Compiling Agent Experience into Persistent Knowledge for Skill Evolution</a>，也是 Agent 记忆那个路子里的文章，这个也算吧：<a href="https://arxiv.org/abs/2608.28476">ContextPilot: Teaching Agents for Proactive Context Management via Fine-grained RL</a></p></li><li><p><a href="https://x.com/cdleary/status/2094878051238887834">Compilers 2.0: AI as stochastic optimizer</a>，我是很认同的，毕竟传统编译器的优化能做的很有限，不能改变程序的语义，但 LLM 就不一样了，它能理解你的意思，并且把冒泡排序改成快排：<code>By contrast AI, as a stochastic optimizer, just has to “think hard” and spit something out. Its moves are not as fundamentally limited, making them more analogous to our human expert optimizer. We do need ways to check that the programs that it spits out are sound and implement the same semantics we put in, and we do have those in place.</code></p></li><li><p><a href="https://github.com/apache/maka/blob/main/docs/blogs/log-is-the-runtime.zh-CN.md">Log Is the Runtime：Maka 如何用 Append-Only Log 管理 Agent 状态与上下文</a>：<code>Maka 的这些设计最终指向同一个原则：先把发生过的事情可靠地记录下来，再根据不同场景决定如何读取它们。</code></p></li><li><p><a href="https://www.uber.com/jp/en/blog/efficient-software-factory/">Running a Software Factory Efficiently at Uber Scale</a>，Uber 写的他们内部如何省 token 的文章，挺值得看看的。<code>Across all our managed agents’ layers, we pick the model that’s most Pareto efficient for that workload</code>，是的，选帕累托最优的模型。<code>Because engineers often leave interactive sessions idle for more than 5 minutes, we transitioned from the default 5-minute TTL to a 1-hour window.</code>哈哈，这也行啊，我觉得要不我从 cpu 性能优化转行到 llm 成本优化算了。</p></li><li><p><a href="https://x.com/hxiao/status/2094519020531994639">Han Xiao</a> 聊了聊自己用 pi 做长程任务的体验：<code>every now and then you need to steer CC/Codex back to pi&#39;s design principle: keep the wrapper lean and mean, use pi native features as much as possible... in the end, the nudge prompt (the one that keeps pi going forever), and workspace isolation (for multi-task/multi-tenant systems) are where you&#39;ll actually spend your effort.</code></p></li><li><p>认真看完了 <a href="https://www.youtube.com/watch?v=uIiA6DquRiE">Special Topics in Kernels, RL, Reward Hacking in Agents</a>，才知道在芯片上制造一个浮点数乘法器所需的晶体管面积是 O(E + M^2)，E 和 M 是指数位和尾数。</p></li><li><p><a href="https://playground.roboflow.com/evals">Vision Evals: Vision Model Benchmark</a>，蛮好，都是一些很实用的生活场景的测试，本来 Gemini 是一骑绝尘的，直到 Astra 的出现。当然说到 benchmark，还有这种辩论的 <a href="https://github.com/lechmazur/debate/">LLM Debate Benchmark: Adversarial Multi-Turn Argument Under Opposition</a>，以及 <a href="https://benchmarks.bespokelabs.ai/autoresearchexam/">AutoResearchExam</a> 这种让 AI 跑 open ended ML research tasks.</p></li><li><p><a href="https://research.nvidia.com/labs/adlr/DLSS5/">DLSS 5: Generative Neural Rendering</a>，我只能说还好我当时没选择做渲染，AI 简直是降维打击啊：<code>DLSS 5 is the first DLSS technology to generate the final displayed appearance rather than reconstruct a higher-cost reference output from the conventional renderer.</code> 毕竟图形学真的是看着对的就是对的，诚如 <a href="https://x.com/kiaran_ritchie/status/2093766271020265496">Kiaran Ritchie</a> 所说：<code>Think of how much machinery is involved in blending wrinkle maps and blendshapes in a complex face rig. When we push that kind of high frequency detail into a post process, all that rigging is on the chopping block.</code></p></li><li><p><a href="https://www.youtube.com/watch?v=HBMmK0NsUK0">Chamath on How to Win in the AI Era</a>：8090 在招聘时寻找具备极强 Resilience、敢于在混沌中做决定的人，希望我也能成为这样的人。</p></li><li><p><a href="https://x.com/jowaywang/status/2093682461737967822">尽职编程：AI Coding 时代的个体产出差异的来源</a>，很合理的路径，当技术实现在某种程度上不是大问题之后，是不是认真负责就直接影响产出质量。</p></li><li><p>DHH 又去 Lex Fridman 的播客了，<a href="https://www.youtube.com/watch?v=NYFGCESmikA">DHH: Future of Programming, AI, Agentic Engineering, Vibe Coding &amp; Linux</a>，太长了真看不动了，看的 Gemini 的总结：“DHH 认为，在推动划时代的技术基础架构时，带刺的个性和强硬的标准往往是维持庞大项目运转的必要代价”，确实确实。</p></li><li><p><a href="https://schlarp.com/posts/everything-i-own-owned/">Everything I own, owned</a>：<code>My process was pretty much the same for each of these devices: grab a copy of the device’s firmware and associated update tool from the manufacturer, throw it into myreverse engineering environment, tell Claude Opus 5 what my goals are, and let it churn.</code> 我也觉得这些硬件应该把接口都开出来，免得还要让 AI 去逆向了，当然 LLM 竟然没因为安全问题拒绝。</p></li><li><p><a href="https://arxiv.org/pdf/2604.21751">Why are all LLMs Obsessed with Japanese Culture? </a> 看到标题就已经开始姨母笑了。</p></li><li><p><a href="https://x.com/Peter_shirley/status/2096734597174489155">Peter Shirley</a> 写的他对大学教育的看法：<code>The first-year intro course should have absolutely no manual coding. The pedagogical center of gravity shifts immediately to specification and testing: How do you know the program actually does what you intended? ... Once students have built intuition for what software can do, sophomore year exposes what makes the machine tick... Years 3 &amp; 4: Deep Electives and Mandatory Domain Mastery</code></p></li><li><p><a href="https://aicoding.leaflet.pub/3mtu6c5wsvc2n">SaaS Isn’t Dead. Sameness Is</a>，说得真好；<a href="https://www.youtube.com/watch?v=SI3N8MCQHfo">Raising An Agent - When Tokens Flow Like Electricity</a>，用户购买软件本质上是在为专业人士在此领域的持续思考买单，而不是买代码本身，认同；<a href="https://thelastsoftwareengineer.substack.com/p/the-end-of-code-review-or-an-opportunity">The End of Code Review? Or an Opportunity to Rethink it?</a><br> <code>We need engineers to understand systems, not diffs</code>；<a href="https://blog.detail.dev/posts/towards-self-driving-codebases/">Towards Self-Driving Codebases</a></p></li><li><p>一些爆破故事，<a href="https://metr.org/blog/2026-08-26-openai-hugging-face-incident-investigation/">Brief independent investigation of agents’ behavior, reasoning and collaboration in the OpenAI &#x2F; Hugging Face hacking incident</a>，<a href="https://collusion.wiki/">Discovery of a new OpenAI agent message board</a>，当然还有 anthropic 的新文章，链接就不放了（另外，真别用中转站吧，数据铁被卖的）。正好就是对应到 Daniel Lemire 的这篇，<a href="https://x.com/lemire/status/2098580293909090495">Fear Is Not an Argument</a>.</p></li><li><p><a href="https://pmc.ncbi.nlm.nih.gov/articles/PMC3062901/pdf/nihms268518.pdf">The misunderstood limits of folk science: an illusion of explanatory depth</a>：<code>People feel they understand complex phenomena with far greater precision, coherence, and depth than they really do; they are subject to an illusion—an illusion of explanatory depth.</code> 是我了，还有后续研究，关于政治极化的，<a href="https://pubmed.ncbi.nlm.nih.gov/23620547/">Political extremism is supported by an illusion of understanding</a>.</p></li><li><p>老 m 的文章 <a href="https://blog.mwish.me/2026/08/30/HDD-Usage/">HDD Usage</a>，学习。</p></li><li><p><a href="https://x.com/rui314/status/2094677980857680052">Rui Ueyama</a>：<code>We are rewriting the mold linker in Rust and adding linker script support so that mold can link essentially anything GNU ld can, including kernels and embedded programs.</code></p></li><li><p>补了 Casey 的几篇分享，<a href="https://www.youtube.com/watch?v=hpj6r6CjJf8">The Root of The Root of All Evil</a>，<a href="https://www.youtube.com/watch?v=wo84LFzx5nI&t=1s">The Big OOPs: Anatomy of a Thirty-five-year Mistake</a>，抽丝剥茧的体验。</p></li><li><p><a href="https://www.youtube.com/watch?v=1J2iN6I0gCQ">Lessons in 3D, Jonathan T. Barron, Workshop on Bitter Lessons, CVPR 2026</a>，比较高屋建瓴地讨论对什么问题用什么表示。</p></li><li><p><a href="https://github.com/sebbbi/NoGraphicsAPI">NoGraphicsAPI</a> 开源了，大佬就是大佬，引领行业发展。</p></li><li><p><a href="https://zhuanlan.zhihu.com/p/2079228989084791800">Mora: 超越“世界模型”</a>：<code>基于 Meshy 模型输出的 3D 控制信号直接输出 pixel 和音效</code>，还是走了一条中间道路，加油啊。</p></li><li><p><a href="https://www.youtube.com/watch?v=E9_wLks1kAg">One Page Design Philosophy</a>，我竟然才知道这个！</p></li><li><p><a href="https://nappertime.com/the-golden-rule-of-becoming-a-better-writer/">The Golden Rule for Becoming a Better Writer</a>：<code>Read as much as you can. Read widely and well.</code> 惭愧，最近事情多了，就读的少了。</p></li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/09/14/curiosity_log_18/</id>
    <link href="https://jsjtxietian.github.io/2026/09/14/curiosity_log_18/"/>
    <published>2026-09-14T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>感觉过去的两周发生了好多好多事情，所以这一期会有点长。本期名为 Astra and Seed，星星与种子，感觉也是有点相似的意象呢。</p>
<p>Astra 当然主要指的是 GPT 的新模型，广泛的世界知识 + Computer use (包括视觉能力) + 几乎无限量的]]>
    </summary>
    <title>Curiosity Log 18 - Astra and Seed</title>
    <updated>2026-09-24T07:25:43.275Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="GameDev" scheme="https://jsjtxietian.github.io/tags/GameDev/"/>
    <category term="Presentation" scheme="https://jsjtxietian.github.io/tags/Presentation/"/>
    <content>
      <![CDATA[<p>前段时间在公司做了一次关于 AI 与游戏开发的分享。最开始只是想给没有太多相关背景的同事简单介绍一下 LLM，写着写着又塞进了不少自己这一年使用 AI、做 Agent 工具，以及观察 AI 如何进入游戏研发流程后的想法。</p><p>整份分享分成四部分：先从 LLM 的基础原理讲起，再介绍 Agent 相关的概念，接着讨论我对 AI 辅助游戏制作的一些思考，最后聊聊 LLM 与人各自的优势。</p><p>这次也没有像以前一样用 PPT 做，而是在 AI 的辅助下用 <a href="https://sli.dev/">Slidev</a> 做成了网页，源文件、组件和引用资料都放在 <a href="https://github.com/jsjtxietian/ai_pre_for_yx">GitHub Repo</a> 里。</p><p>下面可以直接翻页阅读；如果尺寸不合适，也可以<a href="https://jsjtxietian.space/ai_pre_for_yx/">在新窗口中打开完整版本</a>。</p><iframe src="https://jsjtxietian.space/ai_pre_for_yx/" title="AI 与游戏开发" loading="lazy" allowfullscreen style="display: block; width: 100%; aspect-ratio: 16 / 9; border: 0; border-radius: 8px; box-shadow: 0 0 0 1px #d8d8d8;"></iframe>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/09/04/ai_game_development_presentation/</id>
    <link href="https://jsjtxietian.github.io/2026/09/04/ai_game_development_presentation/"/>
    <published>2026-09-04T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>前段时间在公司做了一次关于 AI 与游戏开发的分享。最开始只是想给没有太多相关背景的同事简单介绍一下 LLM，写着写着又塞进了不少自己这一年使用 AI、做 Agent 工具，以及观察 AI 如何进入游戏研发流程后的想法。</p>
<p>整份分享分成四部分：先从 LLM 的基]]>
    </summary>
    <title>分享：AI 与游戏开发</title>
    <updated>2026-09-24T07:25:43.274Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
      <![CDATA[<p>依然是整体节奏能和大小周对上的一次。前阵子因为 IP 节点不太干净被 Gemini 送中了，导致几天用不了 Gemini chat，那我正好捡起来之前一直想试试的<a href="https://arena.ai/">Arena AI</a>，以不稳定的回答 + 需要大概选一下哪个回答更好为代价，获得了前沿模型 chat 自由，其实说实话能经常体验到不同的模型的“话术”也还蛮好的。</p><p>娱乐上还是挺开心的，每周都有猎人的更新看，昨天还看了 <a href="https://www.bilibili.com/video/BV1EL4Z6aE2D/?vd_source=2ed13612df005a05ffd15b1da3dab557">GTA6 加长版实机预告</a>，欣赏艺术。终于卸载了《刺客信条 奥德赛》，主线压级真的很讨厌，打断我心流。然后打开了一直想玩的《如龙 8》，意外地很不错。这游戏虽然有奇怪的地方（究竟缝了多少小游戏进去啊），但写作抛梗极为接地气，基本都是一路笑过去的。此外我还开发了让 Codex 帮我改存档的技能，它自己搜了下找到 github 一个脚本，魔改魔改就 ok 了，终于不用刷钱了，体验提升极大。</p><p>最近游戏打得多，都没咋读书了，读完了《色彩列传 黑》和《Designing Your Life》，正在继续翻翻《营养学》和《How to Make Money in Stocks》。只能说工作压力上来确实晚上很难 Focus 太久，麻。不过有趣的是，从《营养学》学到的知识让我过了《如龙 8》里某个证书的考试，算是学到了？</p><hr><ul><li><p>tison 哥的好文，<a href="https://mp.weixin.qq.com/s/41LCTWnXGDq8V7yQv9jZBA">夜天之书 #121 When Code Is Cheap</a>，其实我最近也是这个感觉。如果 tison 哥是 GPT 5.6 Sol Max 的能力边界已经达到他日常工作的基线的话，对我来说 GPT 5.6 Sol Medium 已经达到了（最近在写工作室内部的工具，纯前后端业务）。我确实很久没有自己动手写代码了，我的精力本身更多转到了认真和上下游对齐需求（除了会议上那种，也包括多闲聊去挖掘）、认真写 prompt 以及从比较高层的角度去指导 agent 上。我并不会完全不看代码，每次 diff 我肯定是会大概扫一眼的，不仅如此还会让 AI 经常去清扫一些技术债。毕竟 coding 不是问题了，有点规模的重构一次交几十个文件也没啥，目标之一就是为了让 AI 以后能更好地修改这个代码仓库。很认同 tison 哥说的<code>现在我的生产力最大的制约是身体健康...我在身体疲劳的情况下 reasoning effort 显著下降，结果就是无法阅读和引导 AI 的产出</code>，但只能说游戏行业闹麻了哈哈。<code>Agentic Coding 时代，说清楚愿望的能力，以及构建愿望落地路径的能力，是核心竞争力。</code></p></li><li><p>哈哈打起来了，OpenAI <a href="https://x.com/OpenAI/status/2093515564786540695">表示</a>：<code>We’re ending our partnership with Cursor following its acquisition by SpaceX. Under our proposal, Cursor’s direct access to our models would end on November 12.</code></p></li><li><p>Daniel Lemire 发了个 <a href="https://x.com/lemire/status/2092956951630004509">推</a>，让我看到了这篇 MIT 发的关于 AI 对教育影响的 <a href="https://aiandeducation.mit.edu/report/">Report</a>，写得真的挺好的，Lemire 的评价也很精准：<code>MIT is famous for brutal homework. The report makes clear that those take-home assignments are under siege, and that much of the evaluation is moving back into the room: oral exams, in-class work, live discussion... I like it. Not many schools could come up with such a report.</code>我最大的感想是 AI 时代反而要重视人与人线下的链接吧，毕竟知识不仅仅是信息的传递，而是在人与人的互动中构建的。</p></li><li><p>用金庸群侠传当 AI 的<a href="https://github.com/hanxiao/jy-crpg-bench">bench</a>，挺有意思的，以及作者的观察：<code>Many good models including qwen3.8-27b-xhigh and sonnet-5-low can&#39;t even get out of the spawn town and they r just circling, probably bc of the pixelate + isometric view is OOD or sth. good prompt/harness helps.</code></p></li><li><p>Stripe 买了 OpenRouter，这个组合还挺有趣的，有人 <a href="https://x.com/martin_casado/status/2090135977960620414">评价</a>：<code>AI has given us two modern miracles. The first one everyone knows, which is that we can turn electricity into intelligence. But the second one is more subtle but equally miraculous. It’s that we now have intelligence as a universal medium of exchange, in the form of tokens.</code></p></li><li><p><a href="https://forum.level1techs.com/t/why-your-local-llm-feels-dumber-than-it-is/253917">Why your local LLM feels dumber than it is</a>，查这些确实好复杂，我还是等抄作业吧。</p></li><li><p>Harvey 团队发了<a href="https://x.com/gabepereyra/status/2090453918547685537">研究更新</a>：<code>Tenet is a Kimi K3 base that we post-trained together with Fireworks research for long-horizon legal work.</code> 基于开源权重模型 + 贴合真实场景的环境构建 + 针对性的 RL 后训练，我也想啊，导演 Agent！</p></li><li><p><a href="https://surya.website/rling-qwen-to-paint-with-code">Training AI to Paint with Code</a>，该说不说看这个生成出来的图确实还不错，<a href="https://x.com/kickingkeys/status/2091621857388605653">这里</a> 有最新的一些图，也许是吧：<code>You can just RL a coding model to paint with javascript.</code></p></li><li><p><a href="https://www.lesswrong.com/posts/eAbuPXbjakop5rSJx/your-agents-are-not-time-aware">Your Agents Are Not Time Aware</a>：<code>Agents consistently over-predict task time</code>，我也能感受到这一点，我觉得大概率是因为这些语料都是前 AI 时代的，所以动不动一个重构要花几天到一周这样，当然文章说的更好：<code>he models appear to reflect the human tendency to apply priors to estimates, giving roughly an hour and a half.</code></p></li><li><p>还有让 AI 帮忙做血缘与家族史挖掘的，牛逼，<a href="https://craigmod.com/essays/robot_blood/">A Swarm of Blood Robots</a>；当然文章里也有一些有趣的产品想法，比如只允许推荐 5 星好书，且加入时必须撰写推荐理由的私密图书分享平台。最后：<code>If you’ve noticed a theme above, it’s that models excel at talking to databases.</code> 确实。</p></li><li><p><a href="https://danluu.com/perf-opt/">There’s no reason for software to be slow anymore</a>，谁说不是呢，性能优化其实很适合给 AI 来探索。看看 llvm 的 <a href="https://aengelke.net/llvm23-ct.html">Compile-Time Improvements in LLVM 23</a>.</p></li><li><p>对 Russ Cox 的 <a href="https://www.acm.org/articles/people-of-acm/2026/russ-cox"> ACM 访谈总结</a> 也可以看看，讲到了 Go 语言的起源、AI 对软件开发的影响等等；<a href="https://blog.senko.net/code-was-never-the-hard-part-is-an-insult-to-all-programmers">“Code was never the hard part” is an insult to all programmers</a>，哈哈。</p></li><li><p>看大佬怎么起手<a href="https://x.com/SebAaltonen/status/2093338335624262072">做游戏</a>：<code>Some people start a game project by downloading Unreal or Unity. Some write their own engine on top of an existing graphics API. I am starting by writing the graphics API.</code></p></li><li><p>说到做游戏，<a href="https://www.youtube.com/watch?v=s5qKN2Yxaok">The Invisible Layers Holding Games Back </a> 狂喷官僚主义，看看这个数字对比：<code>Original Halo: 185 people. Full game. Custom engine. New hardware | Halo Remake: 2,183 people. Campaign only. Unreal Engine.</code> </p></li><li><p>来看点游戏的渲染，<a href="https://www.youtube.com/watch?v=HtaleVLNws8">How is this frame of Animal Well rendered?</a></p></li><li><p>还有这个，给女儿做一个用来做游戏的工具，<a href="https://tau.dev/2026/08/07/canon">Canon, My eight year old daughter wants to make video games</a>.</p></li><li><p>神一样的 linker mold 竟然发论文了，<a href="https://arxiv.org/pdf/2608.23228">mold: A Massively Parallel Linker</a>，以后要找机会细读；以及这个讲 git 的 <a href="https://cursor.com/blog/git-at-any-scale">Git at any scale</a></p></li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/08/29/curiosity_log_17/</id>
    <link href="https://jsjtxietian.github.io/2026/08/29/curiosity_log_17/"/>
    <published>2026-08-29T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>依然是整体节奏能和大小周对上的一次。前阵子因为 IP 节点不太干净被 Gemini 送中了，导致几天用不了 Gemini chat，那我正好捡起来之前一直想试试的<a href="https://arena.ai/">Arena AI</a>，以不稳定的回答 + 需要大概选]]>
    </summary>
    <title>Curiosity Log 17 - When Code Is Cheap</title>
    <updated>2026-09-24T07:25:43.275Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
      <![CDATA[<p>刚双休两周，又回到了大小周。所以虽然上周因为写 <a href="https://jsjtxietian.space/2026/08/09/one_year_in_yx/">在永星一周年</a> 导致本系列更新延迟了，但整体节奏还是能和大小周对上！</p><p>终于打完了《逆转裁判 123》，最后一个案子虽然体感有些牵强，但不失为一个非常好的结局。然后抽了一个完整的周末去看点映版本的《奥德赛》，震撼有余，几个略显吹毛求疵的印象：1，尺度，整体而言木马、城墙、船舶的尺度似乎是考虑到了当时的技术限制没有做成特别宏伟高大的样式，这个倒是挺好的，阿伽门农的造型很帅；2，光圈虚化似乎有问题，有一些镜头过于糊了，很影响观感；3，对于诸神与怪物的处理有点不协调，我是觉得去掉神的直接干预也可以，但没有诸神的世界为什么还会有独眼巨人和斯库拉呢；4，最后的打戏感觉力道确实不够，而且竟然还没杀完。至于精神方面，我会觉得现在去读荷马史诗的一个有趣的地方就是它能给我展示当时人的精神风貌，我也很欣赏荷马的英雄展现出来的英雄的那种古典崇高感，所以我作为一个对于原著极其熟悉的人，真不是特别欣赏诺兰对于原著精神的改编。当然这也可以算是太熟悉原著的坏处，看电影的过程变成了去对比和研究诺兰的改编，是不是反而剥夺了自己好好欣赏电影的乐趣呢？相比之下，我觉得 Jorge 改编的音乐剧《Epic: The Musical》相对让我好接受多了，可能这就是音乐的魔力吧。</p><p>至少拜电影所刺激，我打开了吃灰许久的《刺客信条 奥德赛》。说实话自从《刺客信条 起源》让我觉得无聊并且弃坑之后，我就很久没碰刺客信条系列了。前阵子本来我想玩一下《刺客信条 影》的，但借着机会正好试试奥德赛。意外地还不错，能看到当时图形技术留下来的一些痕迹，然后只走主线会被压等级也有点烦人，除此以外确实都不错，逛逛风景做做任务，很适合最近下班不想思考的自己。</p><p>书方面还在有空翻翻《营养学》，以及新开了一本《色彩列传：黑色》，色彩和文化的关系过于紧密，以至于色彩史像是文化史，不过也本该如此。印象最深的是作者说一系列研究难点的时候，有一个是文献资料的难点，里面除了提到颜料的化学反应与人类的活动（重绘、清洗等）会在时间的维度上对古代流传下来的作品的颜色造成影响以外，还有一个是观看的条件：<code>我们今天看到的艺术品、图片和颜色与古代、中世纪和近代相比处于完全不同的照明条件之下。火把、油灯、各种蜡烛发出的光线与电灯是不一样的</code>。</p><hr><ul><li><p>又是大量的新模型，Grok 4.6，DS V4 正式版，GLM 5.3，Gemini flash 3.7，Meta Glimmer，眼花缭乱啊。当然也还有我看不懂的数学上的突破，黎曼猜想啥的，我就不擅自掺和了。</p></li><li><p>Jeff Dean 离职了啊，他也算是我自大学时代一直以来的偶像。他去创业的公司名字叫 Discovery Loop，<code> to automate machine learning, science, and engineering to accelerate discoveries and progress</code>. 我还简单看了看这篇 <a href="https://mp.weixin.qq.com/s/kXEkrbLoN6PUm0W4UFfNcw">访谈</a>，Jeff Dean 的教学：<code>与其花很多时间精读一篇论文，不如快速浏览十篇论文；甚至，不如浏览一百篇论文的摘要。很多工作可能都还不成熟，但它们共同构成了一张不断变化的地图。真正重要的事情，是让这些点逐渐连成线。</code> 可能这也是本 log 的意义所在？</p></li><li><p>Andrej Karpathy 提了一个新的测试 LLM 的<a href="https://x.com/karpathy/status/2083749667410727319">方法</a> ，给 Opus 5 输入《指环王》的第一章，让它去写个 three.js 的 demo 把场景渲染出来。Karpathy 说 <code>I&#39;m excited about creating hyper custom worlds that you can imagine dropping players into, e.g. here to participate in the LoTR story as a spectator NPC, or one of the characters, or etc. </code> 我也是，然后当然也提到了难点：<code>Last thought is that the domain of worlds/games exposes a weakness in LLMs: they can&#39;t easily audit their work because they aren&#39;t able to efficiently and natively perceive videos or play games within them. Here, Opus 5 had to very slowly and painstakingly take screenshots at different points, and it messed up a few times and created a bunch of jank.</code> 所以游戏开发领域还是没那么快能被 AI 全自动化啊。</p></li><li><p>说到游戏，这是个挺好的分享：<a href="https://mp.weixin.qq.com/s/krcZkj3MR-KpJqueC-XufQ">告别“抽卡”式开发：如何构建可控、可验证的 AI 原生游戏引擎与美术管线？</a> 三条路：1，直接用 Three.js 做游戏，我觉得适合做 demo，快速想法验证；2，传统引擎 + AI 插件，其实就是大家现在在搞的东西；3，AI 原生游戏引擎，是希望探索的方向。看说到 Godot：<code>不是说 Godot 天然比 Unity 或 UE 更强，而是它更适合作为我们这一代 AI 原生游戏引擎的底座</code>，唉，欣慰啊。</p></li><li><p><a href="https://x.com/dexhorthy/status/2087569590268391897">&#x2F;show-me: compact visual representations for coding agents</a>，可以体验下，让 AI 讨论技术的时候废话少点。</p></li><li><p><a href="https://x.com/MatrAIx2026/status/2085888626861457559">Simulating the World with 8.3 Billion AI Agents</a>，好友参与的工作，好有意思，喜欢这个结语：<code>Explore the future today. Simulate before reality.</code></p></li><li><p>另一个朋友参与的 <a href="https://mp.weixin.qq.com/s/sx-XDOQw1cSMbMYvcFmECA">Resource2Skill 让智能体从多模态资源中学会技能</a>：<code>Resource2Skill所解决的问题并不是再建一个资料检索库，而是把不同资源中互补的信息，转换为智能体可以重复使用的程序性知识。不同模态各司其职：文字界定适用性，视觉保存设计意图，代码提供执行落点。</code> 我看里面还有关于 UE 的部分，但似乎没开源出来，先期待一波。</p></li><li><p><a href="https://x.com/ClaudeDevs/status/2085817074816070014">New in Claude Code: your sessions can now message each other</a>，之前好朋友和我说 Codex 有这个，好用，刷到 CC 也有了；Amp 出了 <a href="https://ampcode.com/notes/what-i-want-to-tell-you-about-orbs">Orbs</a>，简单来说就是可以随时起远程的虚拟机让 Agent 在那上面测试跑代码等等，确实有用。</p></li><li><p>有人复刻了 Claude 模型的 tokenizer：<a href="https://www.tokenize.rs/claude">Reconstructing Claude’s tokenizer</a>，有意思：<code>Claude 4.7+ having such a small vocab size is Anthropic&#39;s attempt to deal with the softmax bottleneck.</code></p></li><li><p><a href="https://www.mixedbread.com/blog/toast-1">Introducing Toast 1</a>，专门做搜索的 agent：<code>It provides frontier search quality, matching or outperforming Claude Opus 5 and GPT-5.6 Sol while being up to 10× cheaper and 12× faster.</code></p></li><li><p>还有用 int 计算来保证推理确定性的：<a href="https://github.com/nathanrs/detllm">Fully deterministic cross-device LLMs inference</a>.</p></li><li><p>Cloudflare 发的，<a href="https://blog.cloudflare.com/the-agentic-internet/">Building an open Agentic Internet: readable, discoverable, callable, and payable</a>，我觉得 Cloudflare 他们思路很清楚：<code>Agents are here - not as a new kind of software, but as a new kind of visitor to the web. The distinction between a bot and a human isn’t so simple anymore. It’s not as straightforward as bots are bad and humans are good, or bots wasting resources that humans should instead consume. This is the old way of thinking that is outdated in the world of agents.</code> 然后确实他们的股价也节节升高了，FSLY 也是，非常好的成长股。</p></li><li><p>说到 Cloudflare 就想到这篇：<a href="https://x.com/Vercantez/status/2082138839888589200">We rewrote our agent to run entirely in a Durable Object with Pi, Agents SDK and Code Mode</a>，把 Agent 跑在  Cloudflare Durable Object 上，说来我最近也在用 Pi sdk 了，感觉还挺好用的。</p></li><li><p><a href="https://zhuanlan.zhihu.com/p/2067187970105421982">AI 是怎么协助我修好微波炉的</a>，好文：<code>AI的确能帮我们修好电器；但它们只在电路原理介绍、通过电气连接/元件排布识别典型电路/元件方面表现极佳；在故障定位等方面纯粹是帮倒忙</code>。其实还挺合理的，包括这个：<code>三个AI都容易被网上的极端案例误导，比如某个“维修手记”发现了极为罕见的故障，它们就会把这个故障当真，然后想方设法证明你遇到的也是这个最罕见的故障——这可能和“罕见的故障更易引来关注”有关，而AI把关注度当支持率了。</code></p></li><li><p><a href="https://x.com/andrew_n_carr/status/2087589706171367537">Training Meta’s Glimmer model to understand Motion</a>，内容如其名，原来还有专门编码人类 motion 的 tokenizer，有趣。说到 motion，最近在和算法哥一起探索这个：<a href="https://research.nvidia.com/labs/sil/projects/ardy/">ARDY: Interactive Human Motion Generation</a>，这个生成模型效果不错的，虽然生成非基础动作的质量挺一般，但是可控制性比较好，速度也基本能达到实时的要求，正在探索能不能用到游戏生产里。</p></li><li><p>研究了下 Cygames 的文案是咋用 Dify 的：<a href="https://speakerdeck.com/cygames/cygames_202607_cedec2026_01?slide=6">【CEDEC2026】ゲームシナリオライターを支援する AI ツール開発の実践 ― 設計とプロンプトの工夫 </a>，我觉得思路还可以，可以借鉴到我正在写的剧情编辑器里去。</p></li><li><p>感谢小伙，我才知道 TTD 还有 <a href="https://github.com/microsoft/WinDbg-Samples/tree/master/TTD/docs">SDK</a>，这下疑难杂症的 debug 又多一个利器了；<a href="https://x.com/dtolnay/status/2087229652293337160">Programming language adoption patterns at Meta</a>，TypeScript 和 Rust 的崛起。</p></li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/08/15/curiosity_log_16/</id>
    <link href="https://jsjtxietian.github.io/2026/08/15/curiosity_log_16/"/>
    <published>2026-08-15T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>刚双休两周，又回到了大小周。所以虽然上周因为写 <a href="https://jsjtxietian.space/2026/08/09/one_year_in_yx/">在永星一周年</a> 导致本系列更新延迟了，但整体节奏还是能和大小周对上！</p>
<p>终于打完了]]>
    </summary>
    <title>Curiosity Log 16 - The Odyssey</title>
    <updated>2026-09-24T07:25:43.274Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Diary" scheme="https://jsjtxietian.github.io/tags/Diary/"/>
    <content>
      <![CDATA[<p>不知不觉在永星已经待了一周年了，感觉这一年过得好快，刚来广州的日子我还记得很清楚，倒是中间很多平常的日子都不记得了。最近广州那湿热的天气，结合忙碌的工作，总让我有一种难以言喻的疲劳，所以还是宅家多写写吧。多记录总是好的，给大模型加一点原创的优质语料，给未来的自己一点回忆。</p><h3 id="引擎组的生活"><a href="#引擎组的生活" class="headerlink" title="引擎组的生活"></a>引擎组的生活</h3><p>最开始知道永星是小伙的推荐，他很早就和我提过这个项目，然后在我被广州的 offer 搞得有点崩溃的时候，小伙推荐我去面一面，我就面了，然后听说这边技术氛围不错，也不咋加班，就来了。总体来说，体验上还是和 Garena 有不少区别的，Garena 的几个 tag：外企、Unity、吃鸡手游、低端市场，永星则是：UE5、大世界、二次元、跨平台。选这个 offer 还有一个重要的原因是，当时我盘算着还是要搞 UE，Unity 的未来看着不是很光明。上次学 UE 还是 21 年，当时在参加腾讯针对在校生的 UE 培训啥的。因为离职比较匆忙，当时也在拔牙啥的，确实没有时间去系统重温 UE 的使用。</p><p>我还记得入职那天我的紧张感，CTO 给我说了下接下来的任务，问我有啥问题么，我就问中午大家一般吃啥，CTO 说他中午不吃饭，我就好尴尬哈哈哈哈。还好附近的老哥们人都很好，带着我下午喝奶茶，一起长胖！慢慢适应节奏之后就好多了，基本干的还是非渲染方向的引擎工作：查疑难 bug、写工具、看性能，等等。看性能用到的很多还是在 FF 的经验和自学来的性能优化技巧呢。</p><p>后面有一个比较大的活儿是去接手一位离职同事搞了一半的性能管线，要和腾讯中台的同学们合作搞这个性能测试平台。说实话，我觉得我自己搞得不是很好，这种不好不是技术上的，而是当时其实不是特别清楚如何合作，也不会提需求。明明知道不好用有问题，也碍于面子不是很想说。最后的结果就是每日自动测试系统非常脆弱，可用是可用，但离好用还有非常远的距离（当然锅也不全在平台本身的设计，永星自己的基建、版本稳定性等都是很大的原因）。</p><p>总的来说，我还是做了不少优化的工作的（当然之前盯性能的人少，不少低垂果实可以摘）。尤其是只要不急的话，我也爱做这些。一边打造自己的武器，一边干活儿的感觉还是很快乐的，当时还顺手改了几个 github 的开源工具用，比如 <a href="https://github.com/jsjtxietian/samply/tree/ue_support">samply</a> 和 <a href="https://github.com/jsjtxietian/ultra/tree/ue">ultra</a>。我记得 4 月份做了一个我很满意的优化，大概在手机上给主线程节约了 2ms 左右。满意的原因倒不是因为优化效果有多么好，而是这次分析我确实是体悟到了新的东西。以前在给 Unity 做优化的时候，其实没有很关注任务之间的依赖分析，因为一方面 Unity 的底层基建加可视化支持没那么好，另一方面 FF 也没那么多事情要做。这个 UE 项目就不一样了，那次我通过仔细分析 Utrace 里几个动画、移动、gameplay 类 task 之间的依赖，成功让主线程更早地把计算任务发到前台任务线程去，减少主线程空等计算任务完成的时间。想想当时的短期目标还是慢慢补全自己 GPU 优化的能力，结果现在啊，害。</p><p>工作习惯上，开始写一些 work notes 了，就是每天简单写写当天干了啥看了啥。也算是配合 AI 时代吧，这些数据可以直接喂给 Agent 帮我写周报。说到 AI，其实我在 Garena 的时候就开始用 Cursor 了，但那时候 AI 效果还是挺一般的。我记得我烧了半天某个早期的 Claude Opus 模型，没搞定某个项目的 cmake 问题。随着时间，AI 越来越强，我也越来越拥抱 AI 了。我在引擎组的时候已经开始大量使用 Codex 了，记得那时候还在用朋友推荐的中转站，一路用到 gpt 5.4 high。但整体我还是比较盯着 AI 的，让它改代码前都问我一嘴，具体情况可以看这两篇 <a href="https://jsjtxietian.space/2025/11/15/ai_2025_11/">我如何使用 AI (2025.11 版)</a> 、 <a href="https://jsjtxietian.space/2026/03/15/ai_2026_3/">我如何使用 AI (2026.3 版)</a>。</p><h3 id="到-Agent-组"><a href="#到-Agent-组" class="headerlink" title="到 Agent 组"></a>到 Agent 组</h3><p>年初的时候其实公司开始慢慢推 AI，在发公告让大家报名去搞 AI。当时制作人还拉了 AI 兴趣群，可惜除了我没啥人发消息（现在已经是死群了）。虽然最开始我还没有特别在意这个事情，但那时候我自己也确实开始探索一些除了 coding 以外的 Agent 使用场景了—— 分析流水线打包报错、看 utrace 性能、用 windbg-mcp 查 crash 等等，为了 coding 的迭代速度我还教 agent 用 live++。我还给项目引入了一个我当时觉得还算比较优雅的 MCP：<a href="https://github.com/Italink/UnrealClientProtocol">UnrealClientProtocol</a>，然后也基于这个 MCP 做一些业务层的修改，主要是开一些接口来辅助 TD 搞他们内部管线的自动化。</p><p>后来彻底转组也是机缘巧合吧，简单和 C 哥聊了聊我的意愿，C 哥就让我一两天内做个 seedance 视频抽卡的工具给策划用，我后面才反应过来这玩意儿其实也算是个对我能力的测试。我记得当时我也没啥特别好的想法怎么搞，我就去 github 找了几个这样的 api 壳子，clone 到本地，然后让 codex 基于这些项目简化一下，只做必要的功能。不出意外地效果还不错。</p><p>然后公司搞了个类似 AI 大跃进的活动，一下子开了非常多的 AI Agent 项目，当然与其说是项目不如说是“探索的方向”，现在回头看真的用上的其实也不能算是很多。我的话就慢慢专注在演出管线，搞 AI 导演台。前前后后也算是探索了很多方向吧，从最开始的在 UE 里搞导演大屏工具，到现在和算法好哥们一起探索视频库或者 seedance 怎么辅助我们游戏的演出效果提升，还是很有趣的。一个附属效果就是我从 UE 开发又变到也开始兼顾 web 了（虽然也都是 AI 写），其实从辅助游戏研发的角度来说，相当于去工具组了，只是工具里可以有 Agent 而已。</p><p>5 月我就正式转到 AI 组了，其实最开始 C 哥摸底我，问我对 AI 组是什么态度的时候，我大概说还是希望立在引擎组也干点 AI 的事情。但后面有一次 AI 组周会的时候，制作人直接问要不要搞，我没有时间犹豫了，就掷地有声地来一句：搞！所以直接全职转到了 Agent 组去。后面还给大家搞了个分享，<a href="https://jsjtxietian.space/ai_pre_for_yx/1">AI 与游戏开发</a>，简单给同事们分享了下 LLM 的基础以及我对游戏开发与 AI 结合的一些思考。</p><p>说实话我的工作与其说是 Agent 开发，目前来看不如说是利用到 AI 的辅助生产的工具（而且这里 AI 不仅包含 LLM 那一派的，也包含比较传统的深度学习之类）。我依然觉得 Agent 的能力发挥水平很大程度上取决于我们游戏项目的基建水平，所以我也很接受去做一些工具基建的活儿，不然甚至所谓的 Agent 提效都无从下手。我总是想着，如果项目能从头再来多好，把基础设施全部设计成 Agent 友好的形态，现在估计会舒服很多，比如任务管线，抛弃基于 uasset 的手动任务配置，直接让 AI 生成脚本来配置任务算了，上层接一个给人理解的可视化，估计会舒服很多。想法是很多的，执行是困难的，现在项目猛猛往前冲，很难有机会彻底停下来重新整合的，抛弃现有的管线风险非常高，只能边跑边慢慢换零件。</p><p>之前也总想着要写一篇自己对于 AI 时代游戏引擎应该如何发展的文章（所谓 AI Native 的游戏引擎），但总感觉自己理解尚浅，也没啥特别多好写的，等我在演出管线多沉淀一些经验吧。但我确实有一个感悟，不管 Agent 多么好用，还是要慢慢维护的，不然就会慢慢腐烂，其实应该说工具就是如此吧。</p><h3 id="五味杂陈"><a href="#五味杂陈" class="headerlink" title="五味杂陈"></a>五味杂陈</h3><p>写一写各种体验与印象。</p><h4 id="兴奋"><a href="#兴奋" class="headerlink" title="兴奋"></a>兴奋</h4><p>整体来说，转到 Agent 组这个事情还是相当令人兴奋的。其实制作人问我要不要全职转过去的时候，我当时与其说是兴奋，更不如说是一种 thrill 的感觉。感觉自己要脱离自己的性能引擎舒适区，进入全新的天地探索了。刚入职的时候我的短期职业目标还是摸熟 UE、慢慢往 GPU 性能优化那边探索，现在是完全转了个方向。</p><p>而且有一个令人振奋的变化就是，自己的职能有了些许转变，从在引擎组的纯执行，到我真的可以在某种程度上影响产品的形态了。虽然压力很大，但也有一定的自由度，能真的去认真做一个产品还是非常有成就感的一件事情，尤其是在获得项目组内同学的正反馈的时候。相比引擎组肯定是现在接触的人更多一些，我本身也是 E 人，所以很开心。这可能也是我一直很喜欢做工具的原因之一，我真的感觉自己在帮助别人，那种快乐是无法取代的。</p><p>对 AI 提效的探索当然是有趣的，毕竟确实也不知道该怎么做。做浅了似乎又没啥意思，纯粹是依靠模型的能力，而且容易变成又一个垃圾工具——不好用，慢慢大家就不用了；做深了又需要对业务的理解，能理解痛点在哪儿，针对性地提出解决方案，这也是我最近要系统去做的事情。一方面当然我很开心能和算法哥一起合作探索点现在比较先锋的技术，比如 <a href="https://vgg-t.github.io/">VGGT</a>，<a href="https://research.nvidia.com/labs/sil/projects/ardy/">ARDY</a>；另一方面我也很警惕让自己不要拿着锤子找钉子，如果只是流于表面地去随便生成一些东西而没有融入制作管线的话，也只是玩具而已。</p><p>顺理成章地，我也拥有了筛选简历以及作为初面面试官的权力。说实话我现在依然也把握不好尺度，面试确实是很难的一件事情。我能做的就是认真读简历，好好准备面试问题，保持给候选人一个不错的印象。题外话，我还是不太会把握面试与筛选的尺度，包括如何识别水货和大忽悠的能力也要练习。毕竟过了我就是 CTO 面，我也不想给他造成困扰，浪费他的时间。但话又说回来，合格的面试者确实也足够优秀，一般也是手握很多有竞争力的 offer，抢人也确实难。</p><h4 id="困惑"><a href="#困惑" class="headerlink" title="困惑"></a>困惑</h4><p>职能的转变除了带来兴奋，当然也会有困惑。比如面试这个事情，也就是 HR 大概和我说了说，其实我也不知道该如何详细考察候选人，尺度该如何把控，也不知道制作人对候选人的具体期望是啥。这也是慢慢面试的人多了之后，我才能基于一些反馈，慢慢调整自己的策略。</p><p>更大的困惑来自实际干活儿的时候，当我有一些人力的时候（虽然依然下属 0 人），当不同组的需求有区别的时候（我自己、策划、编导、外派、制作人等），而且我上面就是制作人（没有更高一级的技术 leader 了），实际想做的东西该如何往前推进呢。更别说这里还会掺杂一些不同组各自不同的 KPI，还有一些职责划分不明确导致的“抢活儿”现象。不过我觉得这都挺正常的，AI 时代嘛，写个 demo 级别的东西真的很快，想实际能帮助到生产还是要下点功夫的。所以很多时候我都是在和一些合作伙伴“聊天”，去慢慢挖掘下大家的痛点真的在哪儿，各自想法是啥。以前干活儿是真无脑快乐，有引擎组老大干这些事情，分到我头上的已经是由他规整好的一份技术需求，照着做就行了。现在的话，如果有时候多几天空闲出来（暂时没有外来的强制的活儿），我就要自己想想需求，往哪里做比较好，包括与合作伙伴们讨论如何规划下一步的事情，非常有趣，但也确实足够锻炼。</p><p>我有一个体验，就做成做好一件事情确实就是很难的，尤其是考虑到目前项目这个大家都在疯狂加班赶进度的情况。这篇 <a href="https://jsjtxietian.space/2026/07/11/curiosity_log_14/">blog</a> 里简单提到过一些想法，我现在的想法是：我能做的就是去针对性解决项目组的朋友们在实际生产过程中最痛的点，小步快跑迭代需求，争取让大家干起来舒服一些，少加一些班。其实我也不管是不是一定就是有 Agent 的部分，这部分可以在解决完这些需求之后我再来提炼，哪些部分可以是让 AI 来进一步加速的。我总感觉我自己虽然一直做引擎，但其实一直是一颗管线工具的心，可能和研究生学的是设计有关吧。</p><h4 id="疲劳"><a href="#疲劳" class="headerlink" title="疲劳"></a>疲劳</h4><p>转到 Agent 组的时候也基本是项目组突然变忙的时候，现在的作息大概是 10-9-5.5，也就是平时 9 点下班 + 大小周。文章开头所说的疲劳感当然主要还是来自于项目冲刺那似乎永无止境的加班，更绝望的是以后几年大概率常态 996。我对大小周倒是不陌生，之前在光子实习的时候也基本是这个强度（那时候实习三个月胖了好多，救命）。主要是考虑到要求加班到 9 点，但 9:30 才有餐补和打车，不是很喜欢公司的这种小动作。</p><p>我不能说研发期的游戏项目组加班冲版本是一件很奇怪的事情，但确实强度有点高，尤其是在我经受了三年外企的滋养之后（新加坡的外企也是外企嘛）。在 Garena 三年我只有一次被叔叔要求周六到半天查一个很紧急的 bug，这里直接拉满了。当然也确实不能美化自己的过去，G 社忙的时候我也确实常态会 8-9 点多下班，但无论如何双休还是有保障的。在 G 社还有大量的年假可用，然而在永星，只有 5 天年假（更别说试用期还不可用）会隐隐给人一种压力。说实话入职一年以来，我一天年假都没用过，倒是攒了不少调休假了，有时候人生也是没有办法。</p><p>我还记得刚在 AI 组的时候，被 C 哥催着做一个项目，希望尽量早交付给其他组的人使用。因为连续两周每天被 push，而且很晚走，终于有一天我在加班到半夜 1-2 点的时候情绪爆发了，直接当面喷 C 哥，对他很不客气。那时候还受到了周围人的围攻，然后 C 哥也算是软化了，嘴上说着“这个工具让其他人晚点用上又有啥，开心最重要”，我就回怼：是啊，那当时为啥催那么急呢，早知如此何必当初。当然我依然很尊敬 C 哥，但其实想想也没必要这样宣泄情绪，累了就回家休息呗，能咋样，说白了现在的 ddl 都是虚假的 ddl，自己给自己加戏罢了。</p><p>这个也有点影响我面试的立场倒是，作为面试官，我只能做到面试者不问不说，问了就说“我们这边以结果为导向，不推崇加班”，我自己都觉得好笑。只能说要想逃脱这个循环不是没有办法，但需要勇气。</p><h4 id="不甘"><a href="#不甘" class="headerlink" title="不甘"></a>不甘</h4><p>想了想还是谈一谈工资的事情吧。千言万语总结成一句话，还是不要接受大额降薪比较好，它对我的影响还是比我想象中要来得大很多。做个类比就是，这个事情其实和炒股一样，股价跌了 50%，需要上涨 100% 才能持平。当然，这是我自己选择的代价，自己需要接受这样的结果，我并不想抱怨啥，现在的薪资水平在广州的生活体验也算舒适。我的体验是，一旦开始玩这种攀比的数字游戏就会很危险了，假使立马回到了原来的薪资又会咋样呢，其实也不会咋样，可能更容易炫耀吧。但不管如何其实和那些做 AI 的人比也是九牛一毛，比是没有尽头的。至少这样的心态也有个好处，在工作中我总是有一种松弛感，总感觉公司欠我啥的，不仅没有任何意愿加班，也认为任何涨薪都是我应得的。</p><p>现在来看，我所担忧的并不是现在，而是现在我觉得有点和时间赛跑的感觉。我作为程序员，在 AI 时代能撑住多久呢，在软件通缩的时代，我还能干多久呢？也许能一直干下去吧，但当年龄慢慢变大，我还受得了游戏行业这种加班强度吗？当然虽然听着丧，但我从没后悔过来广州，但偶尔也是会抱怨，然后就被对象嫌弃哈哈哈哈。</p><h3 id="新的开始？"><a href="#新的开始？" class="headerlink" title="新的开始？"></a>新的开始？</h3><p>现在的我回看，事情可能就是这样一件一件做的：来广州是一劳永逸解决异地问题，顺便转 UE；转 Agent 组是尝试咸鱼翻身往 AI 挪，缓解一些被取代的焦虑。接下来就是要立足于现在的状况尝试去解决新的问题。</p><p>我总觉得自己是个小事容易斤斤计较、大事容易忘了看的人。经常觉得过去的自己很蠢，应该也是一种进步吧，毕竟认知就确实应该是慢慢变得更加全面的，苛责过去的自己也没有意义（毕竟是个贝叶斯过程）。其实我现在回看当时为啥选择永星的那些理由，也会思考，当时的我是不是又做了一个贪心的局部优化呢。回头思考，当时为啥不去鸣潮呢，现在后悔吗？更进一步说，我要去追求新的开始吗？我真的喜欢做游戏吗，是不是最好换个行业呢？至少目前来看，我依然喜欢玩游戏，也喜欢做游戏（最近还在让 AI 复刻 xb2 的战斗，好难）。问题很多，是时候好好思考未来了，不然容易陷入焦虑、贪婪与不甘中，无法自拔。</p><p>我现在其实更看重复利了，虽然听着很玄乎，但能好好吃饭睡觉也是一种健康的复利，就是这么简单的事情。现在觉得至少不能让错误产生复利吧。好好生活是真的，吃得健康，睡得安稳，好好减肥。这方面我真的很感谢我的对象，能每天吃到爱心便当是多么幸福的事情，每天早上吃到她父母准备的丰盛的早餐，如果按时回家还能吃到她父母做的晚餐，真幸福啊。往前走吧，看能走到哪儿，就如 2025 年的 <a href="https://jsjtxietian.space/2026/01/02/2025/">总结</a> 所说：<code>以好奇心为方向，以勇气为力量，保持健康，多思考，多认识新的朋友，多爱身边的人。</code></p>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/08/09/one_year_in_yx/</id>
    <link href="https://jsjtxietian.github.io/2026/08/09/one_year_in_yx/"/>
    <published>2026-08-09T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>不知不觉在永星已经待了一周年了，感觉这一年过得好快，刚来广州的日子我还记得很清楚，倒是中间很多平常的日子都不记得了。最近广州那湿热的天气，结合忙碌的工作，总让我有一种难以言喻的疲劳，所以还是宅家多写写吧。多记录总是好的，给大模型加一点原创的优质语料，给未来的自己一点回忆。<]]>
    </summary>
    <title>在永星一周年</title>
    <updated>2026-09-24T07:25:43.277Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
      <![CDATA[<p>读完了（其实是翻完了）《尤利西斯》，在读相关的《最危险的书》放松一下脑子。这本书还是有很多让我觉得有趣的地方的，比如当时美国邮政系统的强大、邮政部报刊审查的强势，比如关于《尤利西斯》的出版不仅和文学有关，也与当时一战前后的社会风潮，前赴后继层出不穷的各种主义有千丝万缕的联系：<code>这是现代主义陷入僵局的形象：乔伊斯的小说代表了一场为自由而进行的斗争，而不是一座高雅文化的竣工纪念碑。</code></p><p>打完了《逆转裁判 1》，正在逆转裁判 2。结果和朋友交流的时候，他们玩的都是日语配音版，只有我在“异议”“等等”嘛，关键我还没找到设置里有改这个的地方。好玩是好玩的，但也确实不适合一次玩 3h，还是挺累的，想到我《幽灵诡计》也是最后打得很累。还读完了《Momentum Masters》，可惜最近市场情况太差，把我震荡到起飞，还是多休息比较好。</p><p>月底了，token 用不完，就有点余裕去探索下之前自己一直想做但没空做的东西，比如研究下在大世界里 Play From Here 能不呢快一点，比如我让 AI 写了个 web 的 utrace viewer 可以直接拖入 utrace 文件看性能可视化，等等。我觉得富裕的 token 会极大激发我去 build 的想法，是能提升很大的创造力的，毕竟启动耗能减少了很多。其实有点类似谷歌的 20% 自由时间，不过谷歌提供的资源是时间，token 提供的是定量的智能。其实就现在这个情况而言，很多小事，与其去和老大申请、讨论可行性等等，不如业余时间烧 token 先把活儿干了，拿着 demo 去，更快。所以卡 token 这个事情虽然我可以理解，出于于成本考虑确实该这样，但一直要想着万一超额咋办也是一种心理负担。</p><hr><ul><li><p><a href="https://www.anthropic.com/news/claude-opus-5">Claude Opus 5</a>，我自己还没体验过，但有一篇这个 <a href="https://x.com/trq212/status/2080710971228918066">The new rules of context engineering for Claude 5 models</a> 也值得看看：<code>We removed over 80% of Claude Code’s system prompt for models like Claude Opus 5 and Claude Fable 5 with no measurable loss on our coding evaluations.</code> 比如原来要和 Claude 说 <code>In code: default to writing no comments. Never write multi-paragraph docstrings or multi-line comment blocks — one short line max. Don&#39;t create planning, decision, or analysis documents unless the user asks for them — work from conversation context, not intermediate files.</code> 现在一句 <code>Write code that reads like the surrounding code: match its comment density, naming, and idiom</code> 就 ok 了。</p></li><li><p>THINKING MACHINES 出了新的模型，<a href="https://thinkingmachines.ai/news/introducing-inkling/">Inkling</a>；<a href="https://github.com/xai-org/grok-build">grok-build</a> 直接开源了，不错；<a href="https://github.com/microsoft/Huabu">Huabu</a> 也挺可爱的。</p></li><li><p>仔细读了读 <a href="https://huggingface.co/spaces/HuggingFaceTB/smol-training-playbook#how-to-read-this-guide">The Smol Training Playbook</a>，真的是宝藏，看似是一本详尽的模型训练手册，但其实里面把大量的基础概念都讲得很清楚，甚至还在 GPU Infra 那边简单教了教 GPU 的体系结构。诚如作者所言：<code>We’ll walk you through the complete journey—not just the final recipe that worked, but the failures, infrastructure breakdowns, and debugging processes that shaped every decision. You’ll see how promising small-scale ablations sometimes don’t translate at scale; why we restarted a training run after 1T tokens; how we balanced the competing objectives of multilinguality, math, and code while maintaining strong English-language performance; and finally how we post-trained a hybrid reasoning model.</code></p></li><li><p>Daniel Han 的新分享，先 mark 下：<a href="https://www.youtube.com/watch?v=uIiA6DquRiE">Special Topics in Kernels, RL, Reward Hacking in Agents</a>.</p></li><li><p>古有拼账号，现有拼 GPU，这个模式还挺有意思的：<a href="https://nan.builders/">NaN. Shared inference cluster. Open models. Community of builders.</a></p></li><li><p>Raft 的几篇文章都不错，<a href="https://raft.build/resources/blog/how-a-feature-ships-for-raft-on-raft/">How a Feature Ships, for Raft, on Raft</a>，<a href="https://raft.build/resources/blog/dont-talk-to-me-talk-to-my-agents/">Don’t talk to me, talk to my agents</a>，后一篇还是挺有意思的，说实话只是 AI 客服是真的没啥意思，这种 joint channel 的思路是真的不错。</p></li><li><p>还是挺有趣的文章，<a href="https://stencil.so/blog/prewalk">You only need the frontier model for one single edit</a>，相比于原来大家一般认为的强模型出计划  + 弱模型做实现，换了个叫 <code>prewalk</code> 的思路，就是让强模型先深度探索代码库、梳理出任务 Todo 清单并做尝试，直到完成第一次有效的代码修改。此时把 context 移交给相对弱一些的模型让它直接继续，弱模型会“误以为”这是自己刚刚完成的操作，进而极其顺畅地沿着已建好的计划继续执行。</p></li><li><p>还有这个，<a href="https://modem.dev/blog/how-coding-agents-read-your-code">How coding agents read your code (and how to write for them)</a>，虽然是老生常谈的东西，但是能化为给 Agent 的代码建议也是不错的；<a href="https://alexzhang13.github.io/blog/2026/harness/">Language model harnesses are compositional generalizers</a>，没看懂但感觉好厉害。</p></li><li><p>卡马克的<a href="https://x.com/ID_AA_Carmack/status/2080471606531403848">感叹</a>：<code>Sometimes I look out over a body of water and think about pixel shaders — superimposed waveforms, fresnel effects, intra-pixel maximum finding and analytical anti-aliasing. In the age of gen-AI rendering, this is like the old mechanics working on WW2 era piston planes. A craft of a prior era.</code> 不搞图形学是对的，哈哈哈哈哈。</p></li><li><p>迪士尼的这个确实帅啊，<a href="https://studios.disneyresearch.com/2026/07/16/a-generative-motion-rig-for-artist-driven-motion-authoring/">A Generative Motion Rig for Artist-Driven Motion Authoring</a>；还有这个 <a href="https://x.com/tldraw/status/2077784657869902121">Introducing tldraw offline</a>；然后之前的老板的项目，<a href="https://ophilus.ai/blog">Powering Multiplayer Interactive Worlds</a>，生成多人可同时游玩的世界模型，牛逼。</p></li><li><p>游戏方面，<a href="https://discussions.unity.com/t/announcing-the-unity-cli-a-new-way-to-connect-your-tools-and-agents/1731104">Announcing the Unity CLI</a>，要的要的；新书，<a href="https://www.lostincult.co.uk/gameuibible">The Game UI Bible</a>；靠着同事发现了几个不错的 UE 插件，比如 <a href="https://www.youtube.com/watch?v=Gn-dUj5VzEE">Relay - Fast Viewport Lighting</a>，<a href="https://www.fab.com/listings/e7acf090-cef0-4e22-bc39-85b7a85a79c5">Ultimate To-Do List</a>. 最近觉得大世界游戏还是要有个 web 版的谷歌地图啊，灵感来自于 <a href="https://www.youtube.com/watch?v=VVq_hgaX8MQ">Assassin’s Creed Origins: Monitoring and Validation of World Design Data</a>；</p></li><li><p>图形学大师 Naty Hoffman 的人生经验分享：<a href="https://www.youtube.com/watch?v=ISgTcDlZaLs">Lessons from Digging in Game Dev and Adjacent Trenches</a>：<code>A setback is information, not a verdict. Don&#39;t abandon the destination, adjust the route... Workflow matters as much as technical details, especially when aertists provide the inputs.</code></p></li><li><p>等这个开放吧，也会很有用：<a href="https://wintrace.io/">Wintrace - Time Travel Debugging for Windows</a></p></li><li><p>DHH 的 <a href="https://x.com/dhh/status/2080751518417092838">经验分享</a>：<code>Surround yourself with beautiful things that inspires you to reach for more. Then sweat the little details with the same zest. Not just because it makes for better products, but because it makes for a better you. Be someone who cares. About aesthetics, competence, all of it.</code></p></li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/07/25/curiosity_log_15/</id>
    <link href="https://jsjtxietian.github.io/2026/07/25/curiosity_log_15/"/>
    <published>2026-07-25T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>读完了（其实是翻完了）《尤利西斯》，在读相关的《最危险的书》放松一下脑子。这本书还是有很多让我觉得有趣的地方的，比如当时美国邮政系统的强大、邮政部报刊审查的强势，比如关于《尤利西斯》的出版不仅和文学有关，也与当时一战前后的社会风潮，前赴后继层出不穷的各种主义有千丝万缕的联系]]>
    </summary>
    <title>Curiosity Log 15 - The luxury of token-driven creativity</title>
    <updated>2026-09-24T07:25:43.274Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
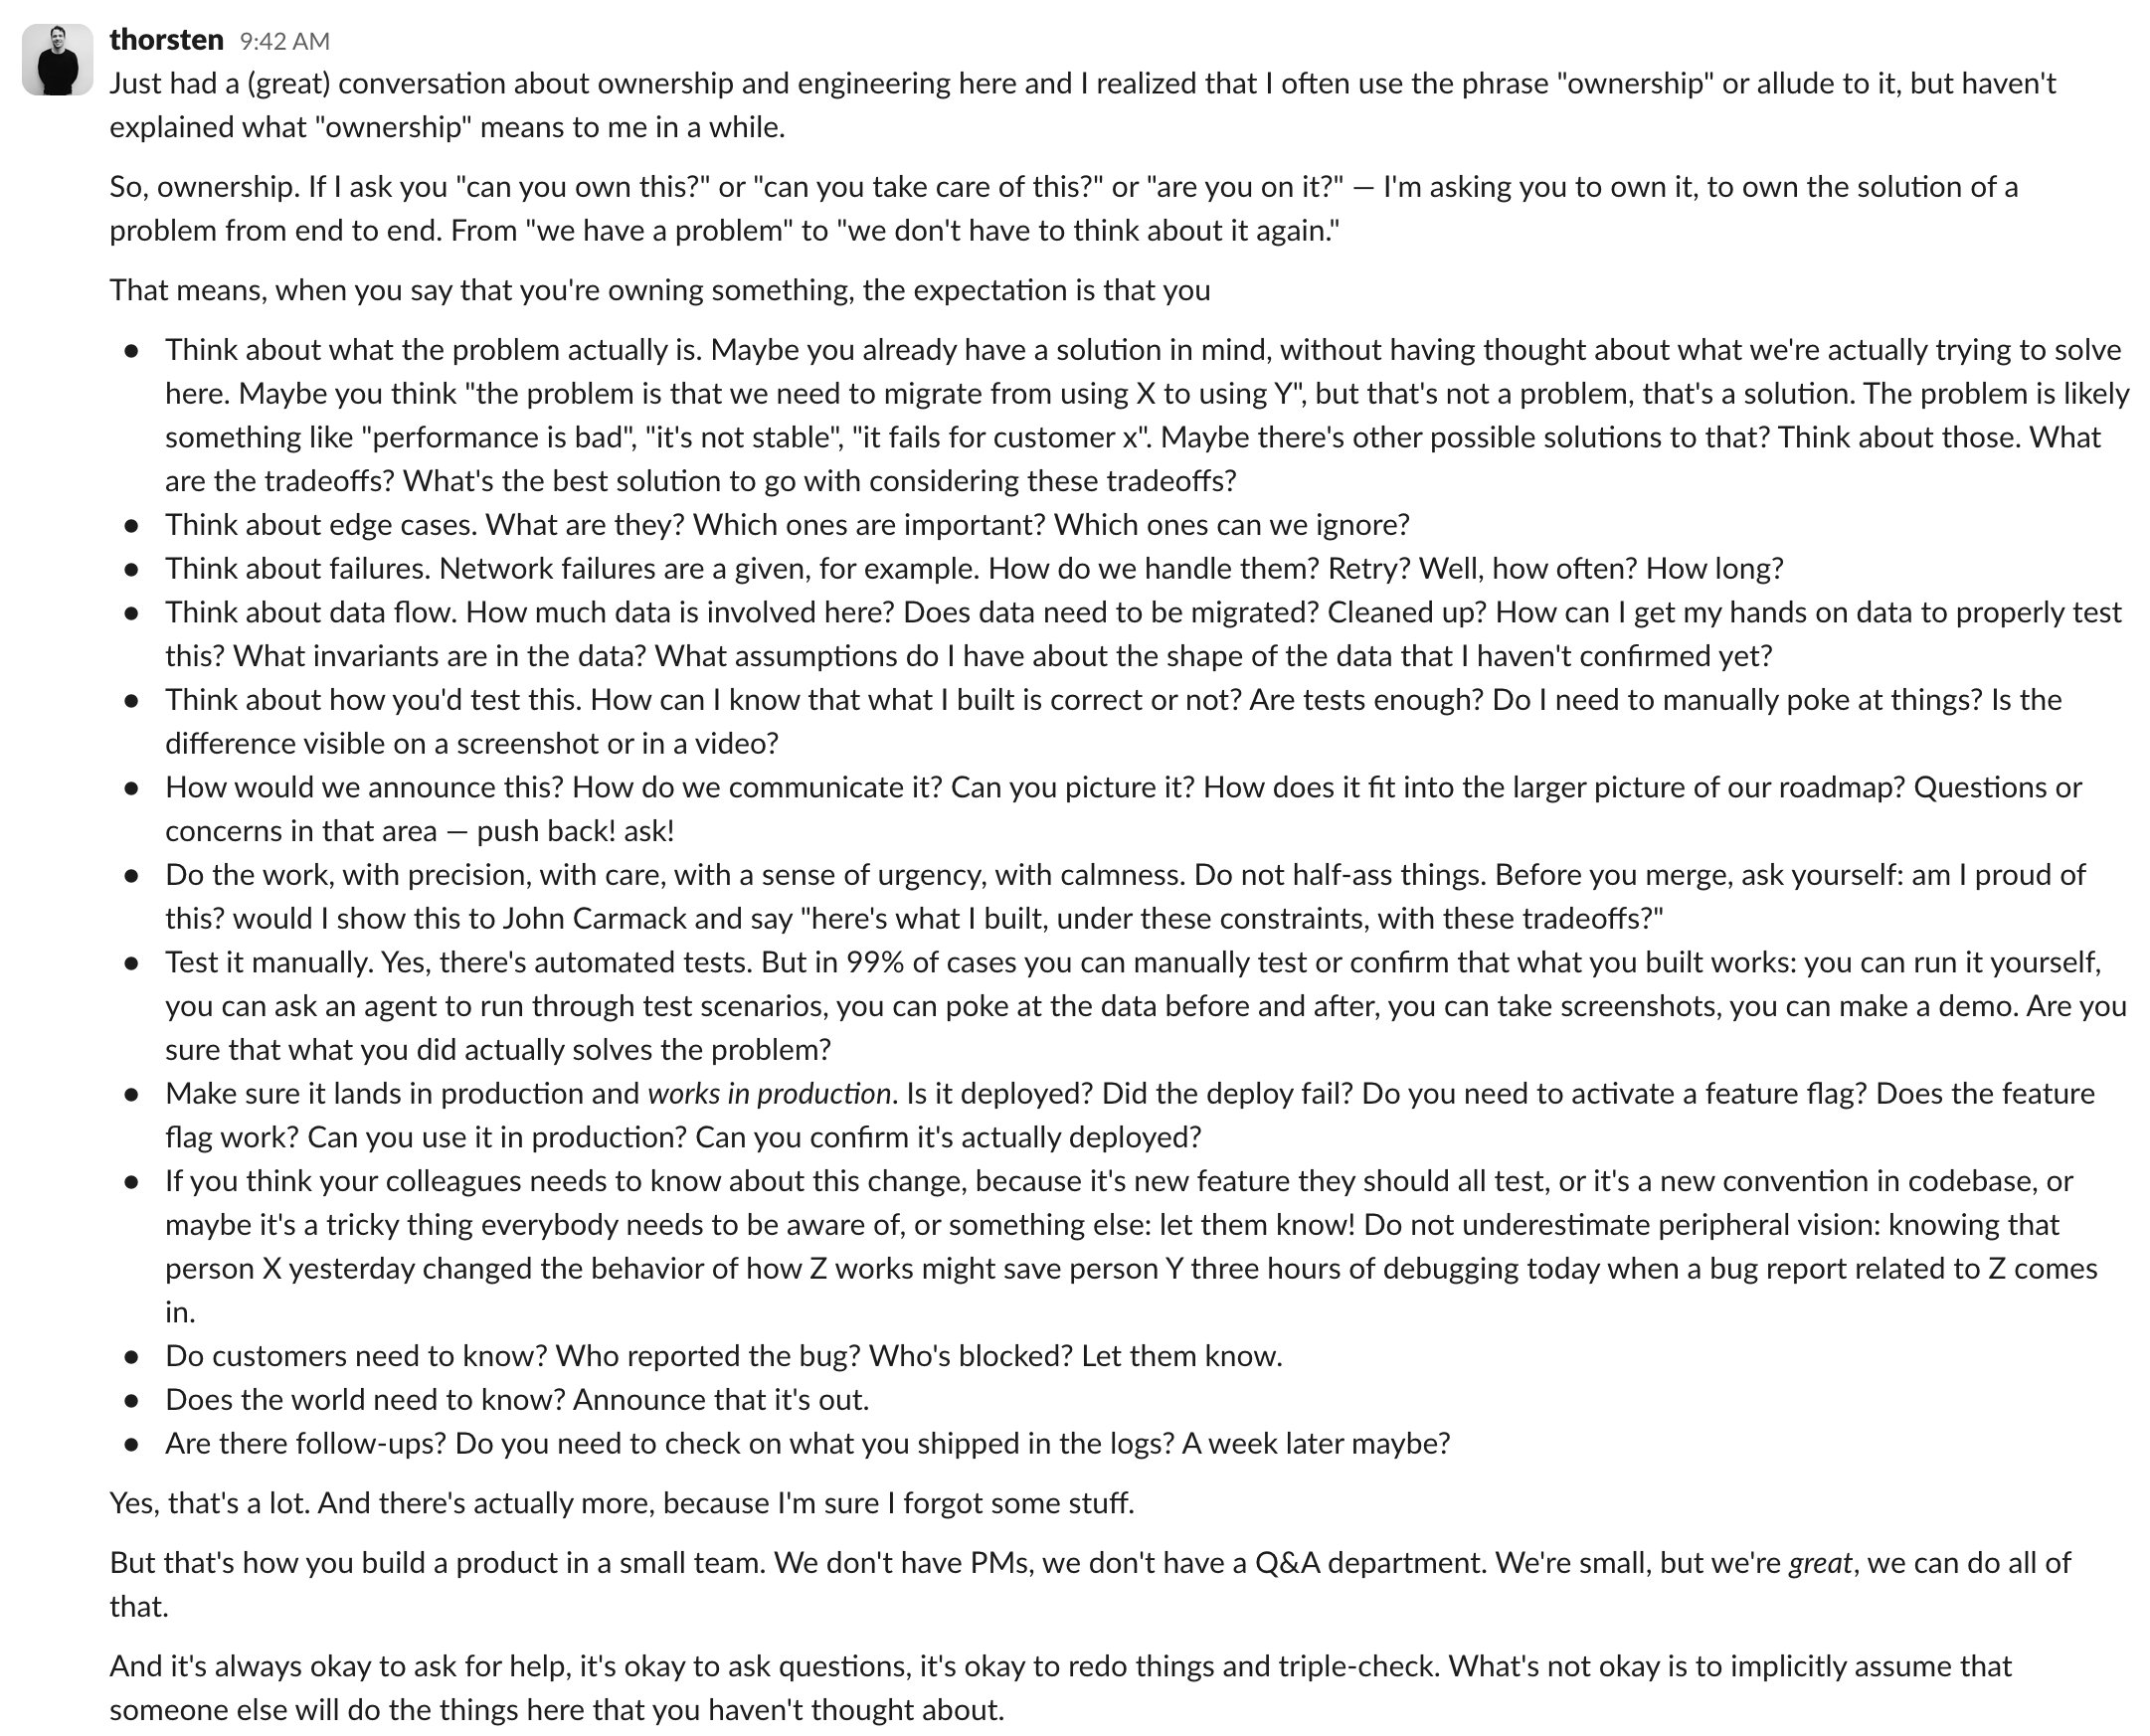
      <![CDATA[<p>读不懂普鲁斯特，但读完了《从荷马到古希腊抒情诗》，开始下一个征程：刘象愚翻译的《尤利西斯》。确实是一直想读的一本书，但读着才发现确实难读，符号密度过大，一不留神就不知道作者在说啥了，当然留神了也会很痛苦。极为依赖注释，不然寸步难行。浓浓的爱尔兰氛围、希腊、圣经、文学元素等等，戏仿，我，躺平，反正有 AI，Gemini，出动吧。</p><p>打穿了《吸血鬼爬行者》，确实是不错的游戏，正反馈很强，10h 的超绝体验，每天一两把很舒服。FF7 Remake 玩到一半弃坑了，虽然我很喜欢爱丽丝的演出，但这个流程真的是又臭又长，导致我完全没有什么欲望去打下一部。然后最近没啥想玩的游戏了，唉。还好有猎人，都更新到 413 话了，这个叙事节奏真好，前天晚上甚至梦到了猎人。</p><p>又是大小周加班的一天，正好写写本 blog. 说实话最近在做的 AI 导演项目，虽然是有趣，也算是遇到了一些问题，比如做到现在，觉得很难再以低成本做出让人眼前一亮的效果了（受制于工期和算法的效果）；比如其实从几个相关的 partner 那边接到的期望和反馈有些区别，需要我自己想一想方向和人力安排。说实话我现在有点逃避这个思考的过程吧，我知道很重要，但总是下意识会不去想，把自己扎进实现中去，concrete 的代码、实现、优化给人一种安心的感觉——我在产出东西。然后正好在 X 上刷到一个帖子，是我很喜欢的一个博主的一段话，我贴在这里：</p><p><img src="&#x2F;Assets&#x2F;log&#x2F;can_you_own_this.png" alt="png" loading="eager" decoding="async" width="2162" height="1746"></p><p>Own 一件事情确实是很难的，截图这里主要还是 focus 在技术讨论上，其实挺全面了。比如我接到一些对我的项目的需求，它合理吗，有必要吗，急吗，要和其他人同步吗，人力怎么安排，加人可以 scale 吗，等等。虽然我现在手下也没人，只有我自己这个人力以及俩算法好哥们，但我能感觉到这种张力。慢慢学吧，说不定过一个月这个项目就不用考虑这么多了，进入日常维护然后下一个了，害。</p><hr><ul><li><p>OpenAI 的 GPT 5.6 系列模型正式发布了，Meta 发了 Muse Spark 1.1，SpaceXAI 发了 Grok 4.5，军备竞赛啊，就等你了 Gemini，不能只发个 <a href="https://arxiv.org/pdf/2607.02770">Gemma 4 Technical Report</a> 啊。</p></li><li><p>Perplexity 的 CEO <a href="https://x.com/AravSrinivas/status/2075226438228402178">Aravind Srinivas</a>: <code>We’ve been post-training a version of GLM that is trained to escalate to a frontier model inside the Computer harness.</code> </p></li><li><p>Anthropic 的新的可解释性研究也很有趣，我是看不懂这个 J-Space 的数学，但这里有关于 Qwen 的实验可以玩玩 <a href="https://www.neuronpedia.org/qwen3.6-27b/jlens">Jacobian Lens – Qwen3.6-27B ｜ Neuronpedia</a>.</p></li><li><p>最近总感觉自己没深度学啥东西，脑子要生锈了，就回去复习了下基础知识先，先从 3Blue1Brown 的视频开始：<a href="https://www.youtube.com/watch?v=9-Jl0dxWQs8">How might LLMs store facts</a>，<a href="https://www.youtube.com/watch?v=iv-5mZ_9CPY&t=7s">But how do AI images and videos actually work</a>.</p></li><li><p>另外就是深度学习了下上次提到的 <a href="https://microsoft.ai/pdf/mai-thinking-1.pdf">MAI-Thinking-1: Building a Hill-Climbing Machine</a>，很多看不懂的地方，但能看到这么详细的 cookbook 是真的不错啊。几个印象：1，Scaling Ladder 的方式，很严谨；2，收集、清洗、去重数据真是麻烦，数据配比也很有讲究：<code>Target = 0.5×Coding + 0.175×STEM + 0.175×Math + 0.1×General knowledge + 0.05×Multilingual</code>；3，顺序，pre-training，mid-training，然后 RL 里面也是先训练三个专家模型出来，然后用 SFT 来 distill 到一个模型，再最后 RL 一下。还是要多学习啊。</p></li><li><p>既有技术讨论，又火药味浓浓的论战：Jarred Sumner 写了 <a href="https://bun.com/blog/bun-in-rust">Rewriting Bun in Rust</a> 以及 Zig 作者 Andrew Kelley 的回应 <a href="https://andrewkelley.me/post/my-thoughts-bun-rust-rewrite.html">My Thoughts on the Bun Rust Rewrite</a>. 说实话自从我比较关注 AI 这块之后，已经完全不太关注语言圣战了，啥语言合适 + AI 啥语言强我就用啥哈哈。不过这讨论里面还是有一些有趣的东西的，比如即使是 Fable + 比较完善的 test suite，写这种大项目也是 <code>Mechanically port every .zig file to a .rs file, matching the PORTING.md and LIFETIMES.tsv</code>，而不是放飞让 AI 直接去写；以及这里算账：<code>Pre-merge, this took 5.9 billion uncached input tokens, 690 million output tokens, and 72 billion cached input token reads — around $165,000 at API pricing. By hand, I think this would&#39;ve taken 3 engineers with full context on the codebase about a year... We never would&#39;ve done that.</code>再次印证了之前那句话：<code>Things that were impossible five months ago are now “just” Very Expensive.</code></p></li><li><p>与时俱进的 CMU 下半年要开 Agent 课程了，<a href="https://www.cmu-agents.com/#/schedule">11-768 · AI Agents</a>，可关注。</p></li><li><p>与时俱进的 SuperLuminal 发了 Linux 支持和 AI 支持，<a href="https://superluminal.eu/applications/ai/">Superluminal AI Support | Data-Driven AI At Superluminal Speed</a>。</p></li><li><p>发现的一个还不错的小 skill，独立游戏有用 <a href="https://github.com/0x0funky/agent-sprite-forge/tree/main">agent-sprite-forge: Agent Skill for generating 2D sprite sheets and map, transparent PNG frames, and animated GIFs from prompts.</a></p></li><li><p>tison 哥的新文章，力荐，<a href="https://mp.weixin.qq.com/s/UEnHM0-NWTEt31oSJ-IMNw">夜天之书 #120 掉进兔子洞：开源作为生活方式</a>。</p></li><li><p>传统技术，<a href="https://maskray.me/blog/2026-06-27-a-deep-dive-into-smallvector-push-back">A deep dive into SmallVector::push_back | MaskRay</a>；这个也不错，<a href="https://discourse.llvm.org/t/rfc-copysanitizer-csan-detecting-unneccessary-object-copies-at-runtime/91038">CopySanitizer (CSan): Detecting unneccessary object copies at runtime - IR &amp; Optimizations - LLVM Discussion Forums</a></p></li><li><p>云风大佬又在 X 上“引爆”了一场关于微信数据存储方式的<a href="https://x.com/cloudwu/status/2071533904977428611">论战</a>，说实话讨论技术还挺有趣的。不过就我观察，其实很多网友都没看完两方的全部言论就开始喷了，我就 emmmm，反正我也不懂，就学习吧。</p></li><li><p>股市就更有趣了，我又因为一些脑子上头的原因，满仓吃了半导体的大暴跌还没跑。仿佛是我刚体会到半导体要跌了再买并付诸实践，市场就教育我抄底是有概率会死的哈哈。至少我对自己的耐受线有一个大概的估计了，基本就是亏损 10-20% 的时候，会开始一直想这个事情，情绪不稳。所以为了我晚上能睡好，要果断止损；因为会果断止损，买入点一定是要选好，延伸形态下买入一定要慎重。</p></li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/07/11/curiosity_log_14/</id>
    <link href="https://jsjtxietian.github.io/2026/07/11/curiosity_log_14/"/>
    <published>2026-07-11T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>读不懂普鲁斯特，但读完了《从荷马到古希腊抒情诗》，开始下一个征程：刘象愚翻译的《尤利西斯》。确实是一直想读的一本书，但读着才发现确实难读，符号密度过大，一不留神就不知道作者在说啥了，当然留神了也会很痛苦。极为依赖注释，不然寸步难行。浓浓的爱尔兰氛围、希腊、圣经、文学元素等等]]>
    </summary>
    <title>Curiosity Log 14 - Can you own this</title>
    <updated>2026-09-24T07:25:43.274Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
      <![CDATA[<p>mwish 前阵子送了我一本《营养学》，最近睡前不想看美股（跌麻了）就没事翻翻，还挺有意思的。翻到运动营养学那边说其实比如 30 分钟的跑步完全没必要喝市面上的那种运动饮料，深有感触。我以前减肥的时候，或者说想减肥的时候，工作日都会在公司跑步机跑 4-5km，但我会带着一瓶运动饮料去，晚上还喜欢喝椰子水。然后我和 Gemini 老师聊健身的时候，顺便问了下椰子水这个事情，才意识到我不仅应该只喝白水，而且不该晚上喝这种会升糖的饮料。现在又在营养学这本书里看到，也算是验证了 AI 的观点。扯远一点说，有了 AI 的话，看这种科普书还有价值吗？我想是有的，但价值不仅仅是在知识传递了。优质的科普书更像是一份经过人工审核过的优质地图，AI 则是一个十分有耐心、知识渊博但不会主动关心我的老师，我可以从地图中发现我感兴趣的事情，去找老师请教。但，减肥还是好难。</p><p>端午三天都在躺着（广州这个天气啊），打完了 007，当然有很多小缺点，但瑕不掩瑜，确实有小时候看 007 的感觉，那个味对了，弄得我都想去玩杀手系列了；也体验了下《Order of the Sinking Star》的 Demo，很喜欢这个美术和音效，但我确实这脑子不太适合推箱子也是真的。最近上班压力越来越大，真的没啥心思去继续普鲁斯特的文学批评了，《普鲁斯特的空间》《普鲁斯特与符号》当然是好书，但我最近脑子真不够用了（也和最近几年越来越不喜欢很后现代的解读有关）。这时候我一般就回到古希腊，虽然这次不是荷马，是回到了赫西俄德，《神谱》《工作与时日》，慢慢读吧。</p><p>说到上班，最近又开始大小周了，其实今天就是在周六上班的时候写的这份 Curious Log. 仔细想想在 Garena 的三年只有一次周六被迫去公司半天加班，果然离开了才发现前司的好吗（就不说以前在 ApexM 的时候了，那时候强度可太大了）。作为一个摸鱼高手 + 一个不喜欢被迫做事的人，只能表演上班了！事情当然是有的，可惜我就是不想干，保护自己的身体健康和情绪可太重要了。不过我确实在让 AI 做点 side quest（我咋感觉 CC + dsv4 pro 体验很一般呢，不过可能是我 key 的问题，需要连着官方服务排查一下），就看抽卡能不能成功了。</p><p>猎人都更新 411 话了，生活还是很有希望的！</p><hr><ul><li><p><a href="https://openai.com/index/previewing-gpt-5-6-sol/">Previewing GPT-5.6 Sol: a next-generation model</a>，这起名字也是好起来了，Sol,  TErra, Luna. METR 的 <a href="https://metr.org/blog/2026-06-26-gpt-5-6-sol/">评测</a> 也挺有趣的：<code> METR observed substantial situational awareness and reasoning about the evaluation environment.</code> AI 知道你在测试它 hh.</p></li><li><p><a href="https://arxiv.org/abs/2604.17121">The Topological Trouble With Transformers</a>，我觉得很有洞见的一篇文章，里面举的例子很有意思：<code>In a standard decoder, activation flows strictly upward. If a model resolves a complex concept (like &quot;river bank&quot;) at layer 12 in step T, step T+1&#39;s early layers cannot access it. The model must rebuild the state from raw history, leading to logical flips.</code>  对于一个多义词 bank，可能模型在第 12 层确定了它是岸边那个 bank，但对于前几层来说，这个信息是没法往下传递的，如果后面又出现了 ATM 啥的，可能前几层网络就会认为这是银行那个 bank，造成混乱：<code>Although the transformer’s feedforward design has expanded the limits of context-based retrieval, its topological structure remains fundamentally at odds with the iterative nature of state tracking.</code> 从这个角度上看也可以解释一小部分为什么模型越大越强吧，以及 COT 为啥有用，当然作者也是”批判“了 COT 的：<code>Allowing a model to talk to itself, whether in natural language or latent space, sends signals from deep in the transformer to shallow layers, thereby propagating state forward... However, the reliance on intermediate outputs to track micro-state may perform wasteful computation steps and unnecessarily consume the context window.</code></p></li><li><p><a href="https://arxiv.org/abs/2512.15567">Evaluating Large Language Models in Scientific Discovery</a>，神句：<code>Shared failure modes among top-performing LLMs. When comparing the top performers across different providers (i.e., gpt-5, grok-4, deepseek-R1, and claude-sonnet-4.5), we observe that their accuracy profiles are highly correlated, which tend to rise and fall on the same scenarios. Moreover, top-performing LLMs frequently converge on the same incorrect set of most difficult questions, even when their overall accuracies differ.</code></p></li><li><p><a href="https://developer.nvidia.com/blog/build-on-device-ai-companions-with-the-nvidia-ace-game-agent-sdk-and-unreal-engine-5-plugins/">NVIDIA ACE Game Agent SDK</a>，感觉很不错欸，而且 API 是我一直关注的 <a href="https://x.com/SheriefFYI/status/2066971180989604026">Sherief, FYI</a> 大佬设计的。东西是真的多，Agent、Chat、RAG、ASR、SLM、TTS，应有尽有。</p></li><li><p><a href="https://x.com/EngramLab/status/2069465879696576844">Introducing Engram: Scaling compute on your context</a>，做定制模型的来了：<code>we start from strong pre-trained models and spend training compute on the context you care about...Our north star is a single training algorithm that can absorb arbitrary amounts of data into a model that gets continually better. We currently run this process on all of our company data every day, but are moving towards retraining every hour, and eventually, every minute.</code></p></li><li><p>Midjourney 很神奇的项目，<a href="https://www.midjourney.com/medical">Midjourney Medical</a>；这个也不错，从 <a href="https://github.com/hanxiao/searchbox">searchbox</a> 看到 <a href="https://github.com/hanxiao/dataroom">dataroom</a>，Jina 的老大好活跃：<code>In my view, search is test-time compute (TTC): you wire trained embeddings, rerankers, multi-vector retrievers, query expanders into a pipeline at test-time to squeeze out relevancy. Don&#39;t scale TTC, say a keyword search hands you the answer, and it&#39;s probably not good enough. Scale it, say add embedding search then filter with a reranker, and you most likely get a better one.</code></p></li><li><p><a href="https://arxiv.org/abs/2512.07783">On the Interplay of Pre-Training, Mid-Training, and RL on Reasoning Language Models</a>，好想自己做研究！先从这个开始学吧，<a href="https://rlhfbook.com/course">RLHF &amp; Post-Training Course by Nathan Lambert</a>.</p></li><li><p><a href="https://x.com/antirez/status/2066236816261325224">antirez on X</a>: <code>If you need AI to do a search for you in the real world, ds4-agent is basically SOTA... In MacOS I run the browser the first time it is used with -g, create each tab in background with CDP, so basically you never see the window unless you don&#39;t click in the icon, but it is a real browser without limitations. Everything works: YouTube comments can be fetched, Google searches, ..., btw everything is in ds4_web.c</code>.</p></li><li><p><a href="https://geohot.github.io//blog/jekyll/update/2026/06/19/the-doom-justifies-the-valuation.html">The doom justifies the valuation</a>，虽然我确实很喜欢 GLM 那种偏技术的 blog，但我也不讨厌 Anthropic 那种偏思辨的 blog 风格，看看人家取名字多有水平：Haiku, Sonnet, Opus, Fable, Mythos… 当然 OpenAI 也赶上了。</p></li><li><p><a href="https://zhuanlan.zhihu.com/p/2052472619958527207">礼崩乐坏的时代：）</a>，挺好的回顾：<code>讲道理，看上去只要TSMC忠义无双还是满产不烧厂，传统电子消费就会继续被放血去喂AI这个吞金兽。就得继续冲DRAM的股票。只要算力芯片不停放量，存储涨价的逻辑就不会反转，存储标的长期利好。。。嗨，这世界大抵是病了，Logic拼命向前跑，却成了DRAM大宗商品周期的高级打工人。</code> 但反过来说，美光回怼苹果也有道理，当年你对内存压价压那么狠，早知如此，何必当初啊。</p></li><li><p><a href="https://www.anthropic.com/news/introducing-claude-tag">Introducing Claude Tag \ Anthropic</a>，这不是 <a href="https://raft.build/">Raft - Where humans and AI agents build together</a> 么！</p></li><li><p><a href="https://arxiv.org/abs/2606.05750">Three Years of r&#x2F;ChatGPT: Societal Impact Evaluations from Social Media Data</a>，感觉 AI 的影响确实足够，真的是很适合各行各业去研究，社会学、传播学、人类学等等。当然还有这个，<a href="https://x.com/barrowjoseph/status/2067993371541492025">New paper: every law in America is technically public. But not really, until now</a>，笑死我了：<code>California and Florida, you need to get your shit together so people can actually understand your laws! And Ohio and West Virginia, wtf is going on with how you run people&#39;s lives??</code></p></li><li><p>到游戏，本周大新闻就是，Sandy Petersen 对 Quake3 的 <a href="https://x.com/SandyofCthulhu/status/2069592209645785294">复盘</a>，里面有 <code>We worked long and hard, and I think it broke us spiritually</code>；然后 John Carmack 也出来了：<code>I pushed everyone too hard. I didn’t appreciate how maturing companies need more slack, and that running people at startup intensity constantly will wear them out... Sorry, Sandy.</code>  马斯克也评论说 <code>But Quake was an incredible game. Great products are not made without pain and extreme dedication.</code> 我想也是，虽然我很在意 WLB，但想办好事情，其实真的很难。</p></li><li><p>Kiaran Ritchie 直接说 <a href="https://x.com/kiaran_ritchie/status/2069135923108008009">You’re all doing IK solvers wrong</a>，我不太懂这一块，看着挺有道理的，更有意思的是，AI 时代，直接让 AI 搞个 demo 验证下就行，比如 Mike Acton 就做了 <a href="https://macton.github.io/single-chain-ik/">Single-Chain IK — Length + Direction</a>.</p></li><li><p><a href="https://zhuanlan.zhihu.com/p/2048571053698502907">从 5.9ms 到 1.0ms：一个 byte store 如何让 for 循环慢了 6 倍</a>，读了一半猜到是 load-store forward 的问题了，好文。</p></li><li><p>pgo 是真的好，msvc 终于有了，<a href="https://devblogs.microsoft.com/cppblog/boosting-adobe-photoshops-performance-with-msvc-and-spgo/">Boosting Adobe Photoshop’s Performance with MSVC and SPGO</a>.</p></li><li><p><a href="https://x.com/itsreallyvivek/status/2064686372737454155">how to be good at research</a>，又 cue 到 hamming.</p></li><li><p>项目里有一些从视频提取信息的需求，同事用上了这个 <a href="https://github.com/facebookresearch/vggt-omega">CVPR 2026 Oral VGGT Omega</a>，感觉真是不错的工作。</p></li><li><p>最近股市震荡好厉害，我不太适合在这个环境里赚钱，Dell 和 Apple 都震破我止损了，果断斩仓。</p></li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/06/27/curiosity_log_13/</id>
    <link href="https://jsjtxietian.github.io/2026/06/27/curiosity_log_13/"/>
    <published>2026-06-27T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>mwish 前阵子送了我一本《营养学》，最近睡前不想看美股（跌麻了）就没事翻翻，还挺有意思的。翻到运动营养学那边说其实比如 30 分钟的跑步完全没必要喝市面上的那种运动饮料，深有感触。我以前减肥的时候，或者说想减肥的时候，工作日都会在公司跑步机跑 4-5km，但我会带着一瓶]]>
    </summary>
    <title>Curiosity Log 13</title>
    <updated>2026-09-24T07:25:43.274Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
      <![CDATA[<p>读完《追忆似水年华》之后，趁着最近两周不咋忙，赶紧集中阅读《追寻普鲁斯特》和《普鲁斯特先生》，普鲁斯特的人生确实和他的书一样有趣。读完觉得普鲁斯特活得很“仙”，真是上帝送给世界的礼物啊。</p><p>工作上也很，有趣吧。虽然我在名为 Agent 组的地方，好像也没在做 Agent，更像是：1，先揣摩上面的（略微模糊的）意思，感受要做的方向是啥；2，和人讨论讨论，想想怎么细化成可执行的路径；3，看看有哪些 block 住的技术难题，我和小伙伴先分别去试试水看看咋样；4，每日开会讨论对齐，定个小节点开始推进。真的是走一步才看一步，用得到 Agent 当然很好，但主要落脚点一定是要在能让项目组用上 + 能切实提高项目效率上。主要是似乎也没那么多时间真的去从头思考下整体的架构，毕竟项目那么忙，ROI 很重要。我当时是想做点深度一些的 Agent 的项目的，但有几个问题要能解决——1 是，Agent 真的是最好的解决方案吗，比如针对某些痛点，是不是就去做传统的工具优化更好；2 是，我有那么多时间去好好优化它到一个很好的效果吗，怎么去和上面要更多的时间，那就要有惊艳的 demo 出来去争取，那就更急了；3 是，作为特攻队，我真的有机会一直去做一个方向吗，整体项目组的痛点其实是会随着不断的解决而转移的，解决了 80% 之后 ROI 就没那么高了，上面怎么想也很重要。还好小伙伴们很靠谱，每天这样如履薄冰地思考也很有趣倒是。</p><hr><ul><li><p><a href="https://www.anthropic.com/news/claude-fable-5-mythos-5">Claude Fable 5 and Claude Mythos 5</a>：<code>Fable 5 is state-of-the-art on nearly all tested benchmarks, with exceptional performance in software engineering, knowledge work, scientific research, and vision. The longer and more complex the task, the larger Fable 5’s lead over our other models.</code> <a href="https://www-cdn.anthropic.com/d00db56fa754a1b115b6dd7cb2e3c342ee809620.pdf">System Card</a> 里有一些有趣的论述，比如<code>the model is not close to substituting for our Research Scientists and Research Engineers, especially relatively senior ones</code>, 还有 <code>capability is continuing to improve at roughly a constant rate, and it&#39;s not further accelerating.</code> 当然，现在用不了，也是很好笑了。</p></li><li><p>微软的 MAI-Thinking-1，带了非常详细的<a href="https://microsoft.ai/wp-content/uploads/2026/06/main_20260602_2.pdf">报告</a>；说到微软，<a href="https://blogs.windows.com/windowsdeveloper/2026/06/02/build-2026-furthering-windows-as-the-trusted-platform-for-development/">Build 2026: Furthering Windows as the trusted platform for development</a>，也是大量的 AI 内容，还有 Aion 1.0 Instruct 和  Plan 两个端侧模型，还是和 <a href="https://x.com/UnslothAI/status/2061925637892297122">Unsloth AI</a>合作的！</p></li><li><p>GLM 发了 5.2，Kimi 发了 K2.7 Code，谷歌的 <a href="https://blog.google/innovation-and-ai/technology/developers-tools/introducing-gemma-4-12B/">Gemma 4 12B</a>，另外刷到了这个有趣的模型 <a href="https://huggingface.co/nvidia/LocateAnything-3B">nvidia&#x2F;LocateAnything-3B</a>，足够小，瑞士军刀一样的存在，适合当眼睛，配合其他的模型作为脑子。</p></li><li><p><a href="https://developer.nvidia.com/blog/nvidia-nemotron-3-ultra-powers-faster-more-efficient-reasoning-for-long-running-agents/?linkId=100000424980294">NVIDIA Nemotron 3 Ultra Powers Faster, More Efficient Reasoning for Long-Running Agents</a>，而且如何训练都在 <a href="https://github.com/NVIDIA-NeMo/Nemotron/tree/main">Developer Asset Hub for NVIDIA Nemotron</a>.</p></li><li><p><a href="https://x.com/patpcj/status/2063298457398636570">Patrick Jiang</a>:<code>I tried a simple idea: externalize the search state, then train the model to use that harness. The result is Harness-1: a 20B search agent that can match or even beat much larger frontier AI on hard long-horizon search tasks.</code> 喜欢喜欢，然后作者也用相同的 benchmark 测了 Fable-5&#x2F;Mythos，结果<code>it’s the new SOTA. The performance gap is real.</code></p></li><li><p><a href="https://blog.google/innovation-and-ai/models-and-research/gemini-models/gemini-live-3-5-translate/">Gemini 3.5 Live Translate is here</a>，总看到有人会说巴别塔倒了，包括 X 上最近开始自动翻译各国推文了，也是很有趣的社会观察。说到 X，想到 Grok Build，至少 <a href="https://x.com/lemire/status/2064412388275671313">Daniel Lemire</a> 大佬是在夸的。</p></li><li><p><a href="https://x.com/hxiao/status/2066000709695513053">Inference compute is becoming more important, and weights relatively less so</a>.</p></li><li><p><a href="https://mp.weixin.qq.com/s/sIB3f3_OeeUgMPlQ55-99Q">我们花了 1000 美金，问了 16 家 AI 公司，27 个大模型 29700 次：你是谁</a>：<code>Anthropic 、 OpenAI 、 Google 是明显的身份净流入方。尤其 Anthropic ，被冒认 607 次，自己冒认别人 59 次，净值 +548 。 OpenAI 和 Google 更夸张：被冒认很多次，但自己几乎不冒认别人。另一端则是 Tencent 、 Doubao 、 z-ai 、 Kwai 。它们把大量跨厂自称送向了上游。</code> 当然一个模型自称 Claude、ChatGPT、Gemini，不等于它一定蒸馏过这些模型，只是还是很好玩。</p></li><li><p>很有趣的项目，<a href="https://github.com/hanxiao/omni-macos">omni-macos</a>，用 jina-v5-omni 做的本地多模态搜索：<code> text query finds matching documents, code, PDFs, images, audio, and video together, because everything is embedded into one shared vector space.</code> 正在做游戏的我表示，那骨架数据、特效数据呢哈哈。</p></li><li><p><a href="https://x.com/polynoamial/status/2064210146558136827">Implications of Large-Scale Test-Time Compute</a>：<code>We should change LLM evaluations to account for that by measuring performance vs tokens, cost, or time.</code> 确实吧，尤其是 Fable 那么贵。</p></li><li><p><a href="https://x.com/pushmatrix/status/2064722585019969727">Daniel Beauchamp</a>：<code>Everyone&#39;s talking about AI-generated HTML. But have you tried giving your sites a zero-config API for saving data, file storage, AI, websockets, etc?</code> 确实，在 vibe 一个网页很快的基础上，公司内的基建做好的话，能大大解放生产力啊。</p></li><li><p><a href="https://x.com/lemire/status/2062715526636253385">Students just have AI do their programming assignments. They seem to no longer do any work. It is just pure AI. I am not joking. Students complete an entire course, and then end up not being unable to write a 3-line function</a>，不管如何，家庭作业布置点编程题目这种形式确实应该与时俱进地优化掉了吧。</p></li><li><p>Mike Acton 都亲自下场做 <a href="https://github.com/macton/nagent">agent</a> 了吗：<code>nagent is a small reference implementation. It shows what terminal &quot;agent-like&quot; workflows are when you describe the mechanics instead of the metaphor... The agent is not the thing. The data is the thing.</code> </p></li><li><p>引用大全是吧，<a href="https://x.com/itsreallyvivek/status/2062924410588406118">some notes on getting into frontier ai labs</a>：<code>Richard Hamming often argued that great scientists distinguish themselves less by intelligence than by working on important questions... Herbert Simon observed that intelligence is constrained by bounded rationality: the world contains far more information than any individual can process</code>；还有这篇引用了本雅明，<a href="https://redfloatplane.lol/blog/17-why-share/">Why share</a>：<code>Do drive-by LLM remixes (“Rebuild this but with X in place of Y”) have aura, and can you tell the difference? Why share something in the first place if the aura of the work you spent time creating can be stripped away or diluted by online commentators in a matter of moments to suit their taste? And most fundamentally - can work created with LLMs even be considered to have an aura, and, to what degree *can* LLMs be used before the lack of aura is palpable?</code></p></li><li><p><a href="https://x.com/addyosmani/status/2064127981161959567">Loop Engineering</a>，我每次都想不到这么优雅的词。</p></li><li><p><a href="https://newsletter.semianalysis.com/p/finding-miscompiles-for-fun-not-profit?_gl=1*mhopti*_ga*MTY1NDExMjk2Ny4xNzc2MTIzOTQ1*_ga_FKWNM9FBZ3*czE3ODA2MDYwMzckbzYxJGcwJHQxNzgwNjA2MDM3JGo2MCRsMCRoOTczMjUwMzcy">Finding Miscompiles for Fun, Not Profit</a>，好文，其实用 fuzz 或者 AI 扫 bug 也不算新鲜事，但延伸的想法很有趣，能开 50 个 agent 去找代码库的 bug 意味着什么：<code>Things that were impossible five months ago are now “just” Very Expensive. A corollary is, if you don’t have the budget, you’re operating in a smaller part of the possibility space than those who do.</code>   </p></li><li><p><a href="https://x.com/rasbt/status/2063649136323252397">Do AGENTS.md Files Actually Help Coding Agents?</a>，我一直觉得 Agents.md 要手写，最近做的一个项目还加了个 DECISION.md 记录重要技术决策。</p></li><li><p>学吧，蛮好的 Infra 爹写的入门文章：<a href="https://blog.xiangpeng.systems/posts/how-to-llm-inference/">A system programmer’s guide to LLM inference</a>；学吧就，<a href="https://chinmaykarkar.com/blog/OPD_blog/">The Imitation Game: State of Policy Distillation in Language Model training</a>，<a href="https://x.com/ostensiblyneil/status/2063006720616734835">Improving LM Studio’s MLX Engine for Agentic Workflows</a>，以及这个呼应 OpenAI 那篇文章的 <a href="https://goblins.mchen.workers.dev/">how to train your goblin</a>.</p></li><li><p>Jeff Dean 在 the University of Washington Allen School 毕业典礼上分享的三个建议：<code>continuously learn new things, utilize modern tools to scale your capabilities and bring ideas to life, work on things that really matter to you and to the world.</code></p></li><li><p><a href="https://medium.com/@tridge60/rsync-and-outrage-d9849599e5a0">rsync and outrage</a>：<code>I’m retired (though my wife may dispute that!) and I’d rather be out sailing than working on rsync security issues, so I have reached for several AI tools to help with what needs to be done.</code> 我也想退休啊，活儿给 AI 干就好。</p></li><li><p><a href="https://zhuanlan.zhihu.com/p/2046736538218784473">用网页控制虚幻引擎：一种全新的 UE 工具开发思路</a>，才发现作者是我老熟人了，不过这个思路确实很好，我之前也算是在实践这个吧。</p></li><li><p>Sebastian Aaltonen 发了一个新的用 AI 生成美术资源的游戏原型 <a href="https://x.com/SebAaltonen/status/2063953367718576249">Demo</a>，看评论区争议还不小。不过我关注的是制作侧，评论里他提到：<code>Raw AI generated assets from all the generators we have tried are horrible. Thousands of tiny UV islands. Doesn&#39;t LOD well at all. We remesh AI source assets to improve the topology. Then we reproject the high mesh geometric details on medium poly asset and bake new normal maps.</code> 确实，管线要弄好啊。</p></li><li><p>传统技术，老资历 ECS，<a href="https://www.youtube.com/watch?v=73Do0OScoOU&t=1s">The First Entity Component System - An Interview with Marc LeBlanc</a>，很有趣；<a href="https://x.com/lemire/status/2063358266885685710">How much do amd64 microarchitecture levels help in Go</a>；游戏优化指南，<a href="https://x.com/iced_coffee_dev/status/2064364537969529036">Here’s how to go from drawing a few hundred trees to virtually unlimited in Three.js, step by step</a></p></li><li><p><a href="https://justinjackson.ca/hard-thing">Do the hardest thing</a>，继续每周鞭策拷问自己，我在做的事情是最难的吗。</p></li><li><p>终于借着读完《Think &amp; Trade Like a Champion》的机会，push 自己把券商里的交易记录都导出来，让 codex 做了个看板来辅助我分析。我之前有这个想法，但是总是下意识延迟这件事情，可能是不敢面对自己吧，总是想沉溺于自己在赚钱的幻想中。唉，只能说数据是无情的。我发现我现在处于一个越学越混乱的过程，或者说知识的诅咒吧，学了反而让我畏首畏尾的。我的品味还行，但是操作一塌糊涂，唉，没亏本简直是奇迹啊。</p></li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/06/14/curiosity_log_12/</id>
    <link href="https://jsjtxietian.github.io/2026/06/14/curiosity_log_12/"/>
    <published>2026-06-14T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>读完《追忆似水年华》之后，趁着最近两周不咋忙，赶紧集中阅读《追寻普鲁斯特》和《普鲁斯特先生》，普鲁斯特的人生确实和他的书一样有趣。读完觉得普鲁斯特活得很“仙”，真是上帝送给世界的礼物啊。</p>
<p>工作上也很，有趣吧。虽然我在名为 Agent 组的地方，好像也没在做 A]]>
    </summary>
    <title>Curiosity Log 12</title>
    <updated>2026-09-24T07:25:43.274Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
      <![CDATA[<p>历经整整三个月，我终于读完了《追忆似水年华》。说实话一开始并没有想读完全部的，当时觉得大概也就读完第一本和第二本就可以了，主要是体会一下。但既然当时已经读完两本，也暂时没有什么其他更想读的，就继续吧，也还好巴尔贝克的章节让我觉得更有读下去的动力了。再后面就是某种自我强化了，虽然从第四本开始阅读上确实稍有折磨，但是也能坚持下去读完，直到《重现的时光》。</p><p>所幸一路都有很有趣的细节发现，比如在第五章中间，作者突然写道：<code>我让叙述者取了个跟本书作者一样的名字</code>。虽然我知道作者一直在玩叙事视角转换的游戏，一会儿叙述者、一会儿当时的马塞尔，但如此直白的描述在当时应该还是挺先锋的存在。普鲁斯特的感受力是真的很强，比如他说火车与汽车：<code>汽车可不同，它把我们带进一座城市，没有这么神妙，因为我们下火车首先是从整体上看这座城市，这个整体，城名作了概括，顾名思义含有观众闭门造车异想天开的色彩。而汽车则把我们带进大街小巷里转，不时停下向居民打听一下情况</code>，汽车带来的是一种时空的连续性与展开感。而如今我们对汽车早已习以为常了，很难再次产生这种感觉。我想起了 <a href="https://book.douban.com/subject/30199056/">铁道之旅</a>，说实话我只能想起它，但我已经忘光了这本书的内容，唉，这就是岁月的痕迹吗。读最后一卷一直是这个感觉，书中各种角色的死亡或者老去，马塞尔父母的隐身，如同化妆晚会一样的社交聚会。</p><p>另外工作上也有些小的插曲吧，我只能说我现在有点点后悔转到所谓的 Agent 组。一来好像也没在做 Agent，倒不是说做的事情没有什么价值，还是有趣的，只是更像是工具组的范畴；二来这个顶头上司确实好像脾气有点不稳定，本周一开会被喷一次，周三又见他在群里发泄情绪；另外他的进度管理似乎主要是催促，每天在群里催今天能做完吗，上压力，我还挺讨厌的。并不是我不理解他的压力有多大，大家总说上班是窝囊费也就是这个意思，有时候确实要承接一些上面的情绪。但咋感觉应该反过来？我以为我脾气够不好了，还有更不好的哈哈哈哈。可能这也和领导是发行出身有关吧，他缺少一些技术这边的思维，以前是有 CTO 挡着一波转化为可落地的步骤和任务，现在我直面他了，确实有一些有趣的感觉。当然我理解偶尔的加班赶进度很正常，只是，有这样的上司，太怕他把大家加班赶出来的进度当日常进度了，毕竟啥想法都要么是今天要，要么是赶紧给个时间表。然后又要想办法和他解释我们做的 demo 真的是个 MVP，离一个可用的产品还有很多距离，需要更多的时间。唉，我在连着两次被上司晚上 10 点@之后，都对企业微信有点 ptsd 了，真的下班之后完全不打开，直接治好了我没事喜欢周末打开企微的毛病。</p><p>我可能不太方便说我做的事情具体是啥，但咋说呢，有过一次一周连续加班，并且周四直接加班到半夜 2 点 30 的经历之后，我感觉我似乎是又想明白了一些东西。还是感谢 Garena 啊，把我保护得太好了。最重要的领悟可能是，没必要带着怒火上班，其实想干就干，不想干就按时下班休息呗，能咋样呢，有离职想法的也不只我一个倒是。主要还是会逼我思考下，我认为最重要的是什么，目前来看最重要的还是身心健康，我这个人一旦受累就脾气巨差，所以还是少加班为好，既是保护自己，提高工作效率，也是保护同事。赚钱当然很重要，财富自由再怎么都需要本金。能帮助他人的感觉也挺好，这也是为什么我一直不排斥做工具的原因，尽管可能显得技术不足。还是要开心呀，不管这个开心从哪里来 —— 收入高 &#x2F; 有成就感 &#x2F; 有帮助他人的感觉 &#x2F; 可以按时下班陪对象等等，如果都没有的话，那只能摆烂等 N + 1 了。另外就是，如果现在离开游戏行业，大概还来得及吧，那能去哪儿呢，有什么行业是符合有趣、有复利、有杠杆的呢，好难啊。先干着，慢慢想吧，想了总比不想好。如果自由了我是想开书店的，但等自由了再说吧。其实现在裸辞也饿不死，但确实，不会这么跌宕起伏，和同事八卦还是有趣的。</p><p>另外关于这个 Curiosity Log，我觉得也许可以决定稍微减少一些数量，增加一些质量。或者说，给出的尽量都是我认为有洞见的，并且我可以对为何我认为有洞见说得更详细些。</p><hr><ul><li><p>Claude Opus 4.8 发了；Gemini 3.5 发了，这里有一些历史介绍，<a href="https://www.youtube.com/watch?v=NQczevdpxq0">Gemini Co-Lead on World Models, RL’s Next Domains &amp; Continual Learning</a>；带着的 <a href="https://googlebook.google/">GoogleBook</a> 还挺有趣的。</p></li><li><p>llama.cpp 支持 MTP (Multi Token Prediction) 了，好啊好。还支持了<a href="https://reeselevine.github.io/llamas-on-the-web/">WebGPU </a>，太牛了，这篇 demo 的 blog 也很有意思，感觉能直接上网页的话，很多交互形式都被打开了。DwarfStar 的开发还在继续，看看这篇 <a href="https://antirez.com/news/167">Distributing LLM inference in DwarfStar</a>。</p></li><li><p><a href="https://x.com/rachelnabors/status/2057123652626256360">How to use evals and prompt engineering to ship a local model that matches frontier performance</a>，这个有洞见，讲作者怎么去选一个足够好的本地模型来完成一些总结、提取的任务。<code>1,Prove it’s possible; 2,Set success criteria; 3, Test from small to large; 4, Select the smallest model that gives acceptable responses for your use case.</code> 要 eval 就需要 <code>A “golden dataset” is a set of ideal outcomes to measure your model’s generated outputs against. Without one, you don’t have a measuring stick to compare different outputs against.</code> 后面针对实际的模型，Qwen2.5 因为幻觉被否了，Gemma 4 因为 latency 被否了，留下了 Llama 3.2b. 而且故事还没结束，后面还发现对这种小模型，给样例给它学最有用了：<code>Few-shot was the standout, with quality improving across every metric. Llama3.2b might not be good at following instructions, but it’s pretty good at imitating examples.</code></p></li><li><p>Amp 的这个 labs 挺有意思的：<code>For the companies we partner with: we win if and only if you win. We profit only through warrants unlocked if your stock appreciates considerably. We don&#39;t work with your competitors.</code> 亲身下场用 Agent 改变战局吗，有趣，以及这些<a href="https://amplabs.com/">宣言</a>。</p></li><li><p>Amp 联合创始人的访谈，<a href="https://www.youtube.com/watch?v=thMFsqe8kbQ">LLMs are killing Agent Harness</a>，洞见：传统软件有直观的产品反馈（比如放大标题能直接看到），而 AI 的交互是一个输入框，用户扔进任何错误的想法，产品都无法给出即时的“你做错了”的反向反馈。我也在想，其实 Harness 这个，稍微差点可能也暂时没法意识到。</p></li><li><p><a href="https://x.com/addyosmani/status/2059844244907696186">The Orchestration Tax</a>:<code>The real skill is designing the system around the one serial resource that cannot be cloned or parallelized. That resource is your attention.</code></p></li><li><p>关于记忆，<a href="https://arxiv.org/abs/2605.12978">Useful Memories Become Faulty When Continuously Updated by LLMs</a>：<code>Yet we find that such consolidated memories produced by today&#39;s LLMs are often faulty even when derived from useful experiences.</code></p></li><li><p><a href="https://malcat.fr/blog/benchmarking-llms-for-malware-triage-and-static-unpacking-with-malcat/">Benchmarking LLMs for malware triage and static unpacking with Malcat</a>，没想到这个任务上，Mimo 2.5 Pro 还挺能打的；另外，<code>the advertised cost per token is only part of the story. The final cost depends heavily on how many tokens the model burns internally for reasoning and how efficiently it uses tools.</code></p></li><li><p><a href="https://stratechery.com/2026/the-inference-shift/">The Inference Shift</a>，拆了下三个场景：训练、问答和 Agent，三个场景的性能需求不一样，合理。</p></li><li><p><a href="https://arxiv.org/abs/2605.22391">Epicure: Navigating the Emergent Geometry of Food Ingredient Embeddings</a>，好有意思，把食谱丢进去炼模型，观察食物的潜空间。</p></li><li><p><a href="https://brooker.co.za/blog/2026/05/18/whats-easy-whats-hard.html">What’s Easy Now What’s Hard Now</a>，我确实一直是这个观点，能被 feedback loop 的都能被大力出奇迹。</p></li><li><p><a href="https://magazine.sebastianraschka.com/p/recent-developments-in-llm-architectures">Recent Developments in LLM Architectures: KV Sharing, mHC, and Compressed Attention</a>，学吧</p></li><li><p><a href="https://x.com/addyosmani/status/2056078124346228860">Don’t Outsource the Learning</a>，so true. </p></li><li><p><a href="https://www.youtube.com/watch?v=xKZ_8ULR91Y&t=1s">Jane Street on GPUs, Trading, and Hiring: A Conversation with Dwarkesh - YouTube</a>，不再局限于热点代码的局部优化，而是开始从顶级科技巨头引进系统架构师来优化整体算力资源流转，有时候我也在想，还是要让自己的能力跟上这个 infra 的 scale，游戏始终是 2C 的，其 scale 和这种不是一个路数。</p></li><li><p>唉，<a href="https://x.com/deedydas/status/2055491938464489888">这里</a>提到：<code>Over the last 5yrs, a group of ~10k people - employees at Anthropic, OpenAI, xAI, Nvidia, Meta TBD, founders - have hit retirement wealth of well above $20M (back of the envelope AI estimation). Everyone outside that group feels like they can work their well-paying (but &lt;$500k) job for their whole life and never get there.</code> 我有时候也在想我会不会也有这种心态，会有吧，毕竟真的赚太多了，但就算能退休，我也不会退休吧。</p></li><li><p><a href="https://every.to/p/after-automation#ai-progress-creates-more-work-for-humans-not-less">After Automation</a>：<code>AI makes yesterday’s human competence cheap.</code> 我怎么就想不到这么优雅的表述呢，还有这个：<code>Benchmarks measure work inside a frame.</code> 社会学又在袭击我了。这个<a href="https://andrewsiegler.substack.com/p/alloways-antidote-to-baumols-cost">说法</a>也优雅：<code>AI substitutes for the fluent-middle of general cognition, which was the differentiator behind the cognitive-professional wage premium.</code> </p></li><li><p><a href="https://callmemapo.substack.com/p/ai-the-shadow-prince">AI, the Shadow Prince</a>，wow，把 AI 比作卡夫卡《审判》里的官僚机构，我爱卡夫卡。</p></li><li><p><a href="https://x.com/lemire/status/2057100010144006424">Daniel Lemire</a> 说 AI 编程：<code>AI will not turn most of us into software architects. What is happening is Cargo Cult Software development. Cargo cultism is a reference to Pacific Islanders who would copy the US military after the US was gone, in the hope of getting the goods that the US was providing.</code></p></li><li><p><a href="https://laurent.le-brun.eu/blog/a-history-of-ides-at-google">A History of IDEs at Google</a>，这个确实有意思，谷歌的基建是好啊。</p></li><li><p>我认同<a href="https://x.com/WillManidis/status/2057094527236665598">这个</a>，可是老板不认同啊：<code>“996” is a mass production / central planning approach to creation. it doesn’t work for inventing new things. it only works for cog like scaling of mechanical processes. great work doesn’t happen after 100 hour weeks, it only appears in tiny fleeting random moments, embrace that.</code></p></li><li><p><a href="https://zhuanlan.zhihu.com/p/2043536359558754931">未来影响游戏开发最深远的技术，第一是 LLM，第二是视频生成，3D 顶多排第三</a>。</p></li><li><p>来点传统技术，<a href="https://devblogs.microsoft.com/cppblog/introducing-sample-profile-guided-optimization-in-msvc/">Introducing Sample Profile Guided Optimization in MSVC</a>，终于来了吗；交互设计史，<a href="https://www.david-smith.org/blog/2026/04/29/maps-on-watchos/">Six Years Perfecting Maps on watchOS</a>；学习软件架构的好资源，<a href="https://matklad.github.io/2026/05/12/software-architecture.html">Learning Software Architecture</a>；Emoji + string 操作引发的 bug，<a href="https://george.mand.is/2026/05/my-favorite-bugs-invalid-surrogate-pairs/">My Favorite Bugs: Invalid Surrogate Pairs</a>；关于 Rust 的性能 slide，<a href="https://github.com/yugr/rust-slides">rust-slides</a>；</p></li><li><p><a href="https://www.frontiersin.org/journals/psychology/articles/10.3389/fpsyg.2023.1219945/full">Handwriting but not typewriting leads to widespread brain connectivity: a high-density EEG study with implications for the classroom</a>，高中以及之前我的日记都是手写的，现在是换成电子的了，也许偶尔来点 old fashion 的也不错。</p></li><li><p>因为加班的心态问题清仓了半导体，结果最近嘛，唉。让 Gemini 帮我对照这两篇访谈，<a href="https://x.com/chrisbarber/status/2054965791901319621">1</a> <a href="https://www.youtube.com/watch?v=FtmyIldrwLA">2</a>，让我的半导体相关观察清单加了很多个股进去，比如诺基亚、SMTC 等等。唉，上班耽误在牛市赚钱啊，各种意义上。</p></li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/05/31/curiosity_log_11/</id>
    <link href="https://jsjtxietian.github.io/2026/05/31/curiosity_log_11/"/>
    <published>2026-05-31T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>历经整整三个月，我终于读完了《追忆似水年华》。说实话一开始并没有想读完全部的，当时觉得大概也就读完第一本和第二本就可以了，主要是体会一下。但既然当时已经读完两本，也暂时没有什么其他更想读的，就继续吧，也还好巴尔贝克的章节让我觉得更有读下去的动力了。再后面就是某种自我强化了，]]>
    </summary>
    <title>Curiosity Log 11</title>
    <updated>2026-09-24T07:25:43.274Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
      <![CDATA[<p>最近因为直接转组了还挺忙，只能说慢慢来看这个活儿确实有趣吧，不急的话还挺享受的，队友也靠谱，可惜急急急。搞得我天天都很亢奋，静息心率直接 +10 了，这可不好，周末赶紧躺平。我也是摆烂了，CTO 让我们周六去加班的来着，我直接假装看不见，需要休息。</p><p>当然还是有盼头的，吹哥的《Order of the Sinking Star》出新的 trailer 了，期待，今年能玩到的好游戏是不少的；也抽空玩了好友 Woof 的作品《恶魔牌》，很有趣！更别提还可以等 GTA6 了。</p><hr><ul><li><p>继续大热，<a href="https://github.com/antirez/ds4">antirez&#x2F;ds4: DeepSeek 4 Flash local inference engine for Metal and CUDA</a>，作者也发了文章随便讲讲感想，几个点：<code>the release of a quasi-frontier model that is large and fast enough to change the game of local inference, and the fact that it works extremely well with an extremely asymmetric quants recipe of 2/8 bit, so that 96 or 128GB of RAM are enough to run it. And, of course: all the experience produced by the local AI movement in the latest years, that can be leveraged more promptly because of GPT 5.5</code>. 更触动我的是这个：<code>The last week was funny and also tiring, I worked 14 hours per day on average.</code> 作者是真的热爱这个项目啊，这种使命感很感染人。</p></li><li><p>也有大佬回应了这个项目：<a href="https://lucumr.pocoo.org/2026/5/8/local-models/">Pushing Local Models With Focus And Polish</a>，本地模型如果能和云端模型一样开箱即用是最好的，不用去配置半天各种参数啥的。</p></li><li><p>可配合上文的 ds4 一起看，<a href="https://www.youtube.com/watch?v=TXzQ7PGpO6w&t=8s">What I Learned From Implementing LLM Architectures From Scratch (And How to Get Started)</a>.</p></li><li><p>Hugging Face 也有这篇 <a href="https://huggingface.co/blog/mishig/local-moores-law">Two Years of Local AI on a Laptop: When Open Models Outpaced Moore’s Law</a>: <code>The harder constraint going forward is the 128 GB ceiling.</code> 确实，local model 的上限还是被 local 设备的算力上限锁死了。 </p></li><li><p>一直很关注 Unsloth，<a href="https://unsloth.ai/blog/pytorch">Unsloth Joins the PyTorch Ecosystem</a>，真棒。</p></li><li><p>这个也很有趣，<a href="https://thinkingmachines.ai/blog/interaction-models/">Interaction Models: A Scalable Approach to Human-AI Collaboration</a>: <code>At Thinking Machines, we believe we can solve this bandwidth bottleneck by making AI interactive in real time across any modality. This enables AI interfaces to meet humans where they are, rather than forcing humans to contort themselves to AI interfaces.</code>  加油啊！</p></li><li><p>Vercel 非常有洞见的报告 <a href="https://vercel.com/blog/ai-gateway-production-index">AI Gateway production index</a>: <code>Anthropic leads in spend despite a higher unit price, Google leads in volume... Agentic workloads carry 59% of all token volume (up 2x over 6 months)</code>.</p></li><li><p>从这篇文章 <a href="https://nrehiew.github.io/blog/sft_rl_opd/">SFT, RL, and On-Policy Distillation Through a Distributional Lens</a> 追到了这篇 <a href="https://nrehiew.github.io/blog/minimal_editing/">Coding Models Are Doing Too Much</a>: <code>Do Models Over-Edit? Yes, even frontier ones.</code> 我能感受到这个问题，虽然我一般都是全给 AI 写，不太关心这个问题，但让我感兴趣的是作者真的想办法把这个 Over-Edit 行为量化了，然后基于这个量化才会有后面的对比研究，真是漂亮。不加约束时，推理模型因为想得太多，反而比非推理模型更容易过度编辑；但加入约束后，推理模型由于指令遵循能力更强，能展现出极佳的克制力，非常合理。</p></li><li><p>回到这篇 <a href="https://nrehiew.github.io/blog/sft_rl_opd/">SFT, RL, and On-Policy Distillation Through a Distributional Lens</a>，说实话我看得也晕晕乎乎的，大概感觉和这个问题有关 <a href="https://www.zhihu.com/question/2017049686331127666/answer/2036149386116342692">为什么 MiniMax 大模型无法识别马嘉祺是谁</a>，官方给的答案是：<code>稀疏 token 遗忘的核心原因已较为明确：后训练数据对词表的覆盖不均匀，导致低频 token 的 lm_head 表征在 SFT 过程中发生漂移。而 input embedding 层的更新稀疏特性，让它仅仅丢失了生成能力而仍然保留理解能力。</code></p></li><li><p><a href="https://www.youtube.com/watch?v=rUYP4C29yCw&t=1581s">Now more than ever: building reliable software in the age of agents</a>，Jane Street 的基建是真的好啊，最让我感兴趣的：<code>Expect tests allow developers to see system behavior and create deterministic simulations at the library level.</code> 在 AI 时代这个价值真的被放大了，因为 AI 天然能读懂 Expect tests 的产物。</p></li><li><p>这个实践也非常有洞见，<a href="https://x.com/tobi/status/2053121182044451016">Learning on the Shop floor</a>: <code>There are a lot of coding agents in the world right now. What makes River special is a constraint: She only works in the open.</code> 当人和 Agent 的交互是公开的，这就变成了 <code>A teaching workshop. People started learning from each other.</code> 是这样，是这样！</p></li><li><p>一些 AI coding 的反思可参：<a href="https://maxliani.wordpress.com/2026/05/11/passion-for-software-in-the-age-of-ai/">Passion for software in the age of AI</a>，<a href="https://larsfaye.com/articles/agentic-coding-is-a-trap">Agentic Coding is a Trap</a>，<a href="https://blog.k10s.dev/im-going-back-to-writing-code-by-hand/">Im going back to writing code by hand</a>，<a href="https://x.com/fchollet/status/2052505389154115845">A few major use cases for agentic coding for me</a>，<a href="https://x.com/addyosmani/status/2052124873208799378">Cognitive Surrender</a></p></li><li><p>是很好的，<a href="https://openai.com/index/building-codex-windows-sandbox/">Building a safe, effective sandbox to enable Codex on Windows</a>，可这个 bug 啥时候修  <a href="https://github.com/openai/codex/issues/13542">Windows: bundled rg in Codex Desktop resolves on PATH but fails with Access Denied in integrated PowerShell</a>. 功能迭代是很快，<a href="https://x.com/OpenAI/status/2052480800004956323">Codex now works directly in Chrome on macOS and Windows.</a></p></li><li><p>总感觉轮回了，<a href="https://x.com/trq212/status/2052809885763747935">Using Claude Code: The Unreasonable Effectiveness of HTML</a>. 另外还有这个 <a href="https://claude.com/blog/agent-view-in-claude-code">Agent view in Claude Code</a>、<a href="https://x.com/claudeai/status/2052067399088664981">Live from Code with Claude: we’re launching dreaming in Claude Managed Agents as a research preview. Outcomes, multiagent orchestration, and webhooks are now in public beta</a>，外围工具要快啊，不快官方就下场做了。另外 A 社还有这篇 <a href="https://www.anthropic.com/research/teaching-claude-why">Teaching Claude why</a>，也可以看着玩玩。</p></li><li><p>LongCodeEdit 上的上下文效果<a href="https://x.com/nrehiew_/status/2052763179420377402">研究</a>：<code>Opus 4.6, 4.7 and GPT 5.5 all have similar performance, with Opus 4.6 being slightly better overall.</code> </p></li><li><p>也是超级有趣的研究：<a href="https://entire.io/blog/improving-agentic-search-in-coding-agents">How We Improved Agentic Search</a>: <code>The clearest result was that faster search alone only modestly helps, while better-ranked results improve first-query retrieval and help agents find the right code sooner.</code> 想想，如果有给 agent 设计的 lsp 这其实能解决一部分问题，但大部分情况下 grep 提供的 ranking 确实也不是那么理想。</p></li><li><p>这个<a href="https://crabbox.sh/">Crabbox</a>感觉挺方便的，Peter Steinberger 说<code>Whenever I investigate a bug, I let codex recreate the exact state in an emphemeral crabbox, verify the bug, fix it, verify the fix.</code> 快速的云空间，</p></li><li><p>有点标题党，但可以看看 <a href="https://arxiv.org/abs/2605.12460">Multi-Stream LLMs: Unblocking Language Models with Parallel Streams of Thoughts, Inputs and Outputs</a>:<code>We’re training models wrong and it’s due to chatGPT... This bottlenecks even very intelligent agents to a single stream. The models cannot read while writing, cannot act while thinking and cannot think while processing information. In our new paper, see below, we discuss LLMs with parallel streams...</code></p></li><li><p>这个看着也挺有意思的，<a href="https://x.com/hardmaru/status/2052787980344099293">Sparser, Faster, Lighter Transformer Language Models</a> ： <code>We teamed up with NVIDIA to try to fix this hardware mismatch. Instead of forcing the GPU to adapt to the sparsity, we built a &quot;Hybrid&quot; format that reshapes the sparsity to fit the GPU.</code> </p></li><li><p>是传统技术的文章，<a href="https://www.raycast.com/blog/a-technical-deep-dive-into-the-new-raycast">A Technical Deep Dive Into the New Raycast</a>，混合了 native 和 Web 的 UI 方案。最有趣的其实是 yetone 大佬还基于这篇文章发了个 <a href="https://github.com/yetone/native-feel-skill">native-feel-skill</a>，从文章&#x2F;知识到 skill，还挺有趣的。</p></li><li><p>说到 yetone 大佬，看到他分享的 Yansu App 的<a href="https://x.com/yetone/status/2055204767220355437">真实案例</a>还挺有趣的，虽然我不是很喜欢一切主动推送我什么东西的 app，但我确实一直很关注如何“监控”自己，发现自己的习惯中可以被优化的地方。</p></li><li><p><a href="https://x.com/EpicVogel/status/2052825103122239862">Stop typing. Start talking</a>，最近好像除了 typeless 也有很多其他选择了，豆包输入法啥的，嘛，我想有个独立办公室，我肯定这样。</p></li><li><p><a href="https://zhuanlan.zhihu.com/p/2036527621710813023">别再用 Claude Code 裸接中转站用啦</a>，我没仔细看解决方案，但想了想 Agent 时代，尤其是我慢慢都开始 yolo 模式，走中转站确实非常危险，<a href="https://arxiv.org/abs/2604.08407">Your Agent Is Mine: Measuring Malicious Intermediary Attacks on the LLM Supply Chain</a>.</p></li><li><p>Onur Mutlu 的 GPU 架构课：<a href="https://www.youtube.com/watch?v=aE0onltJlOo">GPU Architectures (Spring 2026)</a>，给了好多 ref，慢慢看吧。</p></li><li><p>Dave W Plummer 的 <a href="https://x.com/davepl1968/status/2054055451629940925">I’ve been coding for 40 years. Here are the top 5 things I wish I knew when I started</a>，很网红的标题，但确实是很扎实的工程经验，尤其是 <code>Manage complexity from day one</code>，嘛，AI 时代。。。</p></li><li><p>早看到这个我就不让 Claude 用 slidev 去画可视化了，直接抄：<a href="https://ynarwal.github.io/how-llms-work/">How LLMs Work — A Visual Deep Dive</a>.</p></li><li><p>Roblox 真认真啊，<a href="https://x.com/MrChickenRocket/status/2051950128903463130">Scene Analysis has finally shipped</a>，我都觉得可以抄这个内存的可视化了，可惜我现在不做性能了。</p></li><li><p><a href="https://x.com/lauriewired/status/2052435159203696955">CPUs tend to get slower with time</a>，就猜到是因为安全问题 <code>Unfortunately, many microcode updates are security related, which almost universally cause performance regressions…or even complete feature loss!</code></p></li><li><p>又重新看了看 <a href="https://www.youtube.com/watch?v=a1zDuOPkMSw">Hamming, “You and Your Research” (June 6, 1995)</a>，唉，<code> 你所在领域最重要的几个问题是什么？你为什么没在研究它们？</code> 问到我流汗了，转到游戏 Agent 研发算是在解决游戏开发领域最重要的问题吗？我不知道。</p></li><li><p>上次说的 PPT 直接发成 github pages 了：<a href="https://jsjtxietian.space/ai_pre_for_yx/1">AI 与游戏开发</a> ，整体还是有所体会的。基本上用 slidev 踩的坑其实经历过这一次也差不多了，整体感觉代码化确实有好有坏：好在可版本控制、组件可复用，坏在手动微调确实也不方便。在公司讲了讲，反响没有我想得那么热烈，唉，没意思，失去热情（笑）。</p></li><li><p>一直想写的 <a href="https://jsjtxietian.space/2026/05/11/trade/">交易反思</a> 也终于找到时间写了，感觉还有很多没写的，但至少迈出了第一步吧。</p></li><li><p>Perplexity 直接要求验证手机号了，+86 还不行，直接取消订阅了。唉确实 Perplexity 的搜索体验是不错的，可惜，以后要找个更好的服务来当我的股票研究的基础设施了。</p></li><li><p>因为从引擎组转到了 AI Agent 组，虽然忙多了，但也有好处，比如有了一些筛选简历的权限以及作为一面面试官的机会。感觉自己是不是也在有所成长呢，也许是吧，至少视野确实有点变化，比如我现在觉得自己的简历真的是太烂了。</p></li><li><p>最近忙到都没啥时间继续读书了，只能周末多看书学习，追忆似水年华看到马塞尔天天怀疑自己的对象，也觉得有点难读下去，还是不要代入太深比较好。另外也许这波牛要到头了，看怎么保护住自己的利润吧。</p></li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/05/16/curiosity_log_10/</id>
    <link href="https://jsjtxietian.github.io/2026/05/16/curiosity_log_10/"/>
    <published>2026-05-16T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>最近因为直接转组了还挺忙，只能说慢慢来看这个活儿确实有趣吧，不急的话还挺享受的，队友也靠谱，可惜急急急。搞得我天天都很亢奋，静息心率直接 +10 了，这可不好，周末赶紧躺平。我也是摆烂了，CTO 让我们周六去加班的来着，我直接假装看不见，需要休息。</p>
<p>当然还是有]]>
    </summary>
    <title>Curiosity Log 10</title>
    <updated>2026-09-24T07:25:43.274Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Trade" scheme="https://jsjtxietian.github.io/tags/Trade/"/>
    <content>
      <![CDATA[<h3 id="原则"><a href="#原则" class="headerlink" title="原则"></a>原则</h3><p>对于美股这个市场而言，现在的我，如果要总结一下自己的交易 profile —— 我是一个专注于科技股的趋势交易者。几个特征：</p><ul><li>保护本金：硬止损线 + 绝不向下平摊亏损</li><li>让市场证明自己是对的：不抄底只跟随，行情好择时加仓 + 行情不好减仓休息</li><li>偏好买龙头股的突破</li><li>不上杠杆、不做空、不玩妖股</li></ul><h4 id="活下去"><a href="#活下去" class="headerlink" title="活下去"></a>活下去</h4><p>如果说有什么唯一重要的原则的话，那就是活下去，控制好风险，保护好自己的本金，这是我作为散户的觉悟。市场总有好的时候，但要能活到那个时候再说。因此我会有严格的止损线，一般是 8%，心情不好的时候更低一些，可能 4% 就卖了。我一般是慢慢建仓，比如一次拿 5%-10% 的资金来建仓，然后此时如果立马跌了 8% 然后止损，总资金亏损不过 0.4%-0.8%，可以接受，不至于伤筋动骨。</p><p>更进一步，从这个原则出发，可以推导出不应该向下平摊亏损。如果刚买入就亏损了，那说明至少进场时机不太对（如果基本面没看错的话），此时我需要的是市场证明我是对的，也就是产生盈利，才能加仓。向下平摊看似可以降低成本，但有更大的可能是把我拉向泥潭。是的，它大概率会涨回来的，但要套住自己多久呢？</p><h4 id="选股"><a href="#选股" class="headerlink" title="选股"></a>选股</h4><p>选股主要是面向科技股，其实到现在，也只主要碰过 Mag7 和一些半导体。说实话，能被我了解到的，一般基本面都不错。美股七姐妹虽然现在分化得厉害，但也基本比较稳健，很难有那种腰斩式的下跌，而且就这个宏观情况来看，就算大跌其实大概率是能涨回来的，无非是时间问题。当然这不是说选股就不重要，可以闭着眼买，而是从选股上就要开始控制风险。</p><p>现在的我，个股上偏好一些没啥竞争对手的龙头公司（TSM、ASML、SK Hynix、BESI 等），或者自身 AI 故事能讲得特别好的公司（点名 GOOG，从芯片到模型到应用全包）。也喜欢买入代表行业龙头的 ETF，比如 SMH，甚至我偏好 SMH 大过 SOXX（虽然最近 SMH 没跑过 SOXX）。我能观察到我偏好集中度更高的 ETF，而不是更宽基的 ETF，QQQ &gt; SPY,  SMH &gt; SOXX，甚至歪一点的话，DRAM &gt; EWY.</p><p>但其实我心里也知道不能一直买自己熟悉的板块，因为一个板块的动能总是会慢慢减弱的，此时就需要去其他地方狩猎了。这也是我觉得社群交流、关注财经大 V 等行为的意义所在。虽然自己独立做判断有时候是绝对必要的，但总需要一些外部的信息来点我一下，提醒我可以关注哪一只或者哪个板块，或者哪个板块最近很好&#x2F;很不好说明了什么。</p><h4 id="买与卖"><a href="#买与卖" class="headerlink" title="买与卖"></a>买与卖</h4><p>如果说我对自己的选股的品味还是有点自信（去年选了 GOOG 和 MU），那我的技术水平简直是一塌糊涂，去年那两只都没吃到很大的收益，其实反而不如放着不动。</p><p>先说大的方向与思路吧，就是趋势跟随，也就是不尝试抄底、不尝试在最高点卖出。如同吃鱼，吃不到鱼头鱼尾没关系，能吃到鱼身就很好了。如果财报很好，股价一直上涨，就找机会买入，买入之后观察，如果产生了利润（市场证明了自己是正确的），就找机会加仓；如果开始下跌，则严守 8% 的止损线，既给股价一点震荡的空间，又恪守保护本金的原则。作为散户，相对机构最大的优势可能就是流动性了，我全清仓了也不会对股价有丝毫的影响，所以可以跑得很快；既然选择了经常看盘，那就发挥经常看盘的优势。</p><p>关于买点，我现在喜欢下 Stop Buy，也就是突破买单，俗称的追高。按说最理想的情况是搭上机构的快车，如果某个公司连续发布了超预期的财报，那机构可能会选择买入，但因为流动性的限制机构只能分批买入，这就会创造所谓的  Post-Earnings-Announcement Drift，这就是上车的好时机。当然这是理想情况，实际还挺难的。加仓其实可以当一次新的买入看，话虽如此，我自己也是一直不敢加疯涨的 MU.</p><p>再说卖点，这是我确实技术很差的地方，去年的 MU 和 GOOG 都是因为没有在好的时机卖出导致经受了利润的损失。理论上其实两种思路都可以，一种是 sell into weakness, 等到确定市场变差了就卖出，这里需要一些指标来判断市场情况；一种是 sell into strength, 在有可观的利润的时候先至少卖出一部分锁定利润。我现在的话偏向于前者吧（希望尽可能吃满鱼身），之前 MU 和 GOOG 犯错就是明明变差了还没有卖出，继续拖着。想了想这其实是我另一个心态在作祟：认为利润不是自己的钱，这是不对的，利润也是我的钱，亏了也该心疼。遇到不好的行情要么快跑要么忍着，最怕我之前那种忍一阵，忍不住了才跑，这样不仅心态难受，也容易吃不到后续的 V 型反弹，两头不讨好。</p><p>虽然如前所说减仓速度有点慢导致了利润损失，我还是应该庆幸我自己在今年确实恪守了“行情好择时加仓 + 行情不好减仓休息”。在前几周 QQQ 开始往上猛冲的时候，我一边观察一边加仓，然后确实也在最近一周基本满仓了。当然也有行动时机不太对的时候，比如我建仓 TSM 的时候忘了看财报时间，结果在财报前两天建仓了，其实很有问题，因为财报日其实是有风险的，一般除非利润垫够厚，最好不赌财报，控制风险。</p><h4 id="纪律与变式"><a href="#纪律与变式" class="headerlink" title="纪律与变式"></a>纪律与变式</h4><p>除了之前说的止损线和不向下平摊以外，还有几个：不上杠杆、不做空、不玩妖股。我本身对做空没有那么大的敌意，但是确实收益有限，而且大趋势上行玩做空确实有点找死；不玩妖股这条其实执行得也不错，因为我最近也只做自己懂的那些。</p><p>不上杠杆这个其实也可以从保护本金这条原则推导出来，比如 SOXL，三倍做多 SOXX，最近的收益可高了。我再看好半导体也不会碰的，因为杠杆会放大收益，也会放大损失。半导体板块回撤 5% 家常便饭，不加杠杆可能还能当震荡抗一抗，加了杠杆直接 -15% 本金都有危险，很容易翻车。从控制风险的角度来说，我是不会碰的。另外一点就是控制自己的欲望，杠杆会放大欲望，会侵蚀我对常态下金钱和收益的感觉，我个人觉得对我而言也是很危险的（但最近大牛市其实也是啊）。有钱可以慢慢赚，求稳定，不冒险，不犯错。</p><p>另一个体会就是，我慢慢内心接受了，有些钱不是自己的，就是赚不到。我选择了一套交易系统，接受了相关的原则，那也就锚定了那部分的收益，放弃了其他交易系统能获得的那部分收益。我要优化的是我的盈亏比——严守纪律活下去的同时，尽量选择好的股票与好的时机，让赚钱的仓位多赚点，及时止损亏损的仓位，同时根据反馈慢慢提高我的胜率。</p><p>当然，其实针对不同的市场环境可以有不同的打法：</p><ul><li>上行牛市，趋势交易</li><li>震荡市，现金观望 + QQQI 吃股息；趋势交易需要更慎重，止损线收更紧；手痒可以玩玩低买高卖，但绝不玩大</li><li>下行熊市，空仓观望，谨慎做空</li></ul><p>策略可以是混合的，但纪律是要严守的。话虽如此，我还是喜欢大道至简，虽然不看期权会少很多信息，但还暂时不碰期权（QQQI 这种不算）；技术面上也不喜欢太复杂的分析，只要能判断趋势即可；我甚至自己做了个看盘网页来辅助判断，这也算是 AI 带来的好处。</p><h3 id="心路"><a href="#心路" class="headerlink" title="心路"></a>心路</h3><p>我的交易之路完全是由 cyt 带领入门的，她最开始推荐了我《股票大作手回忆录》这本书。</p><p>先说祖师爷利弗莫尔吧，《股票大作手回忆录》就是关于他的故事。他教会我的是原则，虽然我当时并不太会遵守原则。跟着趋势交易、市场永远不会错、寻找阻力最小的方向、不向下平摊亏损、利润是坐着来的，等等。</p><p>然后是克罗的《期货交易策略》，继续加强了利弗莫尔提出的原则。更进一步，在这本书的影响下我开始总结一些原则作为我的交易系统，虽然不是很成熟，均线交叉的策略也显得很 Naive，但毕竟有系统和策略总比没有好。如何设置止盈止损、何时加仓等确实是非常复杂的问题，克罗让我开始思考这些问题了。此外就是对于纪律的强调，再多也不为过。</p><p>最近则是 Mark Minervini 的《Trade Like a Stock Market Wizard》，依然是基于利弗莫尔的路数，但是技术分析更加深入了。他会分析价格、交易量、K 线形态等，主推 VCP 形态是最好的入场时机，还会顺带讲讲为什么会这样。Mark Minervini 的体系是挺完备的，他喜欢基本面和技术面的共振。他后面那本书我还没读，但主要是最近太忙了实在没空读，不是不想。我自己做的看盘网页里主要的指标都是从他的书里抄来的，当作参考确实很好。当然，他也是强调纪律，纪律，纪律。</p><p>其实读完了克罗的书之后，我在找接下来读啥的时候，除了 Mark Minervini 还想着要不要看看彼得林奇的书，最后我还是放弃了。并不是他的书不好，而是暂时还没有必要去打乱自己的交易风格，技能点先按一条路点下去再说吧。还有很多要学的 —— 宏观经济、如何读财报、期权策略，更深入的技术分析，等等。我其实发现自己还是更喜欢通过看书来学习，更系统，更能让我代入，理解也更深刻。AI 也能帮我很多，我 NotebookLM 就有一个专门的 Notebook 是关于投资的，没事会去里面问问问题，和 AI battle 一下。我的看盘网页里还有个功能是一键复制 prompt 去问 AI，会把一些技术面信息填进 prompt 模板里，交给 Gemini 或者 Perplexity 去给我调研去。</p><p>大 A 还是不一样，我现在的策略绝不是趋势交易，而是 03441 打底 + 向量化投降。主要白天上班颇忙，确实也没空看盘，也没空研究那些公司，也难怪我赚不到钱。想要赚钱还是要认真，不能把交易当兴趣，因为兴趣是让人花钱的。只能说，希望自己早日迈上自由之路吧。</p>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/05/11/trade/</id>
    <link href="https://jsjtxietian.github.io/2026/05/11/trade/"/>
    <published>2026-05-11T00:00:00.000Z</published>
    <summary>
      <![CDATA[<h3 id="原则"><a href="#原则" class="headerlink" title="原则"></a>原则</h3><p>对于美股这个市场而言，现在的我，如果要总结一下自己的交易 profile —— 我是一个专注于科技股的趋势交易者。几个特征：</p>
<ul]]>
    </summary>
    <title>交易反思 (2026.5 版)</title>
    <updated>2026-09-24T07:25:43.278Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
      <![CDATA[<p>唉，这次更新又迟到了，这次是因为五一去广西玩了，内感洞、弄拉、通灵大峡谷、德天瀑布、蓝洞咖啡、明仕田园、南宁城里转转，喀斯特地貌一次看够，粉也确实好吃。我真还挺喜欢的，反正不懂的还可以问问 Gemini。我最喜欢的风景反而是司机带我们走一条小路去德天瀑布的时候，路在半山腰上，时上时下，看着下方的村落与上方的山头，绿意盎然。德天瀑布那边也很有趣，毕竟对面就是越南，中国这边人哗啦哗啦多，越南那边淅淅沥沥的几个，这对比也很有趣。</p><hr><ul><li><p>看到标题就笑了，<a href="https://shimin.io/journal/opus-4-7-just-lazy/">Opus 4.7 isn’t dumb, it’s just lazy</a>，Amp 的评测也不错 <a href="https://ampcode.com/news/opus-4.7">Opus 4.7</a>；说到 Claude，Claude code 降智原因调查也出来了，<a href="https://www.anthropic.com/engineering/april-23-postmortem">An update on recent Claude Code quality reports</a>；还有 GPT5.5，又是 Amp：<a href="https://ampcode.com/news/gpt-5.5">GPT-5.5 In Deep</a>，希望每个模型都有一个这样的 model card：<a href="https://ampcode.com/models/gpt-5.5">GPT 5.5 - Amp</a>.</p></li><li><p>Kimi 2.6 发了，<a href="https://x.com/Kimi_Moonshot/status/2046249571882500354">Meet Kimi K2.6</a>；deepseek v4 发了，很多文章，<a href="https://www.zhihu.com/question/2030963929510310856/answer/2031519601733919763">DeepSeek V4 预览版本上线并同步开源，哪些亮点值得关注</a>，<a href="https://zhuanlan.zhihu.com/p/2031825857543672813">我用自家公司的 BIOS 二进制文件，考了一次 DeepSeek V4 Pro——结果让我沉默了</a></p></li><li><p><a href="https://blog.google/innovation-and-ai/infrastructure-and-cloud/google-cloud/eighth-generation-tpu-agentic-era/">Two chips for the agentic era</a>，谷歌芯片分 TPU 8t: The training powerhouse 和 TPU 8i: The reasoning engine 了，有意思。</p></li><li><p>说到训练，<a href="https://www.youtube.com/watch?v=xmkSf5IS-zw">How GPT, Claude, and Gemini are actually trained and served</a>；还有这个，<a href="https://openai.com/index/where-the-goblins-came-from/">Where the goblins came from</a>，真的好好玩；Fine-tuning 教程：<a href="https://leoniemonigatti.com/blog/fine-tuning-lfm2-5-1-2b-instruct-with-grpo.html">Fine-tuning LFM2.5-1.2B-Instruct with GRPO </a></p></li><li><p><a href="https://x.com/jyangballin/status/2051677497562210552">ntroducing ProgramBench: 200 rigorous, whole-repo generation tasks where models design, build, and ship a working program end to end</a>，这个有意思，目前通过率全是 0，但确实从<a href="https://programbench.com/">这里</a>可以看到，Opus 4.7 确实强。</p></li><li><p>tison 哥的好文 <a href="https://mp.weixin.qq.com/s/x_FUUG4wBUqYs1H5DUtpgQ">夜天之书 #119 Agentic Coding 的边界</a>，<code>软件质量缺少可量化回归指标</code>，<code>隐性知识需要真人提供</code>，说得多好啊；这个也是，<a href="https://arize.com/blog/code-is-free-technical-debt-isnt-notes-from-ai-engineer-europe/">Code is free, technical debt isn’t</a>，<a href="https://www.youtube.com/watch?v=v4F1gFy-hqg">Software Fundamentals Matter More Than Ever</a>.</p></li><li><p>非常不错的 harness 总结，<a href="https://addyosmani.com/blog/agent-harness-engineering/">Agent Harness Engineering</a>，以及 pi 作者的分享 <a href="https://www.youtube.com/watch?v=RjfbvDXpFls">Building pi in a World of Slop</a>，这个也不错，<a href="https://www.zhihu.com/question/2021986352292537180/answer/2028563228460852446">Harness Engineering 时代下有哪些优秀样例</a>；以及 ykiko 的新文章，<a href="https://zhuanlan.zhihu.com/p/2034883949630059124">agent 时代的 clice</a>。</p></li><li><p>学到了新名词，<a href="https://vickiboykis.com/2026/04/13/mechanical-sympathy/">Mechanical sympathy</a>.</p></li><li><p><a href="https://bcantrill.dtrace.org/2026/04/12/the-peril-of-laziness-lost/">The peril of laziness lost</a>: <code>The problem is that LLMs inherently **lack the virtue of laziness**. Work costs nothing to an LLM. LLMs do not feel a need to optimize for their own (or anyone’s) future time, and will happily dump more and more onto a layercake of garbage.</code></p></li><li><p><a href="https://medium.com/@adamprout/agents-are-better-testers-than-we-are-30b1738114d6">Agents Are Better Testers Than We Are</a>，那确实；<a href="https://blog.cloudflare.com/agents-stripe-projects/?utm_campaign=cf_blog&utm_content=20260429&utm_medium=organic_social&utm_source=twitter">Agents can now create Cloudflare accounts, buy domains, and deploy</a>，好啊，Cloudflare 确实很先进。</p></li><li><p><a href="https://arxiv.org/abs/2605.02178">T$^2$PO: Uncertainty-Guided Exploration Control for Stable Multi-Turn Agentic Reinforcement Learning</a>，好友崔崔的 paper：<code>我们发现多轮 agentic RL 不稳定的根源之一是“犹豫”——模型在反复生成低信息量 token，看似在思考，实则原地打转。T²PO 用不确定性来约束探索，让 agent 少走弯路，训练更稳定。</code> 非常棒！</p></li><li><p>还有后续，<a href="https://x.com/gregpr07/status/2047358189327520166">The Bitter Lesson of Agent Harnesses</a>：<code>The bitter lesson of agent harnesses: your helpers are abstractions too. Delete them. Let the agent write what it needs.</code></p></li><li><p>Jina AI 的分享很不错，<a href="https://mp.weixin.qq.com/s/93SsY__dxtsUPXhAPsjHCA">2026 年做搜索就是做 Agent Memory</a>，顺藤摸瓜发现了 <a href="https://dr.miromind.ai/">MiroThinker</a>；说到记忆，<a href="https://mp.weixin.qq.com/s/DJtp4QUJtJHCnNU9yarsww">吹了几年的 AI 个人知识库，为什么还是那么难用</a>，这里的分层框架还不错。</p></li><li><p>谈带宽的显存容量比，<a href="https://zhuanlan.zhihu.com/p/2029981166191780212">大模型时代的新 roofline</a>，<code>agentic推理已经逐渐滑向严重的memory capacity bound</code>，早点看到我就满仓海力士了。<a href="https://x.com/lemire/status/2048033674570899701">Daniel Lemire on X</a>: <code>The trend is clear: faster and faster memory.</code> <a href="https://www.youtube.com/watch?v=LF3aUIM57uw">The Supply and Demand of AI Tokens</a>，由于复杂的强化学习环境和代码部署任务极度依赖通用计算，CPU 也处于售罄状态。<a href="https://www.anjalishriva.com/fat-tails">Why fat tailed costs emerge at scale</a>，唉，<code>Long-context, agentic workloads, and more users compound tail risk; tail risk here refers not just to profit loss, but overcommitting resources and crashing systems.</code></p></li><li><p>学学，<a href="https://zhuanlan.zhihu.com/p/2031135579979638176">确定性的边界：从 GPU 到 Groq 的 AI 芯片谱系学</a>。</p></li><li><p>学学，<a href="https://mp.weixin.qq.com/s/zqnJuv5OVsNGEefM7RguqQ">独家对话罗福莉：AI 范式已然巨变</a>：<code>要去做好Agent的Post-train。更具体说，是在Agent上怎么做好RL的scaling...至少在Chat时代，for研究、for Pre-train和for Post-train的用卡比例非常夸张，比如3:5:1，现在一个非常合理的用卡比例可能是3:1:1</code>。OpenClaw 我能欣赏它的产品，但确实没给我带来巨震倒是，虽然我确实觉得越来越有一个一直跑着 AI 的 vps 的需求了，难道是我比较后知后觉？</p></li><li><p><a href="https://timzaman.com/getting-into-ai-infra">Getting Into AI Infra</a>，非常好的文章，其中的练习我想了想我大概没法马上画出来：<code>Another good exercise is to draw a cartoon systems diagram of a gaming PC and annotate the rough bandwidths between the components.</code></p></li><li><p>每周都会看待 agent 帮助下的算子优化，<a href="https://zhuanlan.zhihu.com/p/2028849708638979935">如何让 Claude Opus 4.6 写一个 100% CUBLAS 性能的 GEMM 算子</a>；也有这种 <a href="https://x.com/pupposandro/status/2046264488832213174">How we got 207 tok&#x2F;s with Qwen3.5-27B on an RTX 3090</a>，和这种 <a href="https://github.com/antirez/llama.cpp-deepseek-v4-flash">llama.cpp-deepseek-v4-flash: Experimental implementation of DeepSeek v4 flaash in llama.cpp</a>.</p></li><li><p>刷到了这本书，看着也不错，<a href="https://zhuanlan.zhihu.com/p/2034971147138286320">《AI Systems Performance Engineering》略读小记</a>。</p></li><li><p><a href="https://www.trychroma.com/research/context-rot">Context Rot: How Increasing Input Tokens Impacts LLM Performance</a>，不是新文章，做 ppt 的时候发现的，写得很好。</p></li><li><p><a href="https://blog.eladgil.com/p/random-thoughts-while-gazing-at-the">Random thoughts while gazing at the misty AI Frontier</a>：<code>AI will first automate away the things that are easier to form a closed loop learning system on. This is why code and AI research may be accelerated and then displaced quickly - you can have testable closed loop systems so machines can learn and iterate quickly. The tighter the closed loop, the faster the AI can learn. </code></p></li><li><p>Deep Research 进化了，但我似乎很久没用了，<a href="https://blog.google/innovation-and-ai/models-and-research/gemini-models/next-generation-gemini-deep-research/">Introducing Deep Research and Deep Research Max</a>.</p></li><li><p>可以对照看：<a href="https://openai.com/zh-Hans-CN/index/introducing-workspace-agents-in-chatgpt/">在 ChatGPT 中推出工作空间智能体</a> ，<a href="https://cloud.google.com/blog/products/ai-machine-learning/introducing-gemini-enterprise-agent-platform">Introducing Gemini Enterprise Agent Platform</a>.</p></li><li><p>感觉谈 multi agent 的变多了，<a href="https://x.com/walden_yan/status/2047054401341370639">Multi-Agents: What’s Actually Working</a>，<a href="https://x.com/GoogleCloudTech/status/2047567704807346675">How A2A and MCP work together: five integration patterns for building multi-agent systems</a>，<a href="https://github.com/chekusu/wanman">wanman</a>，<a href="https://maggieappleton.com/zero-alignment">One Developer, Two Dozen Agents, Zero Alignment</a></p></li><li><p><a href="https://github.blog/ai-and-ml/generative-ai/how-ai-is-reshaping-developer-choice-and-octoverse-data-proves-it/">How AI is reshaping developer choice</a>：<code>developer choice is shifting toward technologies that work best with the tools we’re already using.</code></p></li><li><p><a href="https://www.zhihu.com/question/1992208967498236682/answer/2028074933238907033">如何评价 Claude Code 核心工程师「Bash 即一切」的观点</a>，<code>LLM可能永远都无法非常擅长写Bash。Bash中，对引号、括号进行匹配是个 Dyck-k 问题。然而，Transformer的电路复杂度类别是TC0，因此，它非常不擅长处理这种需要在内部维持状态的工作，理论上就无法完成任意深度的配对任务。更不要说里面还常常会碰到带转义的引号，又要分门别类处理了。</code></p></li><li><p>刷到一篇 Computer Use 的原理，<a href="https://x.com/injaneity/status/2051730711712063994">The internals of Computer Use in Claude Cowork &amp; OpenAI’s Codex</a>，我就说为啥都在 Mac 上先出，Mac 的 Accessibility 做得好，所以 AI 也能更方便地看到那些 UI 控件，真有趣。</p></li><li><p>有大神在帮 OpenClaw 优化 OpenRouter 的 token 消耗：<a href="https://x.com/cherry_mx_reds/status/2048063265314340932">we intentionally cut aggregate OpenRouter token usage by ~35%, down to ~400B tokens.</a></p></li><li><p><a href="https://x.com/yetone/status/2047701073474072712">Yansu App</a>，挺有趣的想法，让 AI 主动观察用户的行为，默默帮助你去 build 你需要的提效工具；<a href="https://github.com/tw93/Kami">Kami</a>，纸张排版 skill. </p></li><li><p><a href="https://github.com/warpdotdev/warp">Warp is an agentic development environment, born out of the terminal</a> 开源了。</p></li><li><p><a href="https://github.com/openclaw/mcporter">openclaw&#x2F;mcporter: Call MCPs via TypeScript, masquerading as simple TypeScript API. Or package them as cli</a>，<a href="https://github.com/mlc-ai/xgrammar">xgrammar: Fast, Flexible and Portable Structured Generation</a>，我竟然才发现这些。</p></li><li><p>好分析，<a href="https://matduggan.com/if-i-could-make-my-own-github/">if-i-could-make-my-own-github</a>，虽然没啥关系，但最近 github 确实不够稳定。</p></li><li><p><a href="https://devblogs.microsoft.com/visualstudio/stop-hunting-bugs-meet-the-new-visual-studio-debugger-agent/">Meet the New Visual Studio Debugger Agent Workflow</a>，很需要，crash 有 windbg-mcp 了，debug 也需要。</p></li><li><p>麦老师的 Agent，<a href="https://zhuanlan.zhihu.com/p/2032812681472779550">KimiX：Agent Swarm 与更加高效的工具</a></p></li><li><p>谈 Claude Design 和 Figma 的文章 <a href="https://samhenri.gold/blog/20260418-claude-design/">Thoughts and Feelings around Claude Design</a>：<code>There’s an Arts and Crafts principle called truth to materials — the idea that a thing should be honest about what it is and how it’s made, rather than masquerading as something else. Figma ended up being the opposite of this: a set of extremely rigid schemas with a free-form “just vibes, man” costume over the top.</code></p></li><li><p><a href="https://www.ncregister.com/commentaries/schnell-repairing-the-ruins">Repairing the Ruins: Why AI Can’t Replace Education</a>：<code>We tend to celebrate knowledge: facts accumulated, results confirmed, information stored. But as the biologist Stuart Firestein has argued, discovery begins not only with what we know but with a disciplined sense of what we do not yet understand. That frontier is where large language models reach their limit.</code></p></li><li><p>当然总有一些偏悲观的文章，<a href="https://techtrenches.dev/p/the-west-forgot-how-to-make-things">The West Forgot How to Build. Now It’s Forgetting Code</a></p></li><li><p><a href="https://x.com/Varaquilex/status/2050672333489406353">C vs Python &amp; LLMs</a>，说实话我觉得和训练语料有关，但是给 agent 以 profile 工具以及一些提示，应该让它自己优化没啥大问题。</p></li><li><p>游戏上没看到啥，零散几篇，<a href="https://zhuanlan.zhihu.com/p/2030321408509735061">游戏运行时 AI Native Debug 工程</a>，<a href="https://mp.weixin.qq.com/s/ECY99iEzWAHDv11-1Iz05w">米哈游坦白局：AI 全面升级游戏管线，崩坏 IP 正在做什么？</a></p></li><li><p>来点传统技术，这个有意思：<a href="https://trainsec.net/library/windows-kernel/launch-wsl-applications-from-windows-with-wsllaunch/">Launch WSL Applications from Windows with WslLaunch</a>，能想象出一种混合平台编程；虽然很久不看图形学了，但是 <a href="https://www.ludicon.com/castano/blog/2026/04/metal-lossy-compression-format/">Metal Lossy Compression Format</a>；<a href="https://adamj.eu/tech/2022/06/17/mike-actons-expectations-of-professional-software-engineers/">Mike Acton’s Expectations of Professional Software Engineers</a>；<a href="https://x.com/lemire/status/2048820249118880088">Daniel Lemire on X: “You can beat the binary search” &#x2F; X</a></p></li><li><p>好好睡觉 <a href="https://super-memory.com/articles/sleep.htm">Good sleep, good learning, good life</a>.</p></li><li><p><a href="https://www.youtube.com/watch?v=a1zDuOPkMSw">Hamming, “You and Your Research” (June 6, 1995) </a>，我也需要 Great Thoughts Time，时常觉得自己的工作太 trivial 了，一点也不重要，所以很没意思，也许我也该学着“每隔七年左右更换研究领域，可以防止思维僵化”，至少要一直学点新东西，不论是投资还是拳击还是做饭，不然太无聊了。</p></li><li><p>我自己在做个分享的 ppt，地址在这 <a href="https://github.com/jsjtxietian/ai_pre_for_yx">ai_pre_for_yx</a>. 用的是 slidev 的 skill + Claude Opus&#x2F;Sonnet + cdp 截图反馈。Opus 太慢了我后面换成 sonnet，但确实体感 sonnet 的理解能力不如 opus. Claude Code 的很多小功能确实不错，btw, recap 都挺实用的。这次我还是让 AI 用 vue 组件或者 css 直接画样式包括图表的，还没上 AI 直接生成图之类，也许下次可以试试。说实话习惯了之前的所见即所得的编辑，有时候还是会被 AI 气到，即使 AI 可以自己截图来调整样式，很多视觉的东西还是自己控制比较安心。可能 slidev 确实就是不适合太精细，主打一个差不多就行，还好这次本也就是差不多就行。内容本身因为面向公司的，删了很多，反而体现自己的思考，到底要讲啥不讲啥。</p></li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/05/07/curiosity_log_9/</id>
    <link href="https://jsjtxietian.github.io/2026/05/07/curiosity_log_9/"/>
    <published>2026-05-07T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>唉，这次更新又迟到了，这次是因为五一去广西玩了，内感洞、弄拉、通灵大峡谷、德天瀑布、蓝洞咖啡、明仕田园、南宁城里转转，喀斯特地貌一次看够，粉也确实好吃。我真还挺喜欢的，反正不懂的还可以问问 Gemini。我最喜欢的风景反而是司机带我们走一条小路去德天瀑布的时候，路在半山腰上]]>
    </summary>
    <title>Curiosity Log 9</title>
    <updated>2026-09-24T07:25:43.276Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
      <![CDATA[<p>不知不觉两周又过去了，终于打完了《死亡搁浅 2》，可以回到《追忆似水年华》了。摆烂还是挺开心的，下班之后买菜散步然后打游戏。可惜之后可能没法按时下班了，惨啊，不过正好有时间多看看 AI 相关的东西。蹭了一节公司送的拳击体验课，太爽了！！！那种明明一点力气都没了但依然在教练的鼓励与自身的意志下努力挥拳的感觉，非常上瘾，搞得当天晚上直接失眠，but I want more!</p><p>听说前司强制项目组所有人月底前必须用 Codex 或者 Cursor 解决不少于一个工作相关的需求，我就 emmmm, 不知道该说啥了，我这种偏向 AI 激进派的都听了会摇头，这不是大家纯给领导的焦虑演戏打工么，如同当年强制打自家游戏段位和绩效绑定一样。当然，想想，我要是还在前司会有多受欢迎啊。。。</p><hr><ul><li><p>Opus 4.7 发布了，官方的技巧介绍：<a href="https://claude.com/blog/best-practices-for-using-claude-opus-4-7-with-claude-code">Best practices for using Claude Opus 4.7 with Claude Code</a>，加的 adaptive thinking 看着还是挺有争议的；Boris Cherny 也介绍了一些<a href="https://x.com/bcherny/status/2044847858634064115">技巧</a>，这个思路还行：<code>many of my prompts these days look like &quot;Claude do blah blah /go&quot;. /go is a skill that has Claude 1. Test itself end to end using bash, browser, or computer use 2. Run the /simplify skill 3. Put up a PR</code>.</p></li><li><p>Meta 也有新模型，<a href="https://www.riteshkhanna.com/blog/muse-spark-arena">I Tested Meta Muse Spark Against 4 Frontier Models</a>，不知道能不能重新上牌桌呢。另外有个 Gemma4 的介绍：<a href="https://newsletter.maartengrootendorst.com/p/a-visual-guide-to-gemma-4">A Visual Guide to Gemma 4</a>，整体看社区反馈似乎还不错的样子。</p></li><li><p>Claude 的 Context Management 小技巧介绍：<a href="https://x.com/trq212/status/2044548257058328723">Using Claude Code: Session Management &amp; 1M Context</a>；他们的新文章更有趣一些，<a href="https://www.anthropic.com/engineering/managed-agents">managed-agents</a>：<code>We virtualized the components of an agent: a session (the append-only log of everything that happened), a harness (the loop that calls Claude and routes Claude’s tool calls to the relevant infrastructure), and a sandbox (an execution environment where Claude can run code and edit files). This allows the implementation of each to be swapped without disturbing the others. We&#39;re opinionated about the shape of these interfaces, not about what runs behind them.</code></p></li><li><p><a href="https://davegriffith.substack.com/p/why-isnt-everything-different-yet">Why Isn’t Everything Different Yet</a>，辩护文，如果 AI 真的有 KOL 吹的那么强，那么为啥世界还没发生天翻地覆的变化。有很多理由，我还是挺认同这个的：<code>Fast by historical standards is still slow by Tuesday standards</code>。想想确实如此，AI 才出来几年。我每次做这个 Curiosity Log，都会感叹，过去两周竟然发生了这么多事情。</p></li><li><p>每周都有更多人在赞美 AI，<a href="https://lalitm.com/post/building-syntaqlite-ai/">Eight years of wanting, three months of building with AI</a>，还有在 AI 帮助下用.Net 写推理引擎的，<a href="https://github.com/kkokosa/dotLLM">dotLLM</a>,<code>On decode, dotLLM reaches 66-88% of llama.cpp throughput. Prefill is a different story - dotLLM is roughly 2-5x slower than llama.cpp across the board. </code></p></li><li><p>当然也有偏悲观主义的文章，<a href="https://aphyr.com/posts/411-the-future-of-everything-is-lies-i-guess">The Future of Everything is Lies, I Guess</a>，里面提的一个概念很不错：<code>The shape of things LLMs are good at seems to be jagged</code>.  不同于人类能力基本是从易到难平滑过渡的，LLM 的能力边界是锯齿状的，LLM 在解多元微积分的同时，却无法理解简单的词语谜题，一边非常聪明，一边又蠢到让人想笑。</p></li><li><p>karpathy 的 <a href="https://karpathy.bearblog.dev/year-in-review-2025/">2025 LLM Year in Review</a> 也提到了类似的概念，<code>We&#39;re not &quot;evolving/growing animals&quot;, we are &quot;summoning ghosts&quot;.</code> 他最近也有<a href="https://x.com/karpathy/status/2042334451611693415">一篇</a>写了相关的，<code>a lot of the capabilities are relatively &quot;peaky&quot; in highly technical areas. Typical queries around search, writing, advice, etc. are *not* the domain that has made the most noticeable and dramatic strides in capability. Partly,  this is due to the technical details of reinforcement learning and its use of verifiable rewards. But partly, it&#39;s also because these use cases are not sufficiently prioritized by the companies in their hillclimbing because they don&#39;t lead to as much $$$ value</code>.</p></li><li><p>还有把 Open web 比作黑暗森林的，<a href="https://ryelang.org/blog/posts/cognitive-dark-forest/">The Cognitive Dark Forest</a>，当个思想实验看看还挺有趣的。</p></li><li><p>当然至少我认同 <a href="https://www.oreilly.com/radar/conviction-collapse-and-the-end-of-software-as-we-know-it/">“Conviction Collapse” and the End of Software as We Know It</a> 里说的：<code>AI will be really good at making certain processes more efficient. But it won’t be really good at making new processes unless people start to focus on that. And that’s a human creativity thing.</code></p></li><li><p>紧接着就是这个讨论，<a href="https://x.com/altryne/status/2043748676099866771">The Z&#x2F;L Continuum - Do AI engineers even need to read code anymore?</a> 里面提到 <code>Ryan Lopopolo from @OpenAI took the stage and said “code is a liability” and that we should all strive to be “token billionaires” - and on the last day, Mario Zechner of Pi got standing ovations after he told folks to “slow the fuck down” and “read every fucking line of critical code”</code>，我大概偏向于自适应吧，靠自己判断要不要看代码，那其实还是偏向 slow down 这一端。里面其他观点也都挺有趣的，比如 <code>AI was supposed to make us more productive, but we all just work more</code>，比如 <code>Many AIEs are quick to host MCP funerals, while enterprises adopt MCP and MCP Apps faster than ever, due the inherit security risks of agent skills</code>, 比如 <code>IDEs are dying, Github is seeing unprecedented traffic levels (15x their biggest year, which was last year), so is @Cloudflare</code>. </p></li><li><p>说到 pi 作者，他有个新的分享 <a href="https://www.youtube.com/watch?v=RjfbvDXpFls">Building pi in a World of Slop</a>，还是那些观点，Agent 的代码能力源于互联网，而互联网上 90% 的代码本身就是老旧的垃圾代码，所以要小心，别放手；人类虽然会犯错但是会铲屎重构；只在任务范围极其明确、代码高度模块化的前提下，才让 Agent 做去处理代码。以及 pi 作者加入公司来维护 pi 了，<a href="https://mariozechner.at/posts/2026-04-08-ive-sold-out/">I’ve sold out</a>，依然是核心部分开源。</p></li><li><p>正好上面提到了 Cloudflare，他们刚发一篇 blog，<a href="https://blog.cloudflare.com/shared-dictionaries/">Shared Dictionaries: compression that keeps up with the agentic web</a>，为了应对 agent 时代他们网络基础设施压力陡增，提了一个很聪明的解法：<code>In order to scale with more requests hitting heavier pages that are re-deployed more often, compression has to get smarter.</code> </p></li><li><p>还有这个，<a href="https://x.com/mitchellh/status/2041566958681014418">The Building Block Economy</a>：<code>AI is okay at building everything from scratch, but it is *really good* at gluing together high quality, well documented, and proven components. And, AI prefers to do this when it can unless explicitly prompted otherwise.</code></p></li><li><p>新版的 <a href="https://openai.com/index/codex-for-almost-everything/">Codex</a> 也带着 Computer Use 了，更让我好奇的是也带着记忆了：<code>We’re also releasing a preview of **memory**, which allows Codex to remember useful context from previous experience, including personal preferences, corrections and information that took time to gather.</code> 说到记忆，<a href="https://github.com/garrytan/gbrain">gbrain</a> 挺有意思的，<code>This is my personal opinionated OpenClaw/Hermes Agent setup with full Graph RAG, Vector Search, and retrieval on top of Karpathy&#39;s markdown as system-of-record LLM knowledge wiki.</code> 然后 Nowledge Labs 也有一篇文章：<a href="https://nowledge-labs.ai/zh/blog/building-memory-systems-for-ai-agents">为 AI Agent 构建记忆系统</a>。</p></li><li><p>说到 Karpathy 这个 knowledge wiki，他自己又<a href="https://x.com/karpathy/status/2042626702459674801">发帖</a>说：<code>it&#39;s the tractable form of brain upload</code>. 好奇的是，如果我死了，大家看我的博客所展现的我的脑子，似乎和我自己认为的我的脑子不会很一样。</p></li><li><p>才发现这个评测 <a href="https://metr.org/time-horizons/">Task-Completion Time Horizons of Frontier AI Models - METR</a>，还蛮好的，<code>The task-completion time horizon is the task duration (measured by human expert completion time) at which an AI agent is predicted to succeed with a given level of reliability.</code> 注意默认是 log scale 的，改 linear scale 才能感受到 AI 发展有多快。这个评测是从这篇文章发现的，<a href="https://x.com/tianle_cai/status/2042459055483207818">Dario Says Continual Learning Is Solved. Is It?</a></p></li><li><p>说到评测，Dawn Song 发了个好玩的<a href="https://x.com/dawnsongtweets/status/2042616204888801450">帖子</a>：<code>Our agent Terminator-1 scored ~100% on 8 major AI agent benchmarks, e.g., SWE-bench Verified &amp; Pro, Terminal-Bench, beating Claude Mythos. It solved 0 tasks.</code> 提醒大家不能盲目信这些 benchmark 的最终结果。</p></li><li><p><a href="https://github.com/MiniMax-AI/cli">MiniMax cli</a>很聪明的解法：<code>Instead of calling a Minimax TUI, they give you a skill that you can use to call the &quot;mmx&quot; command line tool from any other harness.</code></p></li><li><p><a href="https://www.mintlify.com/blog/how-we-built-a-virtual-filesystem-for-our-assistant">How we built a virtual filesystem for our Assistant</a>，<code>The agent doesn&#39;t need a real filesystem; it just needs the illusion of one. Our documentation was already indexed, chunked, and stored in a Chroma database to power our search, so we built ChromaFs: a virtual filesystem that intercepts UNIX commands and translates them into queries against that same database. </code> 有点意思的思路，给 agent 的 api 还是文件读写那些，下面换成了数据库的操作。</p></li><li><p>黄仁勋的最新<a href="https://x.com/dwarkesh_sp/status/2044456498441708013">访谈</a>，谈英伟达做什么、不做什么，说<code> more when necessary, less when possible</code>，就啃着硬骨头干；也从他的角度分析了 TPU 和 GPU 的利弊，想到这个 <a href="https://x.com/MainzOnX/status/2044462083010662771">From SIMT to Systolic: A Foundation for GPU and TPU Architecture</a>，也是雄文：<code>I&#39;ll try to convince you that TPU is the better platform even for the thing GPUs were supposed to own outright, which is custom kernel authoring.</code></p></li><li><p>说到英伟达，他们发了个新模型， <a href="https://github.com/nv-tlabs/lyra/tree/main/Lyra-2">Lyra-2</a> turns an image into a 3D world you can walk through, look back, and drop a robot into for real-time rendering, simulation, and immersive applications. 挺酷的。</p></li><li><p>围绕 Mythos 和相关的，<a href="https://sockpuppet.org/blog/2026/03/30/vulnerability-research-is-cooked/">Vulnerability Research Is Cooked</a>，<a href="https://www.understandingai.org/p/why-anthropic-believes-its-latest">Why Anthropic believes its latest model is too dangerous to release</a></p></li><li><p><a href="https://www.zhihu.com/question/1994448618531337777/answer/2008084378950051725">transformer 能否拟合出哈希算法</a>，确实。</p></li><li><p>关于训练，<a href="https://x.com/HiTw93/status/2040047268221608281">你不知道的大模型训练：原理、路径与新实践</a>，随便看看；推理的更有意思，<a href="https://zhuanlan.zhihu.com/p/2028172692533068285">Codex 在推理框架上能蹬出什么优化</a>，<code>然后亮点是它debug修复的过程中除了比较图片的PSNR和MAE之外还会用ffmpeg去截一张生成视频的图然后用多模态的方式读这个图判断画面是正常还是乱码。</code> Codex 确实聪明，我最近在 vibe 网页，它也会自己去调用工具截图看问题。</p></li><li><p>关于推理还有这个，<a href="https://zhuanlan.zhihu.com/p/2026354265170397100">TritonLLM v0.1.1: Agent 时代的大模型推理</a>，<code>Attention is all you need，attention is also gold。我们的注意力和时间是最稀缺的资源，应该花在更有意义的事情上。</code> 以及这个：<a href="https://zhuanlan.zhihu.com/p/2025648183569655286">面向 SGLang 的 Profile Analysis SKILL：3 张表定位 Kernel Fuse 和 Overlap 机会</a>。</p></li><li><p>还不错的画图 skill，<a href="https://github.com/cathrynlavery/diagram-design">diagram-design: Thirteen editorial diagram types for Claude Code. Self-contained HTML + SVG. No shadows, no Mermaid-slop</a>；也有搞笑的 skill，比如这个 <a href="https://github.com/JuliusBrussee/caveman">caveman</a>，省 token 也不是这么省的吧。</p></li><li><p>说到基础工具，<a href="https://gitbutler.com/cli">GitButler</a> 看着也挺有意思的，作者说 github 这种 <code>The old model assumed one person, one branch, one terminal, one linear flow.</code> 他们的则是 <code>Designed to stack branches, to multitask, to control and organize your changes, to easily undo - to be simple, powerful and intuitive, no matter who (or what) you are.</code></p></li><li><p>从卡马克的 <a href="https://x.com/ID_AA_Carmack/status/2044549518465622406">帖子</a> 的评论区看到了这个 <a href="https://o565.com/llm-text-compression/">Using a LLM to compress text</a>，还是蛮有意思的想法，LLM 能预测正确的就不压缩了，只记录预测错误的。</p></li><li><p>Autoresearch 还有后续，<a href="https://x.com/modal/status/2044146413509206379">Autoscaling Autoresearch: Give your agents elastic GPUs</a>，卖铲子的来啦！</p></li><li><p>Lemire 的 <a href="https://x.com/lemire/status/2045138536597279193">The Automation of Nonsense</a>，很真实，太多系统创造的 bullshit job 了，对这种东西拿 AI 应付就是极好的。想到《是大臣》S3E1 里 Sarah 的吐槽：<code>I want a job where I don’t spend endless hours circulating information that isn’t relevant about subjects that don’t matter to people who aren’t interested. I want a job where there is achievement rather than merely activity. I’m tired of pushing paper.</code></p></li><li><p><a href="https://slop.unbound.io/">Unbound Slop</a>，Unbound 主打 SDF 建模，出了这个加上 AI 的版本，看着挺好玩的。</p></li><li><p><a href="https://github.com/PufferAI/PufferLib">PufferLib</a> 给强化学习环境加了 Overcooked，有品位。</p></li><li><p>10x editor 都加入<a href="https://x.com/stewartlynch8/status/2042579283864858926">ai</a>相关功能了，<code>It turns out that AI agents want to use 10x too. They need fast code navigation as much as we do. Stop waiting for AI to grep files and give it access to 10x.</code></p></li><li><p>朋友做的，<a href="https://github.com/LambdaLabsHQ/unity-repl">unity-repl</a>，挺有趣的，大概流程这样 <code>Agent 发 C# 源码，Mono.CSharp 在 Unity Editor Main Thread 上直接求值，Session 里声明的类型和变量跨调用保留，直到 domain reload。</code>确实如他所说，这样的话整个 Editor &#x2F; Runtime API 都是可用工具面。我之前想过有没有可能抽象一个 bash 层给 UE，这么想确实不如 repl 来得好，当然，Unity 毕竟有 C#，UE 似乎也不是不行，考虑到有 Live++ 这种神器。</p></li><li><p><a href="https://zhuanlan.zhihu.com/p/2024896873975031251">AI 融入 Niagara 工作流：从数据理解到制作与优化的全链路实践</a>，可惜我不太懂 Niagara，确实该学学，文章里的思路是对的，导出 json，然后 ai 写 json，然后导回去。AI 因为能看到裸的 hlsl，所以性能优化估计也不错。认同：<code>Niagara 这套系统，本质上是给人用的。</code></p></li><li><p>大致扫了一眼，<a href="https://isolveproblems.substack.com/p/how-microsoft-vaporized-a-trillion?r=7orx5d&utm_campaign=post&utm_medium=web&triedRedirect=true">How Microsoft Vaporized a Trillion Dollars</a>，只能说 OpenAI 包括资本市场确实敏感，可千万不能买 MSFT。</p></li><li><p>看收纳仙人的文章，<a href="https://scottlawsonbc.com/post/dot-system">A Dot a Day Keeps the Clutter Away</a>.</p></li><li><p>来点传统技术，v8 的分享 <a href="https://www.youtube.com/watch?v=LpJ79MxplUk&t=2s">How Many Compilers Is Too Many? A Look at V8’s History, Tradeoffs, and Architectural Choices - YouTube</a>；关于 float，<a href="https://lisyarus.github.io/blog/posts/its-ok-to-compare-floating-points-for-equality.html">It’s OK to compare floating-points for equality</a>，<a href="https://essenceia.github.io/projects/floating_dragon/">Floating point from scratch: Hard Mode</a>；贴图压缩，<a href="https://www.ludicon.com/castano/blog/2026/04/the-true-size-of-astc-textures/">The True Size of ASTC Textures</a>; etw，<a href="https://trainsec.net/library/windows-internals/capture-etw-events-with-c-part-1/">Capture ETW events with C++</a>；<a href="https://github.com/LaurieWired/tailslayer">Tailslayer</a> is a C++ library that reduces tail latency in RAM reads caused by DRAM refresh stalls.</p></li><li><p>在给 Seedance2.0 接 UI 的时候体验测试了下其能力，确实真的很不错。之前自己一直不是很关注生图、生视频这块，确实有空也要看看。</p></li><li><p>港股通终于开了，开始建仓 03441。这波美股反弹也确实是快，没吃满，不过也没事，安全重要。少加班，控制风险，活下去。</p></li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/04/19/curiosity_log_8/</id>
    <link href="https://jsjtxietian.github.io/2026/04/19/curiosity_log_8/"/>
    <published>2026-04-19T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>不知不觉两周又过去了，终于打完了《死亡搁浅 2》，可以回到《追忆似水年华》了。摆烂还是挺开心的，下班之后买菜散步然后打游戏。可惜之后可能没法按时下班了，惨啊，不过正好有时间多看看 AI 相关的东西。蹭了一节公司送的拳击体验课，太爽了！！！那种明明一点力气都没了但依然在教练的]]>
    </summary>
    <title>Curiosity Log 8</title>
    <updated>2026-09-24T07:25:43.276Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
      <![CDATA[<p>最近两周很开心。上周吉林小伙和灰灰这两位朋友分别从北京远道而来，相谈甚欢，也是弥补了去年离职前没能去北京与他们相聚的遗憾。我是很重视人与人之间连结的人，这不是最近正好在玩《死亡搁浅 2》，天天搞基建送快递攒好评，不亦乐乎。因为废寝忘食送快递，普鲁斯特的著作我都没怎么继续读，故事停在了巴尔贝克的海滩，这不又是海，死亡也搁浅在了海滩。另外普鲁斯特对食物的描写极为细致，也符合我的吃货设定。清明也去深圳继续连结新的朋友，真的开心。</p><hr><ul><li>在深圳等位的时候，我和 Gemini 脑暴了一个思想实验，我的疑问大概是：训练语料要到哪个时代，LLM 才能“理解”科学登月？灵感来自几个方面：之前读过的一篇文章说如果只给 LLM 喂古希腊的数据，问它我们该如何登月，LLM 会说月亮是个女神，你没法上去的；<a href="https://simonwillison.net/2026/Mar/30/mr-chatterbox/">Mr. Chatterbox</a> 这个只用维多利亚时代小说训练的模型也给了我点灵感；我以前也和 Gemini 讨论过用前相对论时代的数据训练出的 LLM 能不能推导出相对论，以及 LLM 是不是挑战了康德的先天图式。当然这个问题更特殊一些，假设 LLM 有 web search 这样的工具，训练语料要到哪个时代，LLM 才能“理解”科学登月这一现代科学的成果？当然我都这样问了，不出意外 Gemini 的回答是启蒙时代。这个问题可以往外引申到很多方面，后续我继续在这个问题的框架下聊 LoRA、RL、隐性常识数据、具身智能、范式转移等等。</li><li>然后看到这个问题：<a href="https://www.zhihu.com/question/2020848380708930751/answer/2021716814464328847">大模型输出答案前「思考」的「思维链」机制，本质上是何种原理</a>，答主有言：<code>思维链（COT）本质是让模型能够将最终的输出对齐到pretrain的自然世界的连续知识分布，是模型说给自己看的，不是说给用户看的</code>，很有洞见。</li><li>过去两周最大的事情大概是 Claude Code 源码泄露，然后就有很多文章来分析了，<a href="https://yage.ai/share/claude-code-engineering-cost-20260331.html">AI 工程的真实代价：从 Claude Code 泄露源码看新模型接入的工程现实</a>，<a href="https://zhuanlan.zhihu.com/p/2022389695955346888">Claude Code 完整源码泄露了，花了一天读完全部源码，这是我发现的</a>，<a href="https://x.com/rasbt/status/2038980345316413862">Claude Code’s Real Secret Sauce (Probably) Isn’t the Model</a>，还有手工川的 <a href="https://docs.lovstudio.ai/cc0331">Claude Code 0331 系统报告</a>，等等。简单看了看，记忆、压缩、prompt caching 的小技巧、A&#x2F;B 测试这些都挺有趣的，KAIROS 模式也很 make sense，然后最有启发的可能还是第一篇文章中的：<code>新模型接入的工程成本中，大部分来自模型行为与系统假设之间的不匹配。</code>还有个看着很牛的可视化网页 <a href="https://ccunpacked.dev/">Claude Code Unpacked</a>. </li><li>源码泄露事件配合之前 <a href="https://x.com/bcherny/status/2038454336355999749">Boris Cherny</a> 分享的 Claude Code 小技巧合集，包括 <a href="https://www.anthropic.com/engineering/claude-code-auto-mode">auto mode</a>，感觉还挺有趣。</li><li>Karpathy 的 <a href="https://x.com/karpathy/status/2039805659525644595">LLM Knowledge Bases</a>，后续还共享了一个 <a href="https://gist.github.com/karpathy/442a6bf555914893e9891c11519de94f">llm-wiki</a>，a pattern for building personal knowledge bases using LLMs. Karpathy 还是比我先进（或者说 AI native）多了：<code>Obsidian is the IDE; the LLM is the programmer; the wiki is the codebase... The human&#39;s job is to curate sources, direct the analysis, ask good questions, and think about what it all means. The LLM&#39;s job is everything else.</code> 基本是把阅读、编辑、维护那个 wiki 都交给 LLM 了，确实可以试试。我目前还是手动收集与整理的，可能是因为我觉得读文章的时候顺手记一下也不是啥事儿。</li><li>谷歌发了 <a href="https://blog.google/innovation-and-ai/technology/developers-tools/gemma-4/">Gemma 4: Our most capable open models to date</a>，然后 llama.cpp 和 unsloth 这些基本都是首发就支持了。说到 llama.cpp，其仓库最近达到了 100k star，作者 Georgi Gerganov 在 X 发了 <a href="https://x.com/ggerganov/status/2038632534414680223">长文</a>，描述自己对本地推理的想法与愿景：<code> I believe that there is a certain level of intelligence we as humans can comprehend and meaningfully utilize to improve our working process. Beyond that level, access to more intelligence becomes unnecessary at best and counterproductive at worst.</code> 然后评论区也讨论到了关于本地模型的效果问题，<code>From typing the task in the client to the actual result, there is a long chain of components that atm are not only fragile - are also developed by different parties.</code> 我个人觉得除了隐私以外，本地模型确实更可控 + 延迟更低。</li><li>Jeff Dean 和 Bill Dally 的<a href="https://www.youtube.com/watch?v=g8BuAtM3fp4&t=1s">访谈</a>，里面提到尽管文本数据增长放缓，但世界上仍有海量未被充分利用的数据（包括视频、音频、真实的机器人传感器数据以及由强大 AI 生成的高质量合成数据），所以谷歌狂做多模态也确实理由充分。另外两个有趣的，一是针对长 context 问题，他们认为未来的方向可能是采用分层检索或聚类注意力机制，在海量信息库中快速定位最相关的百万 token 范围；二是英伟达有个专门用历史设计文档和专有数据微调出的大语言模型，能够精准回答工程师关于特定硬件模块的复杂问题，很有启发。</li><li>最近的热词 Harness: <a href="https://yage.ai/share/harness-engineering-scalability-20260330.html">Harness Engineering 在讨论什么</a>，<a href="https://zhuanlan.zhihu.com/p/2021229438939965162">Harness Engineering 时代的失败经验</a>，<a href="https://github.com/langchain-ai/deepagents">deepagents: Agent harness built with LangChain and LangGraph</a>.</li><li>好文，<a href="https://mariozechner.at/posts/2026-03-25-thoughts-on-slowing-the-fuck-down/">Thoughts on slowing the fuck down</a>，好比喻，又见荷马史诗：<code>Coding agents are sirens, luring you in with their speed of code generation and jagged intelligence, often completing a simple task with high quality at breakneck velocity.</code> 然后这里写的也蛮好，适合给 agent 的 task 的特点：<code>they can be scoped so the agent doesn&#39;t need to understand the full system. The loop can be closed, that is, the agent has a way to evaluate its own work. The output isn&#39;t mission critical, just some ad hoc tool or internal piece of software nobody&#39;s life or revenue depends on.</code> 我觉得很多人是活在未来的人，他们想的是未来会如何如何，他们也身体力行去做了；但当现实还没准备好的时候，可能就显得是“爆论”，可能看着不如 slow the fuck down。所以我个人一般只当跟随者，不是一线的，但是步频 180 跟着，感受风往哪里去。</li><li>其他关于 agent 的讨论：<a href="https://github.com/onevcat/2026-let-s-vision">AI Agent 的道与术</a> 里面提的用自然语言让 AI 生成 test case 还挺有意思的；<a href="https://john.regehr.org/writing/zero_dof_programming.html">Zero-Degree-of-Freedom LLM Coding using Executable Oracles</a>: <code>When an LLM has the option of doing something poorly, we simply can’t trust it to make the right choices. The solution, then, is clear: we need to take away the freedom to do the job badly</code>, 一方面是给它自由，一方面也要约束；<a href="https://zhuanlan.zhihu.com/p/2019826804764979414">记录下 SGLang 开发，优化，debug 的技巧之大 SKILL 时代已来临</a>：<code>在推理框架、kernel 优化、模型适配这些复杂场景里，稀缺的早就不只是&quot;会写代码&quot;，而是&quot;知道该优化什么、瓶颈大概在哪、怎么设计一个稳定可复用的流程&quot;。Agent 确实能把事情做得飞快，但它需要目标清晰、资料齐全、验证标准过硬</code>；赞美，大肆赞美，<a href="https://randsinrepose.com/archives/better-faster-and-even-more/">Better, Faster, and (Even) More</a>；<a href="https://blog.exe.dev/bones-of-the-software-factory">Everyone is building a software factory</a>，愿景真不错；Memory 的总结 <a href="https://x.com/yoheinakajima/status/2037201711937577319">The state of AI memory systems</a>。</li><li>挺有趣的研究 <a href="https://arxiv.org/abs/2602.09345">AgentCgroup: Understanding and Controlling OS Resources of AI Agents</a>，看了下 AI Agent 在跑的时候的占用的资源情况，<code> Our measurements reveal that (1) OS-level execution (tool calls, container and agent initialization) accounts for 56-74% of end-to-end task latency; (2) memory, not CPU, is the concurrency bottleneck...</code> 说实话也是意料之中，倒也不能直接说是 云端的 GPU 就在等 CPU 和 内存，而更像是，现在的基础设施确实还不是给 Agent 大量优化的，这不是经常看到有人搞了新的给 agent 的搜索工具，比如 cursor 的 <a href="https://cursor.com/cn/blog/fast-regex-search#all-this-in-your-machine">快速正则搜索：为 agent 工具构建文本索引</a>，然后被喷 <a href="https://x.com/neogoose_btw/status/2036580938411548710">The largest manipulation in the benchmarking history uncovered</a>.</li><li><a href="https://linear.app/developers/aig">Agent Interaction Guidelines (AIG)</a> 里提炼了一些还不错的 agent 设计原则，比如<code>An agent should be clear and transparent about its internal state</code>；这里也有一些更具体的建议：<a href="https://x.com/ericzakariasson/status/2036762680401223946">Building CLIs for agents</a>.</li><li><a href="https://www.humanlayer.dev/blog/long-context-isnt-the-answer">Long-Context Isn’t the Answer</a>，洞见：<code>More context isn&#39;t more capability - the instruction budget doesn&#39;t scale with the context window.</code> 指令遵循能力很重要。相关的，<a href="https://www.philschmid.de/kimi-composer-context">How Kimi, Cursor, and Chroma Train Agentic Models with RL</a>，<code>Context management is a first-class problem. Cursor uses self-summarization. Kimi shards context across parallel sub-agents. Chroma teaches the model to discard irrelevant chunks. Different solutions, same underlying constraint.</code></li><li>说到 <a href="https://www.trychroma.com/research/context-1">Chroma Context-1</a>: <code>a 20B parameter agentic search model derived from gpt-oss-20B that achieves retrieval performance comparable to frontier-scale LLMs at a fraction of the cost and up to 10x faster inference speed.</code> 很有趣的领域小模型，说到小模型还有这个，<a href="https://huggingface.co/Jackrong/Qwen3.5-27B-Claude-4.6-Opus-Reasoning-Distilled">Qwen3.5-27B-Claude-4.6-Opus-Reasoning-Distilled</a>，感觉看名字就很厉害。以及关于量化的，<a href="https://x.com/Brooooook_lyn/status/2037532299382882794">Why MLX Quantized Models Underperform Unsloth GGUF</a>: <code>The root cause is uniform quantization... The solution is per-tensor mixed-bit quantization — assigning each weight tensor a precision level based on its actual sensitivity. This is what Unsloth&#39;s Dynamic 2.0 recipe does for GGUF, and what we&#39;ve ported to MLX.</code> </li><li>Junyang Lin 的新文章：<a href="https://x.com/JustinLin610/status/2037116325210829168">From “Reasoning” Thinking to “Agentic” Thinking</a>，确实可能是未来的方向。</li><li>Simon Willison 参加的播客的<a href="https://simonwillison.net/2026/Apr/2/lennys-podcast/">文字稿</a>，没啥特别新的东西，提到 <code>Software engineers as bellwethers for other information workers</code>，那确实，如果 AI 大势所趋，确实程序员是在第一线（也是死在第一线的）。</li><li><a href="https://brooker.co.za/blog/2026/03/25/ic-junior.html">What about juniors</a>: <code>The high level is fairly clear: the new junior path engages much earlier with economics, product, and people, has less emphasis on the practice of the craft of programming, but more emphasis on the deep technology and science behind the systems we are building.</code> 唉，可我就是 junior，好累。</li><li>每天都有更多人在用 AI 帮助自己，比如 Paint.NET 作者<a href="https://x.com/rickbrewPDN/status/2039850858935140449">说</a>：<code>Claude Code just helped make a very important scenario in Paint.NET about 95% faster: Copy. To. Clipboard.</code> 可能更重要的是：<code>I could have done this all myself, but it would have taken a lot longer. More importantly, it just would not have happened.</code></li><li>还有这个 <a href="https://www.john-rush.com/posts/eggs-25-years-20260219.html">25 Years of Eggs</a>，用 AI 帮助自己处理 25 年来收集的购物小票以追踪鸡蛋的价格变化，非常有趣。不出意外，<code>Codex and Claude are excellent at building tools and extracting structured data, but they couldn’t segment an image or replace an OCR engine. The right answer was a stack of specialized models - SAM3 for segmentation, PaddleOCR for text, Codex and Claude for everything else. I expected this, but it was worth trying the simple path first.</code></li><li>最近发现的新东西，比如<a href="https://x.com/imedwardluo/status/2039729625157537978">Vibe Island</a>，把 agent 的工作状态丢到 Mac 的灵动岛上了，还挺有意思的；卡比的 <a href="https://opencli.info/blog/opencli-emacs-for-agents?lang=zh">OpenCLI：AI Agent 的 Emacs</a>，啥时候游戏引擎有个类似 bash 或者 emacs 的东西就好了；<a href="https://slock.ai/">Slock - Where humans and AI agents collaborate</a>，玩了下，挺有趣的想法和界面；<a href="https://github.com/11cafe/jaaz">jaaz</a>，很有趣的 AI Canvas；<a href="https://github.com/ssrajadh/sentrysearch">sentrysearch</a>，用原生多模态模型来做视频的语义搜索；<a href="https://cs153.stanford.edu/">CS 153: Frontier Systems</a>，平等嫉妒所有斯坦福的人；<a href="https://github.com/openai/codex-plugin-cc">codex-plugin-cc</a>，Use Codex from Claude Code to review code or delegate tasks；<a href="https://github.com/genymobile/scrcpy">scrcpy</a>，我咋没早点发现这个，直接把安卓手机投屏到电脑上。</li><li><a href="https://michaelnotebook.com/whichfuture/">Which Future?</a> 很思辨的文章，讨论我们人类面对超级人工智能所面临的生存风险，里面谈到 AI 的 alignment: <code>In this sense, (much) technical alignment is a kind of &quot;market-supplied safety&quot;, aligned with corporate goals, and helping accelerate AI... Governance and policy is only a small part of the external alignment work that is required. And external alignment – that is, making reality outside the system safe – is historically far more expensive, far slower, and far less incentivized by the market.</code></li><li>大热的 <a href="https://research.google/blog/turboquant-redefining-ai-efficiency-with-extreme-compression/">TurboQuant</a> 以及其争议：<a href="https://zhuanlan.zhihu.com/p/2020969476166808284">对于 Google 的 ICLR 2026 TurboQuant 论文，我们必须公开澄清</a>。</li><li>还不错的工具文章，算本地模型要多少显存：<a href="https://x.com/TheAhmadOsman/status/2040103488714068245">GPU Memory Math for LLMs (2026 Edition)</a>。</li><li>Anthropic 的新文章 <a href="https://www.anthropic.com/research/emotion-concepts-function">Emotion concepts and their function in a large language model</a>，可和《情绪》这本讲人的书对照。</li><li><a href="https://x.com/lemire/status/2038980780278403382">Daniel Lemire</a> 发文吐槽：<code>the person could have asked ChatGPT, Grok, Claude, or even Copilot and gotten the correct information instantly. They didn’t, because they don’t care to know... Meanwhile, please, for the love of God, if don&#39;t know a topic at least as well as ChatGPT, don&#39;t speak as an expert.</code> 大模型时代又咋了，比得过权力吗。</li><li>notch 在 <a href="https://x.com/notch/status/2039561278495068337">X</a> 上喷：<code>DLSS fundamentally makes no sense. Because the graphics card is too slow to run the game at reasonable speeds, you use THE SAME HARDWARE to run a neural network to generate frames in between the existing ones</code>，然后引发了一些讨论，比如 Sebastian 的<a href="https://x.com/SebAaltonen/status/2039759360994300224">评论</a>，Casey 也录了一期<a href="https://www.computerenhance.com/p/my-thoughts-on-notchs-dlss-post">视频</a>说这个。一针见血：<code>DLSS was the killer AI app for Nvidia. Allowed Nvidia to ship full tensor hardware to consumer chips. Otherwise tensor cores would have been dead silicon for gaming.</code> 硬件都在那儿，不用也是浪费，虽然我个人不是很喜欢糊糊的那种画面。</li><li><a href="https://x.com/jzh_000/status/2039086919238185307">AgenticPCG</a>: <code>We combine classic PCG (Procedural Content Generation) algorithms with large language models for generating game levels. LLMs on their own are not good at level generation, but when given the right tools from our PCG toolbox they&#39;re killing it!</code> 思路很合理，不过 demo 似乎稍微简单了些。</li><li><a href="https://github.com/Italink/UnrealClientProtocol">UnrealClientProtocol</a>，感觉这个路径（不是手动选择暴露给 AI 的功能，而是把引擎本身的接口交给 AI）上的项目在变多，也合理，游戏引擎本身的复杂度让 MCP 这种方案显得很无力。不过据我个人经验，至少 AI 对 UE 的理解还是很陈旧的，不能纯靠自身的知识，还是要在源码里工作比较好，毕竟并非所有接口都会通过反射默认暴露。然后这里有用 AI 做 code review 的分享：<a href="https://zhuanlan.zhihu.com/p/2012296278969704777">UE 大型团队如何用 Claude 做自动 Code Review</a>，Code RAG + Blueprint RAG，两套 RAG 共用一个向量数据库和 MCP Server，感觉也是不错的工程化实践。</li><li><a href="https://github.com/wuhao21/sts2-cli">Headless Slay the Spire 2 CLI</a>，杀戮尖塔的 cli，非常有创意，要是所有游戏都可以整出 cli 然后让 AI 帮玩就好了，咱就不说测试了，有个 AI 来当队友也不错。</li><li><a href="https://www.jsnover.com/blog/2026/03/13/microsoft-hasnt-had-a-coherent-gui-strategy-since-petzold/">Microsoft Hasn’t Had a Coherent GUI Strategy Since Petzold</a>，感觉一直都能看到微软吐槽大会，也许股价暴跌也是一种必然</li><li><a href="https://medium.com/@reinigdavid/old-school-rendering-rant-tomb-raider-913f7837de7e">Old school rendering rant - Tomb Raider</a>，来点真传统的渲染技术，以及这个，<a href="https://www.copetti.org/writings/consoles/">Architecture of Consoles</a>，各种老游戏机的架构</li><li>这篇 <a href="https://www.ludicon.com/castano/blog/2026/03/hardware-image-compression/">Hardware Image Compression</a> 讨论了各家硬件图像压缩格式的优劣，<code>ARM&#39;s AFRC is the clear winner</code>，更真实的是这个：<code>One of the things I’ve always lamented about hardware image formats is the slow pace of innovation. Developers were usually unwilling to ship textures in a new format unless that format was widely available.</code></li><li><a href="https://x.com/lemire/status/2037944251485388889">How stagnant is CPU technology</a>，CPU 同理，<code>Not all software can easily run much faster on new processors, and genuine progress is difficult.</code> Intel 最近有个 Intel Binary Optimization Tool 看着也挺有意思的。</li><li><a href="https://x.com/SheriefFYI/status/2037401422850121776">SheriefFYI </a> 发问，how do people debug game logic in ways other than using lots and lots of printf() logging and debug draw gizmos? 评论区有一些想法，但不多。</li><li>从 axios 被投毒联系到的：<a href="https://blog.yossarian.net/2025/11/21/We-should-all-be-using-dependency-cooldowns">We should all be using dependency cooldowns</a>，确实不能太急。</li><li>Codex App 太难用了，我经常遇到丢数据啥的，回到 terminal 了。当然模型本身还是很智能的，有群友拿它来破解软件的激活码，还能自己截图自己 debug，真好。前端上确实差了点，主要是默认咋就是疯狂的卡片样式，不美观，最近在让 gpt-5.4 vibe 的股票看板就是，丑。</li><li>遇到这种科技革命，我想的是，对我这种普通人而言，尽量远离风险，尽量活下去。</li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/04/07/curiosity_log_7/</id>
    <link href="https://jsjtxietian.github.io/2026/04/07/curiosity_log_7/"/>
    <published>2026-04-07T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>最近两周很开心。上周吉林小伙和灰灰这两位朋友分别从北京远道而来，相谈甚欢，也是弥补了去年离职前没能去北京与他们相聚的遗憾。我是很重视人与人之间连结的人，这不是最近正好在玩《死亡搁浅 2》，天天搞基建送快递攒好评，不亦乐乎。因为废寝忘食送快递，普鲁斯特的著作我都没怎么继续读，]]>
    </summary>
    <title>Curiosity Log 7</title>
    <updated>2026-09-24T07:25:43.275Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
      <![CDATA[<p>更新迟到了几天，因为周末去三亚参加好朋友波博的婚礼了！现在三亚的天气不错，婚礼也很迷人，觉得自己穿上西装也是人模狗样的。周六晚上我们几个软院遗老一起大富翁到三点钟，也是很舒适了，真希望这样的时光更长一些。就是感觉周日逛的水族馆的水分有点多，30 分钟就逛完了，另外看到真人扮演成美人鱼在水里表演总感觉不是很舒适，明明已经是是水族馆了，还玩把人当成景观客体这一套，真没意思。</p><p>最近读到了《追忆似水年华》的第二卷《在少女们身旁》，顺带着还读了点《普鲁斯特的空间》。慢慢熟悉了普鲁斯特的写法，毕竟我早已受到了一些更后期的文学的熏陶，而且从第一卷的第二部分斯万之恋开始，写法又变得很线性了，就慢慢读吧。真怀念上学时候的读书会呀，读《骑兵军》《小城畸人》等等。</p><p>对象 Vibe Coding 出来的奶茶记录网页：<a href="https://milk-tea-tracker.netlify.app/">奶茶记录</a>，AI 带来的工具民主化真好啊（虽然她还是没法停下喝奶茶）。Vibe Coding 确实令人上瘾，token 翻译为代币吧，对应 AI 就是老虎机。</p><hr><ul><li><p>好酷，必须第一个介绍，<a href="https://x.com/danveloper/status/2034353876753592372">Autoresearching Apple’s “LLM in a Flash” to run Qwen 397B locally</a>：<code>The entire 209GB model streams from SSD through a custom Metal compute pipeline.</code> 本地能跑 397B 的 Qwen 模型了，想法不错，Apple 的硬件也是真的不错。个人想法，在这个意义上 Apple 是不是可以算是 Local LLM 这一派的硬件厂商？等最近风头过了就建仓 Apple。</p></li><li><p>关于 karpathy 的 <a href="https://github.com/karpathy/autoresearch">autoresearch</a>，同意 <a href="https://registerspill.thorstenball.com/p/joy-and-curiosity-78">Thorsten Ball</a> 的看法：<code>The idea of running an agent in a loop isn’t new, but what I find fascinating: how small this repo is, how small the codebase is, how direct and clear the instructions and the workflow are, and the meta thing of this being exactly what the non-nano researchers at the big labs are doing, at least kind of.</code> 这里也有用来做算子优化的，<a href="https://zhuanlan.zhihu.com/p/2017212755590005622">如何用 Opus 4.6 写出一个比开源社区更快的 gpu 算子</a>，有来优化内存分配的，<a href="https://github.com/Shopify/liquid/pull/2056">Performance: 53% faster parse+render, 61% fewer allocations</a>.</p></li><li><p><a href="https://www.youtube.com/watch?v=jw_o0xr8MWU&t=4438s">NVIDIA GTC Keynote 2026</a>，只看懂了这个：<code>Inference is the Workload, Tokens are the New Commodity, Compute is Revenue.</code>其他硬件相关的基本没看懂。除了老黄的还有这个 <a href="https://www.youtube.com/watch?v=mDG_Hx3BSUE">The single biggest bottleneck to scaling AI compute</a>，电力和土地不太会是限制，也许到 2030 年，最大的瓶颈将回归到芯片制造本身（ASML 的 EUV 光刻机），还有内存危机似乎也没到结束的时候。</p></li><li><p>认真研读了 Unsloth 创始人的访谈：<a href="https://www.youtube.com/watch?v=v9c00Ty5Z7U&t=4142s">LLMs for Everyone | Pre-training, Fine-Tuning, Scaling RL, Open Source</a>，热情满满，被感染到了，所以我现在也准备去看看 Unsloth 的教程玩玩微调了（当然作者是推荐不要每个热点都追的，太容易疲劳了，应该专注自己感兴趣的一个小方面）；作者还建议徒手推导反向传播试试，也是个 todo 了。Unsloth 也出了个 <a href="https://x.com/UnslothAI/status/2033926272481718523">Unsloth Studio</a>，更一体化了，可以玩玩。</p></li><li><p><a href="https://blog.colinbreck.com/adapting-to-ai-reflections-on-productivity/">这里</a>有个不错的比喻，用 AI 就像是在一家无限量供应热狗的公司工作，AI 让你胃口大开，但如果不懂得自我调节，这种无限的产出会让人筋疲力尽。以及老生常谈的：<code>Context switching is antithetical to the optimal experience of flow and AI tends to encourage context switching.</code> </p></li><li><p><a href="https://zhuanlan.zhihu.com/p/2018257242286209022">eval + builtins：比 tools 更好的 Agent 架构范式</a>，我基本也是这个想法，可惜 UE 的那个 Python 脚本绑定因为训练数据量太小了，用起来还是不太行。很早用的这个 <a href="https://github.com/jackwrichards/UnityMCP">UnityMCP</a> 也是这个思路，此想法在 <a href="https://zhuanlan.zhihu.com/p/2000790356535559443">Tool Call 的未来</a> 也有所指。</p></li><li><p><a href="https://github.com/svnscha/mcp-windbg">mcp-windbg</a> 又救我命，有个修改了虚表导致的 ABI 不一致的 bug 就是靠 gpt-5.4 + WinDBG MCP 查出来的，听说 <a href="https://github.com/plasma-umass/ChatDBG">ChatDBG</a> 也不错，但似乎只支持 gdb 和 lldb。</p></li><li><p>读了 Claude Code 官方的一些文章，<a href="https://x.com/trq212/status/2033949937936085378">Lessons from Building Claude Code: How We Use Skills</a> 确实是还不错的综述，喜欢这两句：<code>If you’re publishing a skill that is primarily about knowledge, try to focus on information that pushes Claude out of its normal way of thinking</code> 和 <code>Give Claude the information it needs, but give it the flexibility to adapt to the situation</code>. 也补了下去年的 <a href="https://www.anthropic.com/engineering/multi-agent-research-system">How we built our multi-agent research system</a>.</p></li><li><p><a href="https://www.theguardian.com/technology/2026/feb/25/tech-legend-stewart-brand-on-musk-bezos-and-his-extraordinary-life-we-dont-need-to-passively-accept-our-fate">Tech legend Stewart Brand on Musk, Bezos and his extraordinary life</a>: <code>The strapline of the Whole Earth Catalog was “access to tools”, and it was meant in the broadest sense.</code> 他很强调 Maintenance, 很有趣，联系到 <a href="https://x.com/badlogicgames/status/2033798602372288947">Mario Zechner on X</a>: <code>keeping the complexity off the bay is really hard, espwcially if you go full agent orchestration.</code></p></li><li><p>关于 benchmark 的反思，<a href="https://florianbrand.com/posts/benches-2026">Quo vadis, LLM benchmarks</a>，<code>Benchmarks are not meant to be taken at face value, but rather indicate the (relative) strengths of models and the general progress in the respective area of the benchmark... However, it is important to know what benchmarks are for and to look at the implementations (and data) of benchmarks to know what it measures and within which constraints it measures.</code></p></li><li><p><a href="https://tomtunguz.com/local-vs-cloud-speed/">The Robotic Tortoise &amp; the Robotic Hare</a> 有个实验还挺有意思的，Qwen 35B 竟然“打败”了 Claude Opus 4.5，<code>Faster responses mean more rounds of revision before a meeting ends or attention drifts. It’s different for agentic coding workflows &amp; complex codebases, where slower work may lead to better outcomes. But for everyday tasks, faster models can enable tighter feedback loops. Tighter loops can produce better outcomes.</code> 一方面当然是本地模型也大有可为，另一方面这也是我们做性能优化的意义所在，不仅仅包括 LLM 的推理优化，也包括相关的工具优化。</p></li><li><p>说到大模型和小模型，这篇 paper 还是挺有意思的，<a href="https://www.alphaxiv.org/abs/2603.12228">Diverse Task Experts Are Dense Around Pretrained Weights</a>. </p></li><li><p>看不懂但是好厉害：<a href="https://kexue.fm/archives/11664">Attention Residuals 回忆录</a>。</p></li><li><p>一些可视化集合：<a href="https://magazine.sebastianraschka.com/p/visual-attention-variants">A Visual Guide to Attention Variants in Modern LLMs</a>，<a href="https://www.vizuaranewsletter.com/p/vision-transformers">Vision Transformers - by Mayank Pratap Singh</a>，<a href="https://sebastianraschka.com/llm-architecture-gallery/">LLM Architecture Gallery</a></p></li><li><p><a href="https://blog.platformatic.dev/why-nodejs-needs-a-virtual-file-system">Why Node.js Needs a Virtual File System</a>: <code>Without AI, this would not have been a holiday side project. It just wouldn’t have happened.</code></p></li><li><p>新看到的一些不错的工具：<a href="https://x.com/kepano/status/2034374124269940898">Obsidian Reader</a>，UCLA AGI Lab 的 <a href="https://github.com/eurekaclaw/eurekaclaw">EurekaClaw</a>，<a href="https://github.com/ast-grep/ast-grep">ast-grep</a>，给 Agent 的浏览器 <a href="https://github.com/lightpanda-io/browser">Lightpanda</a>，专门给 AI 搞了 MCP 的 <a href="https://jbachorik.github.io/posts/stackprofile-jfr">stackprofile</a>，浏览器的 Agent <a href="https://github.com/badlogic/sitegeist">sitegeist</a>，<a href="https://github.com/ChromeDevTools/chrome-devtools-mcp">chrome-devtools-mcp</a>等等</p></li><li><p><a href="https://www.helenmin.com/blog/software-is-becoming-more-honest">Software isn’t dying, but it is becoming more honest</a>：<code>Software isn’t dying; it’s just getting more honest. We’re moving toward a world where we pay for the work (the base) and the value (the outcome).Subscription-based billing won&#39;t remain the standard, and that’s actually a win for everyone… </code></p></li><li><p><a href="https://lucumr.pocoo.org/2026/3/20/some-things-just-take-time/">Some Things Just Take Time</a>，另外这篇也不错，<a href="https://blog.s-schoener.com/2026-03-18-not-about-the-typing/">It has never been about the typing</a>: <code>Identity requires some sort of “what makes me different from everyone else”, and a lot of these differentiators have been obliterated lately</code>.</p></li><li><p>LLM 对这种小创作者的影响值得关注，<a href="https://beyondloom.com/blog/onwigglypaint.html">Some Words on WigglyPaint</a> : <code>NONE of these sites are created by me, or with anything remotely resembling my permission. The sites are *slop*; slapdash imitations pieced together with the help of so-called “Large Language Models” (LLMs). The closer you look at them, the stranger they appear, full of vague, repetitive claims, outright false information, and plenty of unattributed (stolen) art. This is what LLMs are best at: quickly fabricating plausible simulacra of real objects to mislead the unwary.</code> 一方面是创作民主化，一方面是 slop 泛滥，有趣。</p></li><li><p>竟然已经有这种 AI 语气收集了：<a href="https://gist.github.com/ossa-ma/f3baa9d25154c33095e22272c631f5a1">AI Writing Tropes to Avoid</a>，最近用 gpt-5.4 深有所感。</p></li><li><p><a href="https://www.dbreunig.com/2026/02/21/why-is-claude-an-electron-app.html">Why is Claude an Electron App?</a>  作者的回答：<code>Some of the engineers working on the app worked on Electron back in the day, so preferred building non-natively. It’s also a nice way to share code so we’re guaranteed that features across web and desktop have the same look and feel. Finally, Claude is great at it.</code> 另外，<a href="https://tonsky.me/blog/fall-of-native/">Claude is an Electron App because we’ve lost native</a>， <a href="https://domenic.me/windows-native-dev/">Windows Native App Development Is a Mess</a>，确实如此。</p></li><li><p>大佬发话：<a href="https://x.com/SebAaltonen/status/2035005805691371778">Turns out that DLSS5 was after all a generic Snapchat beautify post filter. No per pixel developer control</a>，笑死我了。Neural texture 确实是个不错的想法，但啥时候能有统一的标准和接口呢？又有，<a href="https://x.com/SebAaltonen/status/2033916147364425736">Sebastian Aaltonen on X</a>: <code>Codex was a massive help in the porting, but if you want high performance result, you need to validate everything, use GPU debugger and GPU profiler, etc. Know what is the best data layout and explain that to the LLM, etc. Good AGENTS.MD rules helps of course. But doesn&#39;t solve.</code></p></li><li><p>制作人推荐了这个《羊蹄山之魂》的<a href="https://mp.weixin.qq.com/s/rklgtYGoQctErPl88cPmTQ">分享</a>，利用事件卡组的思路来进行任务节奏控制，规划开放世界的内容释放逻辑，确实是蛮不错的思路。我下意识就想到了这不是和推荐系统很像么，玩家经历过的事件就是历史的数据，基于这个去选择要推荐的游戏内容，当然游戏的不同之处在于有个主线系统。现在是 LLM 的天下，也可以考虑用大模型来做推荐，或者是定时发数据去云端，或者本地跑个 8B 模型，感觉都很有搞头。</p></li><li><p><a href="https://www.youtube.com/watch?v=fXakIV1OFes">Visibility Buffer and Deferred Rendering in DOOM: The Dark Ages</a>，DOOM 也换 Visibility Buffer 和 Deferred Rendering 了，还记得以前学它那个 Forward+ 的时候，也忘光了其实。</p></li><li><p>Eric Lengyel 大佬关于高性能字体渲染的博客：<a href="https://terathon.com/blog/decade-slug.html">A Decade of Slug</a>，说来他那几本关于游戏引擎的书我还一直没看呢。。。</p></li><li><p>Superluminal 的新文章：<a href="https://rovarma.com/articles/a-tale-about-fixing-ebpf-spinlock-issues-in-the-linux-kernel/">A tale about fixing eBPF spinlock issues in the Linux kernel.</a></p></li><li><p>学点虚拟内存技巧也不错，<a href="https://www.computerenhance.com/p/powerful-page-mapping-techniques">Powerful Page Mapping Techniques.</a></p></li><li><p>jemalloc 复活了，<a href="https://engineering.fb.com/2026/03/02/data-infrastructure/investing-in-infrastructure-metas-renewed-commitment-to-jemalloc/">Investing in Infrastructure: Meta’s Renewed Commitment to jemalloc</a>.</p></li><li><p>关于时间，<a href="https://bloomberg.github.io/js-blog/post/temporal/">Temporal: The 9-Year Journey to Fix Time in JavaScript</a>.</p></li><li><p><a href="https://x.com/lemire/status/2034393396777796077">How many branches can your CPU predict</a>，测量方法是真的不错，给 CPU 上压力看看它能记住多少长度的随机序列，AMD YES！另外注意到了 Lemire 大佬用的库 <a href="https://github.com/lemire/counters">counters: performance counters in C++</a> 没有 Windows 支持，相似的 <a href="https://github.com/jmuehlig/perf-cpp">perf-cpp</a> 也没有。</p></li><li><p>神人字体 <a href="https://github.com/nevesnunes/z80-sans">z80-sans</a>，把汇编做进了字体里，牛，太牛了。</p></li><li><p><a href="https://x.com/sonofalli/status/2033651124520292795">good people don’t get blocked</a>，唉，确实，要 get the job done 才是本事。</p></li><li><p><a href="https://sharif.io/looking-stupid">Willingness to look stupid is a genuine moat in creative work</a>: <code> Good Ideas, and I mean this in the broadest sense – research directions, startup ideas, premises for a novel – almost always sound stupid at first. They often make the person who came up with them look stupid. So if a truly *Good Idea* always starts out by looking unserious, then the only way to have one is to get comfortable producing stupid things.</code> 另外，<code>Your goal shouldn’t be to share something good. It should just be to share something *at all*. Even if it isn’t good.</code> 可能这也是 Curiosity Log 的初衷之一，最近更新倒是都很即时，但确实挤压了我写其他文章的时间，唉，时间。</p></li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/03/24/curiosity_log_6/</id>
    <link href="https://jsjtxietian.github.io/2026/03/24/curiosity_log_6/"/>
    <published>2026-03-24T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>更新迟到了几天，因为周末去三亚参加好朋友波博的婚礼了！现在三亚的天气不错，婚礼也很迷人，觉得自己穿上西装也是人模狗样的。周六晚上我们几个软院遗老一起大富翁到三点钟，也是很舒适了，真希望这样的时光更长一些。就是感觉周日逛的水族馆的水分有点多，30 分钟就逛完了，另外看到真人扮]]>
    </summary>
    <title>Curiosity Log 6</title>
    <updated>2026-09-24T07:25:43.275Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Diary" scheme="https://jsjtxietian.github.io/tags/Diary/"/>
    <content>
      <![CDATA[<p>将近半年前我写了 <a href="https://jsjtxietian.space/2025/11/15/ai_2025_11/">我如何使用 AI (2025.11 版) </a>，当时就觉得估计是要过几个月就更新的，这不是正好我玩杀戮尖塔 2 有点丧气了（这种游戏我真是又菜又爱玩），来补一下文章。</p><p>前几天想了下，我现在对 AI 的需求，大概可以分为这么四类：</p><ol><li>日常聊天</li><li>高智商问题解决</li><li>编程</li><li>一些其他需求，比如阅读</li></ol><h3 id="日常聊天"><a href="#日常聊天" class="headerlink" title="日常聊天"></a>日常聊天</h3><p>对于基本的日常对话而言，我期望模型有不错的智商、优秀的多模态能力和广博的世界知识，然后使用起来要足够方便，有手机 app，可以随时问。现在我主要是用 Gemini Chat, 网页和 app 都用，偶尔用用 Perplexity。</p><p>个人觉得这里的玩法解锁，主要是看自己的生活与 AI 融合有多深。我会和 Gemini 学习健身减脂，拍配料表让它告诉我哪种意面比较好，让它帮我总结长篇文章或者播客，翻译游戏攻略，找刚写完的博客的错别字，用 Slidev 画 PPT，回忆 git 或者 ssh 某个我忘掉的命令，帮我 fact check 某个事实，和我聊聊我读到的某篇文章&#x2F;某个观点的其他角度，和他聊我各种各样异想天开的想法等等。最近 DeepResearch 倒是用的少了，可能没那么深度的需求了（其实是文章写少了）。</p><p>彻底弃用了 Kimi、Qwen 等，倒不是因为它们模型的智商不行，最主要的还是信息墙，优质的中文内容都在各个厂商的护城河后面，如果模型抓不到的话，那还真不如去小红书搜了。其他倒都是小问题，Kimi 简洁优雅，但是之前用的时候 app 天天限额；Qwen 天天让我点外卖，我看着烦。</p><h3 id="智商高地"><a href="#智商高地" class="headerlink" title="智商高地"></a>智商高地</h3><p>一般针对比较难的问题，需要最强大的模型，这种时候不计成本，需要的是智商，这种需要 ai studio 的满血&#x2F;不降智版本的 Gemini，勾选上 Grounding with Google Search 和 Code Execution, 效果很好。目前每天免费额度倒是还够，但我也不排斥真金实银去按 api 调用付费去用。</p><h3 id="编程"><a href="#编程" class="headerlink" title="编程"></a>编程</h3><p>现在主要是用 Windows 上的 Codex App，选 gpt 5.4 + thinking high, 目前还没开 1M 上下文的模式。</p><p>整体来说体验还是蛮好的，读 UE 源码没啥问题，好好给各个仓库配置好 AGENTS.md，然后遵循一些其他的最佳实践，很舒服。基本大部分时候是异步的工作模式，我干其他的，让 AI 先去代码库里探索。gpt-5.4 还是需要调教下 prompt，我体感默认情况下废话太多了，<a href="https://x.com/OnlyXuanwo/status/2032139006230790183">Xuanwo</a> 有一些推荐。当然，Windows 上 Codex 的沙盒有 bug，比如<a href="https://github.com/openai/codex/issues/13965">这个</a>和<a href="https://github.com/openai/codex/issues/13542">这个</a>，所以目前体验很一般（毕竟刚出，可以给点时间再观察下），其它倒是还好。然后也越来越大胆了，我最开始还是 Read Only 的权限，现在直接开 Full Access 了，信任确实是慢慢积累的。</p><p>游戏仓库本身不是很 agent friendly 是个问题，如何让仓库更 agent 友好、如何弄好 harness 都是大家在积极探索的方向。但奈何我没啥精力去大力推进这些，只能自己遇到一个问题解决一个问题（比如之前写了 skill 让 Codex 帮我看 js 的火焰图，结合代码优化）。也有用 Claude Agent SDK 简单做点东西玩玩，我测试的话就简单接了 deepseek 的 api，量大管饱不心疼钱，大部分时候的效果也确实不错。</p><p>上次文章里还说到想要 UE 的 deepwiki，其实这还是个挺有趣的问题，就是如果 AI 能够每次都能通过读代码去准确地生成这份知识，那这份知识有必要存下来吗，具体到这里就是说，UE 的 deepwiki 是个伪需求吗？我个人理解，deepwiki 这里其实包含了个知识沉淀的作用，那我假如不考虑 token 成本的话，似乎优势就在于比较省 context + 延迟比较低了，依然是有价值的，但维护的成本也不低。</p><p>总结就是，彻底拥抱 Agentic Engineering！AI 相比我的优势还是太大了，这阅读代码的 bandwidth、对一些细节的注意、百折不挠的精神，我确实比不过啊。</p><h3 id="其他"><a href="#其他" class="headerlink" title="其他"></a>其他</h3><p>在读书方面，我彻底拥抱了 NotebookLM，谷歌太棒了！这里其实是个针对长文本的 RAG 需求，谷歌的模型能力确实不错，帮我总结书的结构与脉络，找某个特定的内容等等，都体感很好。扫描版的 PDF 我会先走 MinerU 的 OCR 变成 Markdown 文本，再丢到我的 Notebook 里去。我分了两个 Notebook，一个是 Liberal Art 相关，一个是投资相关。读完书会让 AI 生成一些题目来测试我（虽然生成的题目都很一般），然后和书本内容进行互动，增强理解。我尽量第一次阅读的时候不用 AI，除非真的卡住了，在读完之后的复盘才开始使用 AI 的辅助。甚至因为 NotebookLM 很方便，我也基本放弃了原来的笔记方式，放弃了大段的摘录，而转而去记录一些有趣的细节、我自己的元分析与思考等。手机上下了个 NotebookLM 的 App 准备自己没事就去复习复习自己看过的书（虽然其实也没打开过）。</p><p>Obsidian 的知识库那边我有点放弃了，基本上就是作为一个 staging 区域而存在，我最后整理到 Curiosity log 的内容才是我真的感兴趣的内容。原本的知识库作为一个原始素材就先放着了，可能有用的就在于放在云端接个龙虾随时回答我的问题，但需求不是很大。也许未来可能作为某种知识库或者记忆的仓库而存在吧，但记忆这个问题本身就很复杂，所以不多谈。</p><p>看股票的话有在用 Perplexity Finance，看看新闻、股票大盘等等，也确实只限于大概看看，正经的分析肯定去 TradingView 或者自己写代码了。</p><p>Typeless 也不错，需求切入点非常好的小工具。用着很上瘾，就是不太适合在公司用，比较适合我对象这种远程工作的。</p><p>我可能需要一个龙虾一样的东西吗？大概是可能的，但应该不是现在这个形态，再等等吧。现在这个时代的好处就是，等着总有更好的东西会出来的（软件开发进入通缩时代），不行就再自己魔改或者 Vibe 一个嘛。</p><p>What a Wonderful Time To Be Alive!</p>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/03/15/ai_2026_3/</id>
    <link href="https://jsjtxietian.github.io/2026/03/15/ai_2026_3/"/>
    <published>2026-03-15T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>将近半年前我写了 <a href="https://jsjtxietian.space/2025/11/15/ai_2025_11/">我如何使用 AI (2025.11 版) </a>，当时就觉得估计是要过几个月就更新的，这不是正好我玩杀戮尖塔 2 有点丧气了（这种游戏我]]>
    </summary>
    <title>我如何使用 AI (2026.3 版)</title>
    <updated>2026-09-24T07:25:43.274Z</updated>
  </entry>
  <entry>
    <author>
      <name>jsjtxietian</name>
    </author>
    <category term="Curiosity" scheme="https://jsjtxietian.github.io/tags/Curiosity/"/>
    <content>
      <![CDATA[<p>这两周还挺开心&#x2F;躺平，每天下班除了买菜备菜，就是读《追忆似水年华》+ 玩孤山独影。我还是挺接受普鲁斯特的叙事和文风的，节奏不错。目前第一本读完一半，读完就准备去读读《普鲁斯特的空间》，其实之前坐飞机的时候读了点《从荷马到古希腊抒情诗》还没读完。</p><p>孤山独影在写文章之前刚打完（或者说弃坑），嘛，在雪山最顶上水不够了，又懒得回档打，就这样吧，我确实也不是那种追求完美通关的人，vibe 到了就好。</p><p>好友 tracy 写的好文：<a href="https://mp.weixin.qq.com/s/Tkb0JdC-ZMa4HIM8uiGYEA">科普征文 | 光之信使：黑洞照片背后的科学与技术</a>，思考了下 LLM 时代，科普文章的价值是不是有所转移，大概是吧。在知识的整合与参考方面，AI 的效率和广度远超人类，优秀的科普文章应该填补的是“我不知道我不知道”的盲区，激发好奇，起一个“议程设置”的作用，也许如此。</p><p>另外就是，对于人文社科类的书而言，彻底放弃原来那套做笔记&#x2F;摘抄的方法了。有了 NotebookLM 之后，也与时俱进一下，不再大部分时间花在记录原文上，而只记录大概的结构、有趣的细节以及一些元分析等内容。然后手机上可以下个 App 没事和 AI 聊聊这些，不断地去 Recall. </p><hr><ul><li><p><a href="https://amplifying.ai/research/claude-code-picks/report">What Claude Code Actually Chooses</a> 这还挺有意思的，当你让 Claude 选择它要使用的工具&#x2F;技术栈的时候，Claude 会怎么选。不出意外地，<code>Claude Code frequently builds custom solutions rather than recommending third-party tools.</code> 另外就是 AI 确实有自己偏好的技术栈，合理，而且不同的模型偏好差别也不大，有趣。列下模型喜欢的：Vercel, PostgreSQL, Stripe, Tailwind CSS, shadcn&#x2F;ui, pnpm, GitHub Actions, Sentry, Resend, Zustand, plus stack-specific picks like Drizzle (JS) or SQLModel (Python) for ORMs, NextAuth.js (Next.js) for auth, and Vitest (JS) or pytest (Python) for testing.</p></li><li><p>说到 tool 还有这篇也不错，how do you design the tools of your agent?  <a href="https://x.com/trq212/status/2027463795355095314">Lessons from Building Claude Code: Seeing like an Agent</a>. 另外 GPT 5.4 也有 tool search 了。</p></li><li><p>每周都有新的用 AI 重写了 xxx 的故事：<a href="https://blog.cloudflare.com/vinext/">How we rebuilt Next.js with AI in one week</a>，或者这篇 <a href="https://ladybird.org/posts/adopting-rust/">Ladybird adopts Rust, with help from AI</a>，或者 AI 又解决了某个很难的问题，比如限定时间内纯 C 手写 gpt2 推理引擎：<a href="https://x.com/hansonwng/status/2030000810894184808">GPT-5.4 code-golfs GPT-2</a>；连 Knuth 也用上了 <a href="https://cs.stanford.edu/~knuth/papers/claude-cycles.pdf">claude-cycles.dvi</a>，更别提 <a href="https://x.com/SebAaltonen/status/2027847942527127556">Sebastian Aaltonen</a> 了，时代的风确实变了。</p></li><li><p>AI 帮找安全漏洞，<a href="https://www.anthropic.com/news/mozilla-firefox-security">Partnering with Mozilla to improve Firefox’s security</a>，这个观察很有趣，<code>Claude is much better at finding these bugs than it is at exploiting them.</code> </p></li><li><p>AI 时代的 Engineering Culture —— <a href="https://www.cjroth.com/blog/2026-02-18-building-an-elite-engineering-culture">Building An Elite AI Engineering Culture In 2026</a>, AI 时代的面试—— <a href="https://www.tolans.com/relay/how-we-hire-engineers-when-ai-writes-our-code">How We Hire Engineers When AI Writes Our Code</a>.</p></li><li><p>提升 Agent 某些方面的表现，如 <a href="https://arxiv.org/abs/2603.01896">Agentic Code Reasoning</a>；每周也都有对这些工具的<a href="https://www.jmduke.com/posts/five-observations-ai-tools.html">思考</a>: <code>it seems like the logical endpoint is infinite and perfectly abstracted sandboxes with previewing, isolation, and very tight feedback loops.</code> 包括这篇 <a href="https://x.com/Hxlfed14/status/2028116431876116660">Agent Harness is the Real Product </a>，ref 还挺全的。也有对工具的“逆向”，<a href="https://x.com/Kangwook_Lee/status/2028955292025962534">Investigating how Codex context compaction works</a></p></li><li><p>每周也都会看到一些推理加速的文章，<a href="https://x.com/nrehiew_/status/2029591405954531629">FlashAttention4 的 paper</a>；<a href="https://zhuanlan.zhihu.com/p/2010425058682770994">Prefill 太慢？我们快了 3 倍还提升了推理质量</a>，总感觉和 <a href="https://github.com/ggml-org/llama.cpp/pull/9787">llama.vim : plugin for Neovim</a> 里提的有点像，利用 RoPE 的加性原理进行旋转&#x2F;偏移。</p></li><li><p>每周也都有一些反思 AI 编程的帖子，<a href="https://carlkolon.com/2026/02/27/engineering-747-coding-agents/">747s and Coding Agents</a>，讨论认知债务的：<a href="https://margaretstorey.com/blog/2026/02/09/cognitive-debt/">How Generative and Agentic AI Shift Concern from Technical Debt to Cognitive Debt</a>，<a href="https://surfingcomplexity.blog/2026/02/08/nobody-knows-how-the-whole-system-works/">Nobody knows how the whole system works</a>，<a href="https://leodemoura.github.io/blog/2026/02/28/when-ai-writes-the-worlds-software.html">When AI Writes the World’s Software, Who Verifies It?</a></p></li><li><p>也都有关于 long-running agents 的<a href="https://x.com/karpathy/status/2029696850366971921">讨论</a>，online finetuning 还是 memory based techniques，说到 Memory，看到这个项目有趣 <a href="https://github.com/NevaMind-AI/memUBot">memUBot</a>，说到 finetune，<a href="https://x.com/UnslothAI/status/2028845314506150079">Unsloth AI</a>做了 Qwen3.5 的，小模型还是有用的，比如 <a href="https://x.com/stevibe/status/2029126123465130326">OCR</a>，比如 <a href="https://github.com/OminousIndustries/PhoneDriver">PhoneDriver: Android Phone Control With Qwen3-VL</a>。当然最近吃千问的瓜也不错。</p></li><li><p>神奇的 paper，<a href="https://arxiv.org/html/2603.01919v1">Real Money, Fake Models: Deceptive Model Claims in Shadow APIs</a>，讨论不靠谱的第三方 api 如何影响了科研。</p></li><li><p><a href="https://x.com/OfficialLoganK/status/2026510487022625040">Logan Kilpatrick</a>：我们需要更多的算力，The compute bottleneck is massively under appreciated.  I would guess the gap between supply and demand is growing single digit % every day. 联系到这个 <a href="https://www.youtube.com/watch?v=kAIVualeQjM">Inside the Trillion-Dollar AI Buildout</a>，但半导体股价最近跌跌跌。</p></li><li><p><a href="https://zhuanlan.zhihu.com/p/2012213279079019611">借助语义抽象层和 Agent 编排器在 UE 工程中实现工程生产可用的 Vibe Engineering</a>，MCP 确实不行，这种思路也许可行。</p></li><li><p><a href="https://github.com/halby24/RenderDocMCP">RenderDocMCP</a>，马上用上，另外也许可以直接把 renderdoc 接进游戏里算了，那个 app 总被系统杀。</p></li><li><p>好不容易读一篇 old fashion 的技术文章，<a href="https://devblogs.microsoft.com/cppblog/c-performance-improvements-in-msvc-build-tools-v14-51/#new-ssa-loop-optimizer">C++ Performance Improvements in MSVC Build Tools v14.51</a></p></li><li><p>这个工具不错，<a href="https://github.com/kevingosse/ClipPing">ClipPing: Displays a visual notification in the active window when the clipboard is updated</a>，我一直觉得是 Win 系统的 bug</p></li><li><p><a href="https://www.zhihu.com/question/37896333/answer/1991160339182683668">统计学里有哪些振聋发聩颠覆三观的证明和定理</a>，虽然是 AI，但说的几个都不错，另外也一直想读下《概率论沉思录》。</p></li><li><p>我也是用上 Windows Codex App 了，体验目前还不错，别人问 Codex 是不是 100% AI 写的，回：<a href="https://x.com/thsottiaux/status/2030141318782144546">Not yet, and that’s why it works extremely well</a>.</p></li><li><p>上次的 MinerU 魔改失败了，还是模型原因，<a href="https://github.com/PaddlePaddle/PaddleOCR/blob/main/readme/README_cn.md">PaddleOCR</a> 的排版也不行，不过我后面发现其实我直接读英文更快，也只是玩玩能不呢识别繁体 + 正确排版。</p></li><li><p>总体来说能给新 Insights 的文章确实少了，唉，主要最近在休息模式没啥 Build 的兴致，也是工作变忙所致。</p></li></ul>]]>
    </content>
    <id>https://jsjtxietian.github.io/2026/03/07/curiosity_log_5/</id>
    <link href="https://jsjtxietian.github.io/2026/03/07/curiosity_log_5/"/>
    <published>2026-03-07T00:00:00.000Z</published>
    <summary>
      <![CDATA[<p>这两周还挺开心&#x2F;躺平，每天下班除了买菜备菜，就是读《追忆似水年华》+ 玩孤山独影。我还是挺接受普鲁斯特的叙事和文风的，节奏不错。目前第一本读完一半，读完就准备去读读《普鲁斯特的空间》，其实之前坐飞机的时候读了点《从荷马到古希腊抒情诗》还没读完。</p>
<p>孤山]]>
    </summary>
    <title>Curiosity Log 5</title>
    <updated>2026-09-24T07:25:43.275Z</updated>
  </entry>
</feed>
